 Addy Crezee
a good Seedance prompt reads like a shot list, not a description: name the subject exactly, give every beat a camera move, tell each reference what it controls, describe the sound, and end with what must never change. Seedance 2.5 takes text, images, video and audio together and makes clips of 4 to 30 seconds. the best prompt we have run is not ours: it's a Chinese product-ad template that we reuse by changing three slots. below: what the model accepts, the rules for writing prompts, that template in full with the video it gave us, 12 mistakes that cost us generations, a table of short modifiers, and community prompts worth a look. facts checked September 27, 2026.
what seedance 2.5 accepts: inputs and modes
Seedance 2.5 is ByteDance's video model, announced on July 31, 2026; Seedance 2.0 came out on February 12. both generate picture and sound in one pass. per the BytePlus ModelArk documentation, one request can run in these modes:
| mode | what you give it | what it's for |
|---|---|---|
| text-to-video | a prompt only | anything you can describe |
| first frame | one image + prompt | your image is frame one, the model animates it |
| first and last frame | two images + prompt | the model fills the motion between them |
| multi-reference | images, videos and audio + prompt | characters, products, a camera move or a rhythm taken from references |
| video editing | a video + prompt | change something in an existing clip |
| video extension | a video + prompt | continue a clip |
the limits that shape a prompt:
| Seedance 2.5 | Seedance 2.0 | |
|---|---|---|
| clip length | 4–30 seconds, whole seconds, or "auto" | 4–15 seconds, or "auto" |
| references | up to 30 images, 10 videos, 10 audio files (Replicate) | up to 9 images, 3 videos, 3 audio clips (ByteDance); on fal no more than 12 files in total |
| resolution | 480p, 720p, 1080p (ModelArk, fal) | 480p, 720p, 1080p, 4K (fal) |
| aspect ratio | 16:9, 4:3, 1:1, 3:4, 9:16, 21:9, adaptive | |
| sound | dialogue with lip-sync, effects, music; can be switched off | the same |
| timestamps in the prompt | understood, in whole seconds | not understood – use "Shot 1, Shot 2" |
| prompt length | recommended: up to 1,000 English words or 500 Chinese characters |
a few things the table hides:
- 4K on 2.5 depends on the host. ModelArk and fal list 480p to 1080p for 2.5; WaveSpeed's endpoint offers a 4K option. we haven't checked whether that's native generation or upscaling.
- the prompt limit is a recommendation. the BytePlus API docs give a recommended length; we didn't find a published hard cap. our prompt below is 953 words and ran without errors. Dreamina additionally recommends keeping it concise: "Use the shortest prompt that fully specifies the production."
- reference syntax depends on the platform. BytePlus writes
@Image 1,@Video 1,@Audio 1; Replicate uses[Image1]; Dreamina shows@Image1. use the labels your interface inserts. - real faces can't be uploaded directly. BytePlus: "Seedance 2.5 and Seedance 2.0 series models do not support directly uploading reference images/videos that contain real human faces." verified people go through a separate private asset library.
- editing and first-frame modes keep the source aspect ratio, and editing keeps roughly the source length.
how to write a seedance prompt: the rules
BytePlus's prompt guide for 2.5 suggests one skeleton: subject + location + event + genre/style + camera movement. that's the minimum. the prompts that worked for us, and the popular community prompts below, add sound, references with jobs, and locks. here is what to write for what – our recommendations, based on our runs and the official guides.
what goes where
| part | write | why |
|---|---|---|
| look | the look in a few words + "throughout", near the top | the look applies to every shot, not just the first |
| subject | exactly what it is, with 2–3 visible details; the brand name spelled once | vague subjects get a generic stand-in; our unnamed brand became the category word |
| references | one job per reference: "@Image 1 is the product: label and cap only", "@Video 1 is the camera move only" | a reference with no job can pull in everything – colours, background, framing |
| beats | one action per line, in order; in 2.5 with timestamps (0–4s), in 2.0 as Shot 1, Shot 2 |
the model follows sequences better than paragraphs |
| camera | a verb for each beat: push-in, whip pan, orbit, tracking | if you don't say how the camera moves, the model decides |
| cuts | "hard cut", "match cut", "white flash" only where the place or scale changes | a cut inside one location made the model rebuild our scene |
| sound | what you hear, beat by beat, or "no music" | sound is on by default; unspecified, the model picks it |
| ending | the last frame as a picture: "the product lands in the centre, freeze frame" | a named final frame gives the clip a clear end |
| locks, last | what must never change, what must never appear | "never distorted", "no real human faces", "no watermark" |
how to ask for a style
a style word works best when it names something a camera or a film stock physically does. "Cinematic" or "beautiful" is vague; add the concrete details behind it. ways to get a specific look:
| you want | write | example source |
|---|---|---|
| a phone video that looks real | vertical phone footage, rolling shutter, autofocus hunting, auto-exposure shifts, micro jitter | community realism block (Sourcecode12, Reddit) |
| a home video from the 2000s | Mini DV camcorder, occasional focus hunting, "Hand covers lens as recording ends." | community prompt (Strength04_X, X) |
| film | 35mm film grain, light leaks, film gate flicker, dust and scratches | our ad template; Higgsfield library |
| a music video | whip pans, speed ramps, strobe, datamosh, chromatic aberration | our ad template |
| a premium product ad | macro close-up, hard rim light, black void, slow push-in | fal product prompt; our template |
| comics or print | pop art, halftone shading, bold ink outlines | Krea's Seedance example |
| an eyewitness clip of something huge | phone footage + an impossible event, slight handheld shake | community prompt (mhu99, Reddit) |
three rules that hold across styles:
- say "throughout". the look should hold across every shot, not only the first. (Dreamina's own guide leads with the subject; the look can come right after it.)
- mix looks on purpose, not by accident. our ad template deliberately asks for an "analog-digital hybrid aesthetic". what breaks is a contradiction, like "locked-off camera" and "strong handheld shake throughout". BytePlus's advice: resolve any conflict between the prompt and the references.
- change one thing per run. Dreamina's guide says the same: when a result is off, change one variable, not five.
for text prompts in general – task, context, limits, format – see our guide on how to write AI prompts. video adds time, camera and sound on top.
the prompt we ran: a product hype ad in 51 paragraphs
where the template came from
the template is a Chinese prompt for a "high-energy streetwear ad cut like an experimental music video". we didn't write it and don't know its original author; it reached us as a finished prompt. on August 28, 2026 we ran it for a coffee brand, SEREBRYAKOV: image-to-video, two reference images (the bag and the beans).
- as is, no edits: a 10-second clip with 8 of the 10 scenes the prompt describes, and the logo held.
- with three slots filled in: 12 seconds, 9 scenes, beans bursting out of the bag as it comes apart, the brand spelled right everywhere.
then we tried to improve it. we rewrote it in English, added a second product, swapped in generic equipment, wrote timings for every beat, added more locks. every version came out worse. the lesson we wrote down that day: don't rewrite a prompt that works, change only the slots.
why it works, as far as we can tell: the product rule opens the prompt and comes back in the closing constraints; most scene changes are named with an editing cue (hard cut, white flash, match cut, whip pan), so the model gets a sequence, not a mood; there's one climax with a reversal (the product explodes, then snaps back); typography, colour and sound each get their own block; and it only asks for what image-to-video does well – macro, a hero shot in a void, glitch, type, an exploded view.
the three slots
everything else stays word for word. only these change:
| slot | what you put in | why |
|---|---|---|
| the product line | brand, what the product is, 2–3 visible details, the brand name spelled once | without it the model writes the category ("COFFEE") in every title |
| the zoom target | one detail – the logo, a label, a seam | the original lists "logo, badge, seam, sole, buckle, cap…", and the model picks at random |
| the explosion | what the product is really made of, plus matching sounds | the generic list ("panels, fabric, hardware, soles, laces") took our coffee bag apart into paper and burlap |
the english test
the coffee lesson said English rewrites lose quality. but a rewrite changes the words and the content. this time we tested the other half: a full paragraph-for-paragraph English translation – 51 paragraphs in, 51 out – with nothing added or cut except the three slots. (One word slipped in translation: the chrome lettering "gradually" forms in the original; in ours it just morphs.) the product is a demo hoodie with the thehype wordmark (our merch mock-up, not something on sale), from one reference image.
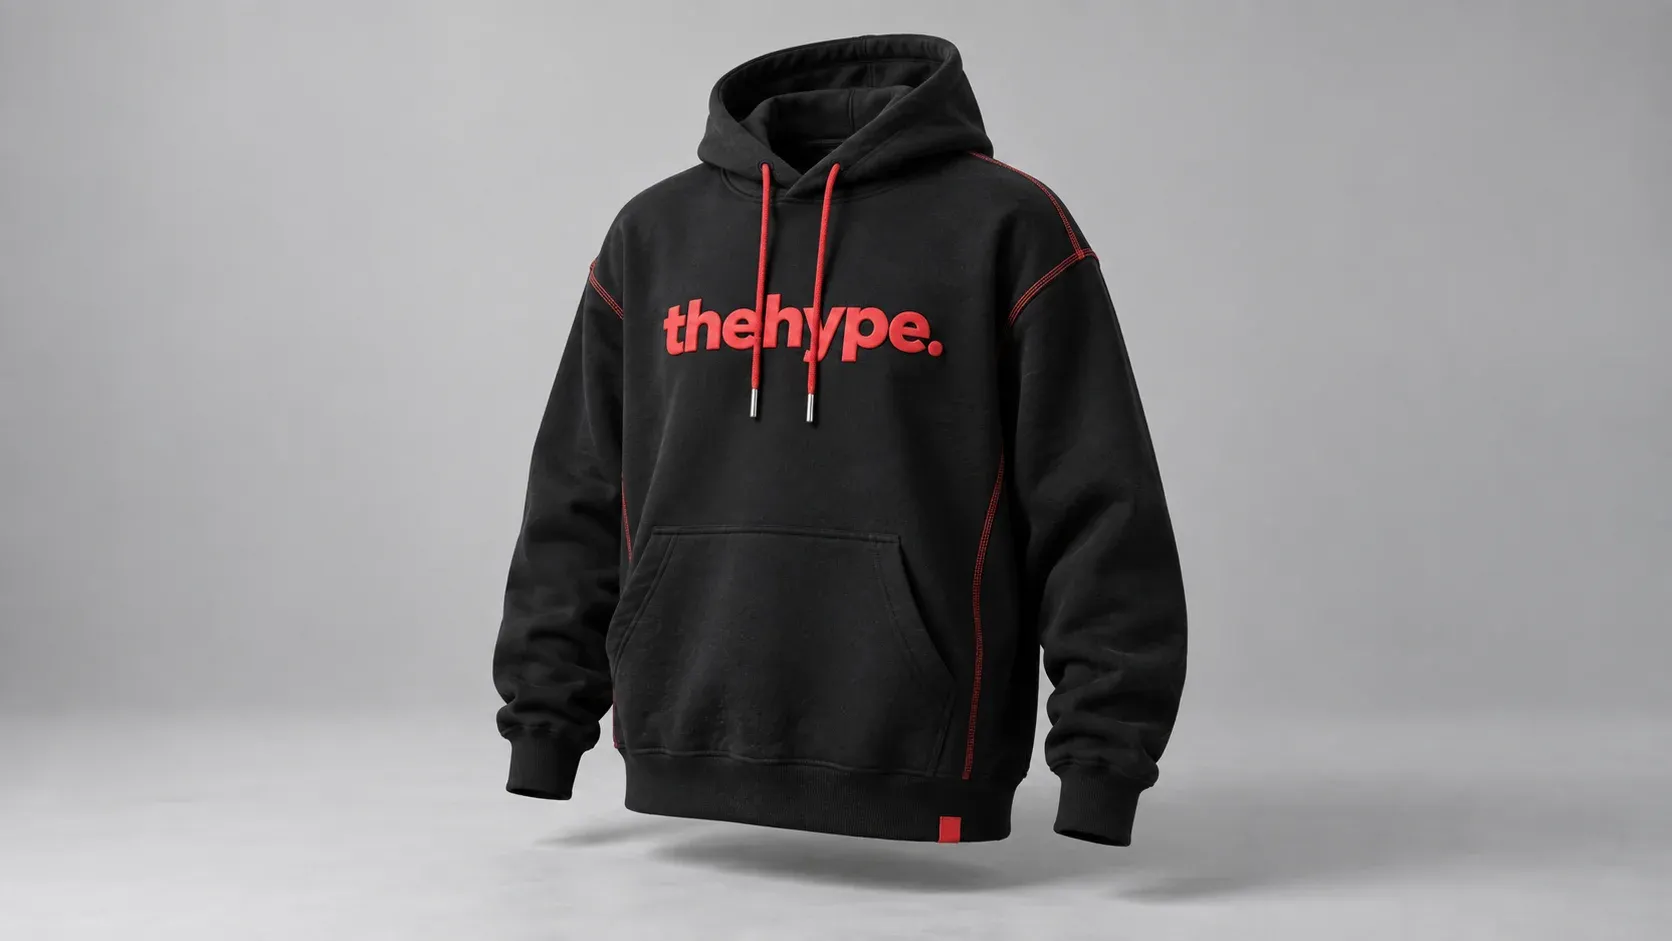
settings: image-to-video with the photo as a reference, 12 seconds, 16:9, sound on. the clip doesn't open on the photo – it opens on a macro of the seam, as the prompt asks. the full prompt, 6,393 characters and 953 words:
An ultra-dynamic, highly trend-driven social media commercial built around the product shown in the input image. The product is a thehype black heavyweight oversized hoodie (red lowercase "thehype." wordmark in raised puff-print across the chest, red contrast flatlock stitching on the shoulder and side seams, red flat drawstrings with brushed-metal aglets, a small blank red woven label on the hem, ribbed cuffs and hem). The brand name is "thehype." – all lowercase letters, one word ending with a period, no hyphens and no spaces, and the period is always visible; every typography animation and the final stamp use this name, never "HOODIE" or any other generic word. The subject, brand identity, logo and overall color palette all come directly from the uploaded image – every single scene must use exactly the same product, and the product's design, materials, texture, logo, proportions and details stay absolutely consistent throughout the entire video.

The energy of high-end fashion streetwear, combined with the editing style of an experimental music video. Analog-digital hybrid aesthetic: crisp, sharp product texture combined with 35mm vintage film grain, dust, scratches, light leaks and film gate flicker.

The rhythm is extremely intense, high-speed editing throughout, never a static shot – the camera keeps moving until the very last frame.

Opening:

An extreme macro close-up of the product's finest surface – texture, stitching, engraving, weave structure or material grain. Distorted light and reflections slide across the surface. Handheld camera with obvious shake and strong motion blur.

A sudden white flash transition; kinetic typography slams in violently, letter by letter. The letters stretch, jitter and split into RGB chromatic aberration.

Hard cut:

A high-speed whip pan into a low-angle upward hero shot of the product. The product floats in a black void, lit by harsh black-and-white strobe lights. The frame shakes constantly, with datamosh data-corruption effects and horizontal scan-line tearing.

Then an ultra-high-speed zoom:

The camera rushes instantly from a wide shot to the product's most iconic detail – the red raised puff-print lowercase "thehype." wordmark on the chest, including the period.

One extreme speed ramp completes the push from a long shot to an extreme close-up, dropping suddenly from ultra-high speed into extreme slow motion at the moment of impact. Motion blur forms light trails, while five ghosting product-clone trails drag behind the path of motion.

A match cut on the product's main silhouette instantly turns into a high-speed FPV drone orbit. The camera tilts to a Dutch angle and rotates aggressively. Film grain suddenly intensifies, the image briefly inverts into a negative, then instantly returns to normal.

The frame shatters into a layered 2.5D parallax collage:

Cut-out images of the product in different sizes slide at different spatial depths. Add torn-paper edges, halftone textures, hand-drawn doodle annotations and bold stamp-style lettering. The layers gradually separate and float in three-dimensional space.

Product explosion:

The product bursts apart in ultra slow motion into its real components – front and back body panels, both sleeves, the hood, the kangaroo pocket, ribbed cuffs and hem band, the red flatlock stitching threads unravelling from the seams, the red drawstrings with their brushed-metal aglets, the small red woven hem label, and the raised puff-print "thehype." wordmark peeling off the chest as one intact rubbery layer.

All parts float in the air, forming an exploded-view product constellation. A handheld camera circles slowly and unsteadily between the pieces, producing overlapping echo trails.

Then time reverses, and all parts slam back together in a high-speed speed ramp, precisely restoring the complete product.

The reassembled product morphs like liquid into huge chrome brand-name lettering. The letters wobble like liquid metal, the whole frame is stretched horizontally like taffy, then instantly snaps back into place.

Then a strobe montage:

Product images switch at near-subliminal flash speed – the product displayed on a chrome mannequin silhouette, paparazzi-style photography under harsh direct flash, frozen mid-spin, negative-color frames, glitch-corrupted frames, VHS tracking errors.

All shots are connected by high-speed whip pans and white flash transitions.

Finale:

A sudden hard cut to a black screen.

One last intense flash.

The product then lands precisely in the center of the frame, ending on an ultra-sharp still freeze frame. The film grain still breathes slightly. The brand name stamps in with a strong impact animation and holds until the end of the video.

Typography:

Extra-large bold condensed sans-serif type throughout, combined with distressed typewriter-style text overlays.

Text animations include:

Violent pop-ins, per-letter jitter, rapid letter-spacing expansion, wave distortion, fast position glitches, brief displacements.

Use short, punchy words that fit the brand's character.

Color:

A high-contrast, low-saturation base palette, with neon accents taken from or harmonizing with the product's own brand colors.

Strong vintage film grain, dust, hair-like film defects, light leaks, film sprocket-hole edges, chromatic aberration in fast motion, VHS wobble during glitches, deliberate exposure instability and lens breathing.

Sound design:

Sound design only, no music.

A low-frequency impact on every cut.

A whoosh on every whip pan.

A camera shutter sound on every strobe.

The product explosion and reassembly use sounds that match the real materials – heavy cotton fleece stretching and tearing apart, stitching threads snapping, the rubbery puff-print peeling off, drawstrings whipping through the air, metal aglets clicking – they must match the product's actual materials.

A tape-stop effect on every speed ramp.

Static crackle on glitch frames.

Rising air tension before the logo appears.

Then complete silence, ending on one final intense impact sound.

Core constraints:

The product's design, logo, proportions, materials and all key details must never be distorted, altered or warped at any point in the video.

No real human faces – only human silhouettes or chrome mannequins.

No smooth stabilizer shots.

No calm or slow passages before the ending.

No watermark.

No music.
the Chinese original, for anyone who wants to run it as is. replace the zoom list and the explosion list with your product's real parts, and add a line naming your brand:
超高动感、极具潮流感的社交媒体商业广告,围绕输入图片中所展示的产品展开。主体、品牌识别、Logo 和整体配色均直接来源于上传的图片——每一个场景都必须使用完全相同的产品,产品的设计、材质、纹理、Logo、比例和细节在整个视频中始终保持绝对一致。

高端时尚街头服饰的能量感,结合实验性音乐录像带的剪辑风格。模拟数字混合美学:清晰锐利的产品质感与 35mm 复古胶片颗粒、灰尘、划痕、漏光和胶片门闪烁相结合。

节奏极其激烈,全程高速剪辑,绝不出现静止镜头——直到最后一帧之前,摄影机始终保持运动。

开场:

以产品最精细的表面进行极致微距特写——纹理、缝线、雕刻、编织结构或材质颗粒。扭曲的光影和反射在表面滑动。手持摄影带有明显抖动和强烈运动模糊。

突然闪白转场,动态字体逐字猛烈出现。字母拉伸、抖动,并产生 RGB 色差分离效果。

硬切:

高速甩镜进入低机位仰拍的产品英雄镜头。产品悬浮在黑色虚空中,由强烈的黑白频闪灯照亮。画面不断抖动,并出现 datamosh 数据损坏效果和水平扫描线撕裂。

随后进行超高速变焦:

摄影机从广角瞬间冲向产品最具标志性的细节——Logo、徽章、接缝、鞋底、扣件、瓶盖或任何能够定义该产品的核心细节。

一次极速变速运动完成从远景到极端特写的推进,在撞击瞬间从超高速突然坠入极慢动作。运动模糊形成光轨,同时出现五个带有残影的产品克隆轨迹,拖曳在运动路径之后。

产品的主体轮廓进行 Match Cut,瞬间转换成高速 FPV 无人机环绕镜头。镜头以荷兰角倾斜并进行激进旋转。胶片颗粒突然增强,画面短暂反转成负片效果,然后瞬间恢复正常。

画面碎裂成分层 2.5D 视差拼贴:

产品的剪裁图像以不同尺寸分布在不同空间深度中滑动。加入撕纸边缘、半色调纹理、手绘涂鸦标注和醒目的印章式字体。各个图层在三维空间中逐渐分离并漂浮。

产品爆炸:

产品以超慢动作爆裂成其真实组成部件——面板、结构层、织物、五金件、鞋底、鞋带、瓶盖或其实际构成的其他部件。

所有零件悬浮在空中,形成一个爆炸视图式的产品星座。手持摄影机在碎片之间缓慢而不稳定地环绕,并产生重叠的回声残影。

随后时间反转,所有零件在高速变速中猛烈地重新组合,精准恢复成完整产品。

重新组装后的产品进行液态变形,逐渐变成巨大的铬金属品牌名称字体。字母像液态金属一样晃动,整个画面像太妃糖一样被水平拉伸,然后瞬间恢复原位。

随后进入频闪蒙太奇:

以近乎潜意识闪现的速度连续切换产品画面——产品被展示在镀铬人体模型轮廓上、强烈直闪灯下的狗仔队摄影风格、旋转过程中定格、负片色彩画面、故障腐蚀画面、VHS 跟踪错误。

所有画面通过高速甩镜和闪白转场连接。

最终:

突然硬切至黑屏。

最后一次强烈闪光。

产品随后精准落在画面中央,以极致锐利的静态定格画面结束。胶片颗粒仍在轻微呼吸。品牌名称以强烈的冲击动画盖印出现,并保持到视频结束。

字体设计:

全程使用超大号粗体窄体无衬线字体,结合做旧打字机风格文字叠加。

文字动画包括:

猛烈弹入、逐字抖动、字距快速扩张、波浪变形、快速位置故障、短暂位移。

使用简短、有冲击力、符合品牌气质的词语。

色彩:

以高对比度、低饱和度的基础色调为主,并加入从产品自身品牌色彩中提取或与其协调的霓虹色点缀。

强烈复古胶片颗粒、灰尘、毛发状胶片瑕疵、漏光、胶片齿孔边缘、快速运动中的色差、故障时的 VHS 摇摆、刻意的曝光不稳定以及镜头呼吸效果。

声音设计:

仅使用声音设计,不使用音乐。

每一次剪辑加入低频冲击。

甩镜加入呼啸声。

频闪加入相机快门声。

产品爆炸与重新组装使用符合真实材质的声音——织物拉扯声、金属碰撞声、塑料卡扣声等,必须与产品实际材质匹配。

变速加入磁带停止音效。

故障画面加入静电爆裂声。

Logo 出现前加入空气张力逐渐上升的声音。

随后完全静音,并以最后一次强烈冲击音结束。

核心约束:

产品的设计、Logo、比例、材质和所有关键细节在整个视频中绝不能扭曲、改变或失真。

禁止出现真实人脸——只能使用人物剪影或镀铬人体模型。

禁止平滑稳定器镜头。

禁止在结尾之前出现平静或缓慢的段落。

禁止水印。

禁止音乐。
what came out
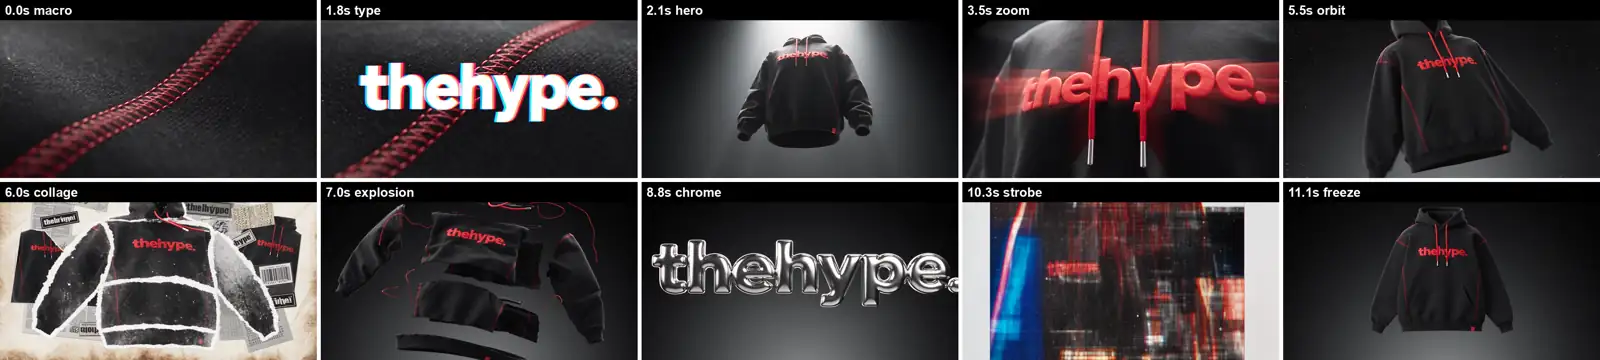
a 12-second clip, 1080p, 24 frames per second. all ten scenes the prompt describes are there, in order:
| time | scene in the prompt | what we got |
|---|---|---|
| 0–1.7s | extreme macro, handheld | the red flatlock seam in sharp detail; the camera drifts slowly, with little of the requested shake |
| 1.75–2s | kinetic type with RGB split | "thehype." slams in over the macro with a colour split – the whole word at once, not letter by letter |
| 2.1–3.3s | hero shot in a black void | hard cut to the hoodie floating under a harsh top light, with horizontal scan-line tearing |
| 3.5–5.4s | speed-ramp zoom to the wordmark | a push into the chest print with red ghost trails; the period survives |
| 5.5–5.9s | match cut, FPV orbit, Dutch angle, negative flash | compressed into half a second: a dark wipe, one bright flash frame, a tilted, turning hoodie |
| 6–6.8s | 2.5d paper collage | torn-paper cut-outs, newspaper clippings and a barcode on an aged-paper background |
| 7–8.6s | exploded view, then reverse | hood, body, sleeves, pocket, hem band, drawstrings and red threads drift apart; the reassembly lasts about 0.2 seconds |
| 8.75–10.1s | liquid chrome lettering | chrome "thehype." with the period; the first frames are hard to read before it settles |
| 10.25–11s | strobe montage | a glitch frame, a chrome mannequin, a white studio shot, one frame where the hoodie flashes light grey |
| 11.1–12s | landing in the centre, freeze frame | the hoodie centred and still |
what it skipped or got wrong:
- no final brand stamp and no cut to black. the clip ends on the product without the logo stamping in – the last instruction of the finale.
- the wordmark didn't peel off as its own layer. it stayed printed on the chest panel during the explosion.
- invented text in the collage. the newspaper cut-outs carry garbled pseudo-words next to the real wordmark. secondary text is still where the model makes things up.
- the explosion is closer to the product, but not complete. naming the real parts gave recognisable garment sections – hood, body, sleeves, pocket, hem band – plus loose red threads and drawstrings. the cuffs stayed on the sleeves and the label stayed on the hem.
the sound kept to the "no music" rule: no music and no speech, as the prompt asks.
the verdict on English. with the three slots filled in, the Chinese coffee run gave 9 of 10 scenes in 12 seconds; the English hoodie run gave 10 of 10 in 12 seconds, and the main titles resolve to "thehype.". that's one run each, with different products and references, so it's not a controlled A/B. our hypothesis: what hurt us in August wasn't English itself but changing the content while translating, and keeping the structure is what helped here. these two runs can't prove why.
12 mistakes that cost us generations, and what to do instead
every one of these happened to us in Seedance 2.0 or 2.5 between July and September 2026. each fix is our suggestion from that experience; where we tried it, we say what happened.
- we rewrote a prompt that worked. coffee ad, August 28: English, a second product, timings, locks – each version worse than the original. fix: change only the slots, keep the rest word for word.
- a brand spelled with hyphens came out with hyphens. we wrote the letters one by one,
E-R-E-B-R-Y-A-K-O-V, to help the model, and it rendered "SE-REBRYAKOB". fix: write the name once, as one word, and add "no hyphens, no gaps". - a Latin letter turned Cyrillic. in a Russian surname the final Latin V became the Cyrillic "В". fix: "Latin alphabet only, the last letter is a Latin V".
- a hard cut inside one location made the model rebuild the scene. the letter S "fell" twice and the bag moved to a new spot. fix: shoot linked beats as one continuous camera move; cut only when the location or scale changes.
- a generic parts list took the product apart wrong. "panels, fabric, hardware" turned a coffee bag into paper and burlap. fix: list the real layers – matte film, foil, valve, zip – and what's inside.
- the model wrote the category instead of the brand. titles said "COFFEE". fix: one line that names the brand and forbids the generic word.
- a reference range broke the parser. in Seedance 2.5
@image4-@image9threw an error (August 28, a different clip). fix: list them one by one,@image4, @image5, @image6. - the start frame showed the result, not the action. on July 29 all ten inserts for our weekly video started after the event – the lid already torn off – so there was nothing left to animate. fix: draw the first frame mid-action, with room for the motion to go.
- a prop vanished. "he strokes the cat" – but both hands held a fishing rod, so the rod disappeared. fix: before generating, check what is in each hand on every beat.
- moderation rejected cartoon references. on July 8 Seedance 2.0 rejected caricatures of footballers: "The reference image was rejected by provider moderation. not retryable." a cartoon style doesn't help if the face and kit are recognisable. fix: remove the recognisable features from the reference, or use another model.
- "handheld" was ignored. handheld, snap zoom and run-and-gun all came out near-static in our July tests – three wordings, same result. fix: put the shake on top of a clear camera move (pull-back, tracking), or add it in the edit.
- "room tone" added noise. in a quiet cat shot on September 23 it gave a background hum. fix: "pure silence, one soft meow". and describe the sound you want: sound is on by default, and otherwise the choice is left to the model.
one thing we haven't isolated: whether beat timings help or hurt the ad template. we added them only together with other changes, never in a clean A/B.
short modifiers: what each one is meant to do in the frame
short words and phrases that change a clip a lot. the effect column is the intended effect, not a guarantee. the "source" column shows where the term is documented or demonstrated: Dreamina (ByteDance's own guide and examples), platform (a hosting service's Seedance guide), Runway (another video vendor's camera glossary, not Seedance-specific), community (a shared prompt) or ad template (appears in the template above). the last column is ours: in our run means the word is in the ad template we generated with; tested means we checked that specific word.
camera
| word | what it does in the frame | source | us |
|---|---|---|---|
| push-in | the camera moves closer, the subject grows | Dreamina | |
| pull back | reveals more of the scene | Dreamina | |
| tracking | follows a moving subject | Dreamina | |
| pan | turns sideways across a scene | Dreamina | |
| orbit | circles the subject, showing different sides | platform | in our run (FPV orbit) |
| crane up | rises for a reveal | platform | |
| truck left / right | slides sideways | platform | |
| whip pan | a fast sideways sweep with motion blur | Runway | in our run |
| FPV drone | a fast, swooping first-person flight | ad template | in our run |
| handheld | human-held instability | Dreamina | tested: came out near-static |
| snap zoom | a sudden fast zoom | – | tested: ignored |
| low angle | looks up, the subject feels big | Runway | in our run |
| Dutch angle | a tilted horizon, unease | ad template | in our run |
| aerial | from high above | Runway | |
| over-the-shoulder | the action framed past someone's shoulder | Dreamina | |
| single continuous shot | no cuts | Dreamina |
framing and focus
| word | what it does in the frame | source | us |
|---|---|---|---|
| wide shot | the subject and plenty of surroundings | Dreamina | |
| medium shot | waist up, body language | Dreamina | |
| close-up | a face, object or detail fills the frame | Dreamina | |
| extreme macro | surface texture, stitching, grain | ad template | in our run |
| rack focus | sharpness jumps from one plane to another | Runway | |
| deep focus | foreground and background both sharp | Runway | |
| soft focus | a softened, hazy image | Runway | |
| focus hunting | sharpness searches and settles, like an autofocus camera | community |
time and editing
| word | what it does in the frame | source | us |
|---|---|---|---|
| slow motion | stretches an action | Dreamina | |
| speed ramp | speed changes within a shot, faster or slower | Dreamina | in our run |
| time-lapse | a slow process compressed | Dreamina | |
| jump cuts | skips between moments | Dreamina | |
| hard cut | an instant switch to a new shot | ad template | in our run |
| match cut | a shape in one shot becomes the same shape in the next | ad template | in our run |
| white flash | a flash-to-white transition | ad template | in our run |
| freeze frame | the image stops dead | ad template | in our run |
| strobe montage | near-subliminal flashes of different shots | ad template | in our run |
look and film
| word | what it does in the frame | source | us |
|---|---|---|---|
| 35mm film grain | visible grain, a photographed feel | platform | in our run |
| light leaks | warm washes of light at the edges | ad template | in our run |
| chromatic aberration | colour fringes on edges, often in fast motion | platform | in our run |
| datamosh | frames smear into each other like broken video compression | ad template | in our run |
| VHS tracking error | wobbling lines and colour bleed of old tape | ad template | in our run |
| Mini DV camcorder | soft consumer video with imperfections | community | |
| auto-exposure shifts | brightness jumps as the camera adjusts | community | |
| hard rim light | a sharp line of light around the subject | platform | |
| cyberpunk | neon, futuristic city styling | Dreamina | |
| pop art | bold graphic, comic-like styling | platform | |
| halftone shading | printed-dot shadows | platform | |
| bold ink outlines | strong drawn contours | platform |
"in our run" means the word is in the prompt we generated with. in the hoodie clip we could clearly see the macro, the hard cut, the ghost trails of the zoom, the Dutch angle, the chrome lettering, the scan-line glitch, the strobe montage and the freeze frame; we couldn't pick out the speed ramp or the datamosh as distinct effects.
community seedance prompts worth a look
we haven't tested these ourselves. these are selected community prompts and platform examples; where a page showed likes, we list them. prompts are the authors' work, so we credit them and retell the longer ones by structure with short quotes. popularity is what the page showed on September 27, 2026. for the first four, likes are as shown by the GoodCase gallery, which reposts X prompts; we couldn't open the original X posts to confirm them.
| # | what the clip shows | author | date | popularity | model, mode |
|---|---|---|---|---|---|
| 1 | a summer night in Seoul as a home video | AIwithkhan (X) | Aug 27, 2026 | 6.4k likes | 2.5, text only |
| 2 | time freezes over a spill in a 1950s diner, then rewinds | techhalla (X) | Aug 1, 2026 | 2.8k likes | 2.5 |
| 3 | a two-idol K-pop music video | just_sharon7 (X) | Aug 1, 2026 | 1.4k likes | 2.5 |
| 4 | an espresso ASMR vlog on Mini DV | Strength04_X (X) | Jul 31, 2026 | 917 likes | 2.5 |
| 5 | a passenger jet turns into a giant robot, filmed on a phone | mhu99 (r/singularity) | about Feb 2026 | not shown | 2.0 |
| 6 | an elf fights a monster, from a 3×3 storyboard image | isoundwaveisuperior (r/Seedance_AI) | about Apr 2026 | not shown | 2.0, one image |
| 7 | a tokusatsu heroine transformation | AIwithSarah_ (X), reposted by zeroludesigner | about May 2026 | not shown | 2.0, image reference |
| 8 | a style block for "accidental" phone footage | Sourcecode12 (r/ChatGPT) | about May 2026 | not shown | 2.0 |
| 9 | a girl eating a burger turns into a creature, eats a zombie, then goes back to lunch | Rus Syzdykov (Higgsfield) | Apr 13, 2026 | not shown | 2.0, 4 images |
| 10 | a grapefruit soda can hero shot | John Ozuysal (fal) | Jun 18, 2026 | not shown | 2.0, text only |
| 11 | a skincare serum brand film | Sameer Sohail (OpenArt) | Aug 10, 2026 | not shown | 2.5, product photo + style video |
| 12 | a 15-second biscuit commercial | @Itswsm105f (X, via imagineVid on GitHub) | Jul 18, 2026 | not shown | 2.0 |
what's worth taking from them:
- Seoul home video (1). length and "no references" first, then the subject with a consistency note, the neighbourhood, a consumer camera's defects ("Strong handheld shake", "autofocus hunting"), and six ordinary beats: leaving home, buying a pastry, meeting a cat, leaves falling into her hair, a rest, the walk back. realism comes from the camera's flaws, not from cinematic moves.
- frozen diner (2). Timestamped acts: calm setup (0–4s), the collision and frozen spill (4–8s), an orbit and rewind (8–17s), stopping the accident (17–24s), a knowing close-up (24–30s). it separates the one person who moves from a world that doesn't: "Time locks completely at the peak of the spill".
- K-pop MV (3). Timestamped shots alternating group choreography, solos, close-ups and a mirrored double, with two recurring sets – a pink studio and a blue stage – to keep fast cuts coherent. it asks for natural weight shifts and realistic cloth.
- Mini DV espresso (4). Labelled blocks – CAMERA/LOOK, STYLE, SUBJECT, SETTING, ten three-second beats, AUDIO NOTES, REALISM NOTES – following the real steps of making coffee and ending with "Hand covers lens as recording ends."
- storyboard grid (6). the whole video prompt is one line: "Use (at)image1 to create a 15s cinematic fantasy animation." the work is in the image: a 3×3 storyboard made first in an image model.
- serum film (11). the most useful habit here: each reference gets a limited job – the product photo controls "the label, and the cap only", the style video controls pacing and colour.
- biscuit ad (12). a classic 15-second structure: product (0–3s), slow-motion break (3–6s), dipping into chai (6–10s), rotating pack (10–13s), family payoff (13–15s).
more collections: the awesome-seedance and imagineVid repositories on GitHub, and the prompt galleries on Higgsfield and fal.
where to use seedance 2.5 and what it costs
Seedance 2.5 is on BytePlus ModelArk (model ID dreamina-seedance-2-5-260628), in Dreamina, in ByteDance's Jimeng AI and Doubao Pro, and on third-party platforms: fal, Replicate, Higgsfield, Krea, Kie.ai, Runware and WaveSpeed. magnific (formerly Freepik) lists it as coming soon. Dreamina first rolled 2.5 out to subscribers over 16 in Europe, Asia, the Middle East and South America; its current offers also cover the US.
approximate prices per second of output, 16:9, without video input, as listed on September 27, 2026:
| where | 480p | 720p | 1080p |
|---|---|---|---|
| BytePlus ModelArk (example estimate) | $0.103 | $0.231 | $0.569 |
| Runware | $0.1025 | $0.2304 | $0.6135 |
| WaveSpeed | $0.18 | $0.36 | $0.90 |
| fal | $0.2205 | $0.473 | $1.164 |
ModelArk and fal actually bill by tokens, so the per-second numbers are estimates, and the final charge on each platform is what counts; clips with video input are cheaper per token but count the input length too. for how Seedance 2.5 compares with other video models, see our Seedance 2.5 vs Minimax H3, Grok Imagine 1.5 and Gemini Omni comparison and the Time100 AI red carpet result, where HappyHorse 1.1 beat Seedance 2.5 at 1.8x lower cost.
faq
what is the seedance 2.5 prompt character limit?
we didn't find a published hard limit. the BytePlus API docs recommend no more than 1,000 English words or 500 Chinese characters. our 953-word prompt ran without errors and all ten scenes came out.
should seedance prompts be in english or chinese?
both work. our Chinese ad template beat every English rewrite we made of it, but a faithful English translation of the same template gave all ten scenes. if you start from a proven prompt, translate it word for word and change only the slots – don't rewrite it.
do timestamps work in seedance prompts?
in Seedance 2.5, yes, in whole seconds (0–4s). BytePlus says Seedance 2.0 ignores timestamps and responds to shot numbers ("Shot 1", "Shot 2") instead.
how do i reference images in a seedance prompt?
with the tag your platform inserts: @Image 1 on BytePlus, @Image1 in Dreamina, [Image1] on Replicate. list several one by one – a range like @image4-@image9 broke the parser for us.
can i use a photo of a real person?
not directly. BytePlus says Seedance 2.0 and 2.5 don't accept reference images or videos with real human faces; verified people go through a private asset library. recognisable cartoon versions of real people can be rejected too.
do these prompts work in sora 2, veo or kling?
the camera and film words are standard film vocabulary, and Runway's camera glossary uses the same terms, so they carry over. the reference tags and timestamp rules are Seedance-specific. we haven't run this template in other models.
why does my seedance video have random music?
sound generation is on by default, and if the prompt doesn't describe the sound, the model chooses it. describe what you hear on each beat, or write "no music".
sources
- ByteDance Seed: introducing Seedance 2.5 – announcement, July 31, 2026
- ByteDance Seed: Seedance 2.0 official launch – February 12, 2026
- BytePlus ModelArk: Seedance 2.5 tutorial – modes, resolutions, aspect ratios, reference tags
- BytePlus ModelArk: video generation tutorial – durations, model IDs
- BytePlus ModelArk: create task API – prompt length recommendation
- BytePlus ModelArk: Seedance 2.5 prompt guide – prompt structure, timestamps vs shot numbers
- BytePlus ModelArk: portrait guide – real faces
- BytePlus ModelArk: pricing
- Dreamina: Seedance 2.5 prompt guide
- Dreamina: Seedance 2.0 prompts, examples and 4K prompt guide
- Dreamina: Seedance 2.5 launch – regions, and September offer FAQ
- BytePlus: how to write better Seedance 2.5 prompts
- magnific: Seedance 2.5
- Replicate: bytedance/seedance-2.5 – reference limits
- fal: Seedance 2.5 text-to-video and Seedance 2.0 reference-to-video API
- Runware: Seedance 2.5, WaveSpeed: Seedance 2.5, Higgsfield: Seedance 2.5, Krea: Seedance 2.5, Kie.ai: Seedance 2.5
- Runway: camera terms
- Higgsfield: Seedance prompting guide, Higgsfield: generating with Seedance 2.0
- Krea: Seedance 2.0 API guide
- fal: Seedance 2.0 prompting guide
- OpenArt: Seedance 2.5 prompt guide
- GoodCase prompt pages: Seoul home video, frozen diner, K-pop MV, Mini DV espresso
- Reddit: jet robot, storyboard grid, tokusatsu, phone realism
- GitHub: LearnPrompt/awesome-seedance, imagineVid/Awesome-seedance-2-0-prompts-and-skills