 Felix Laurent
Alibaba released Qwen4-Max on November 16, 2026, five days after a quiet preview with no benchmarks. This time the Qwen team brought charts. On its own tests, Qwen4-Max matches or beats Claude Opus 5.5 on several agent and coding tasks. The independent Artificial Analysis Intelligence Index tells a different story: Qwen4-Max scores 43, sixteen points behind Opus 5.5 and three behind China's Kimi K3.1 Pro.
The model is still a big step up from Qwen3.8-Max and much cheaper to run. Whether that makes it a good release depends on what you compare it with.
What Alibaba launched with Qwen4-Max
Qwen4-Max is built on a new mixture-of-experts architecture with native vision and a 1 million-token context window. It takes text and images and returns text. Alibaba has not published a parameter count or a model card.
The API is live on QwenCloud. The model is also available in Qwen Studio, QwenWork and the coding tool Qoder, and through Alibaba's Token Plan subscription. Qwen4-Max itself stays closed, but the Qwen team said open weights for smaller Qwen4 models will be released later. It gave no date or model list. Unsloth, which publishes compressed versions of open models, said one of them will be Qwen4-27B. According to Unsloth, that model will run on machines with 16GB of RAM.
The price is lower than Qwen3.8-Max on every line.
| Price per 1M tokens | Qwen4-Max | Qwen3.8-Max |
|---|---|---|
| Input | $1.50 | $2.00 |
| Output | $4.50 | $6.00 |
| Cached input | $0.075 | $0.25 |
Alibaba also showed demos in 3D design, manufacturing and materials science. In one, the model turns a rough 3D blockout of a restaurant into a finished scene and a cinematic cut.
The bigger claims are about efficiency.
Alibaba's numbers: fewer tokens, lower cost
Alibaba says Qwen4-Max beats Qwen3.8-Max while using up to about 50% fewer tokens. Two examples from its post:
- Work360, Alibaba's new benchmark of professional tasks: token use drops about 24% at xhigh reasoning and 35% at high. Average cost per task falls from $4.43 to $1.67.
- Terminal-Bench 4.0: token use drops about 48% at xhigh and 49% at high.
Work360 is Alibaba's own framework. It sorts work into 26 top-level domains, 182 subdomains and 721 specialized fields, from finance and law to manufacturing and healthcare. Qwen4-Max scores 52.69 on it against 47.74 for Qwen3.8-Max, about 10% higher. No other lab has run it yet.
Alibaba also compared Qwen4-Max with rivals from the US and China.
Qwen4-Max vs Claude Opus 5.5 on Alibaba's benchmarks
Alibaba's chart covers sixteen tests. It pits Qwen4-Max against Qwen3.8-Max, Claude Opus 5.5, GPT-6.1 Sol, GPT-6 Astra and Kimi K3.1. Eight of them show the pattern well.
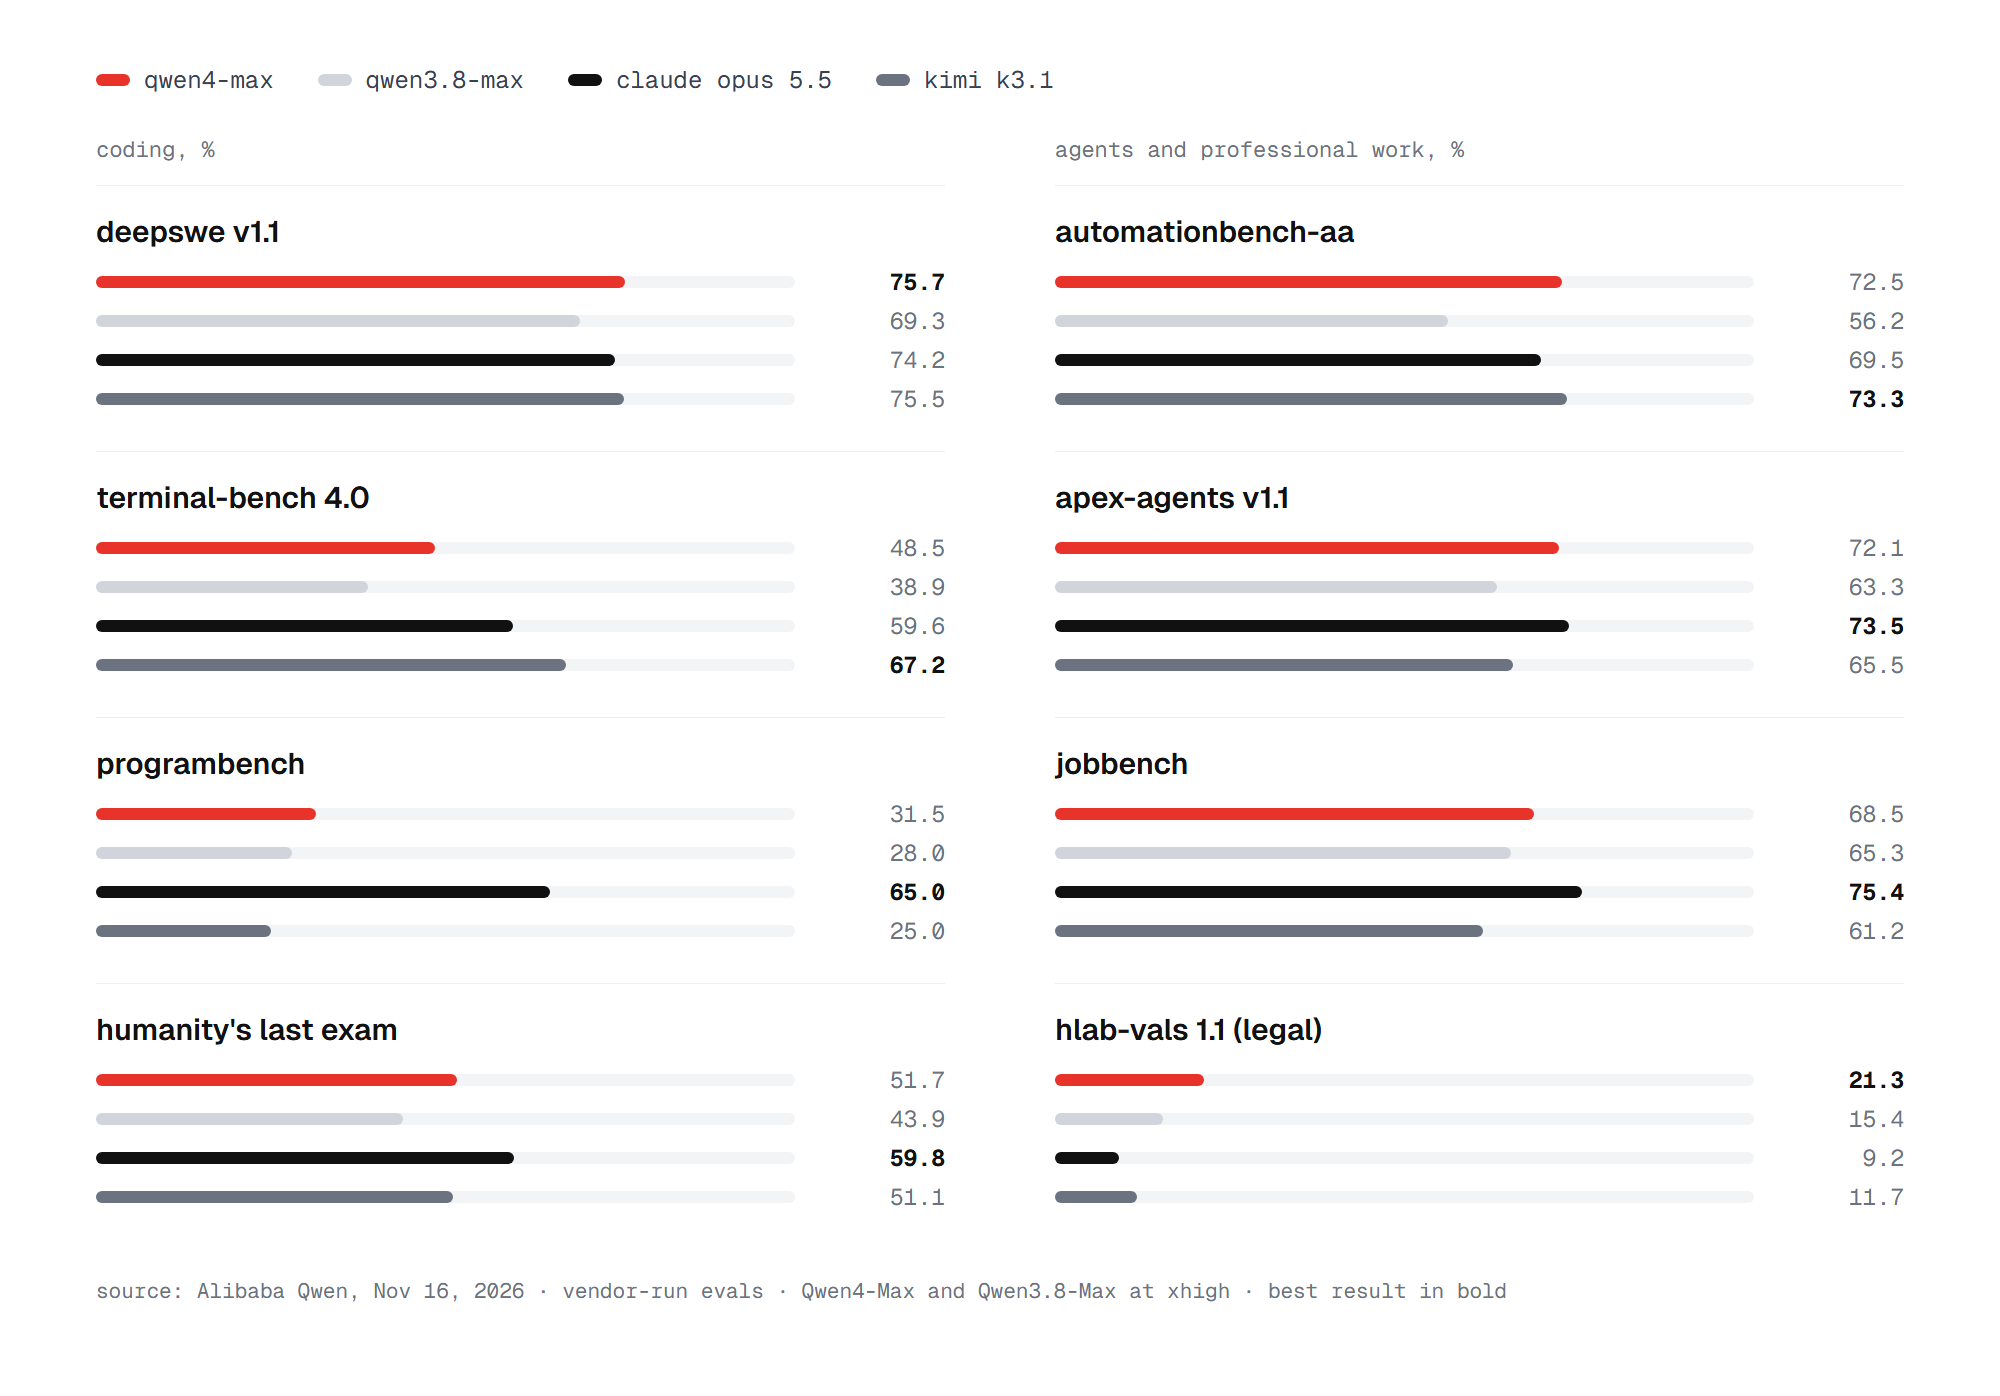
Qwen4-Max comes out ahead on DeepSWE, an agentic coding test, at 75.7%. It also wins clearly on HLAB-Vals legal agent work with 21.3% against 9.2% for Opus 5.5. It is close to Opus on APEX-Agents and ahead on AutomationBench-AA.
The gaps go the other way on harder coding and reasoning. On Terminal-Bench 4.0, Qwen4-Max scores 48.5% against 59.6% for Opus 5.5 and 67.2% for Kimi K3.1. On ProgramBench, which asks a model to replicate software from its behavior, it reaches 31.5% against 65.0% for Opus. Opus also leads on Humanity's Last Exam and JobBench. Elsewhere on Alibaba's chart, GPT-6.1 Sol and GPT-6 Astra beat Qwen4-Max on chart reading, video understanding and clinical reasoning.
Those are the vendor's numbers. The independent ones arrived within an hour.
What Artificial Analysis found
Artificial Analysis ran Qwen4-Max at xhigh reasoning through its Intelligence Index, which combines nine evaluations. The model scored 43.
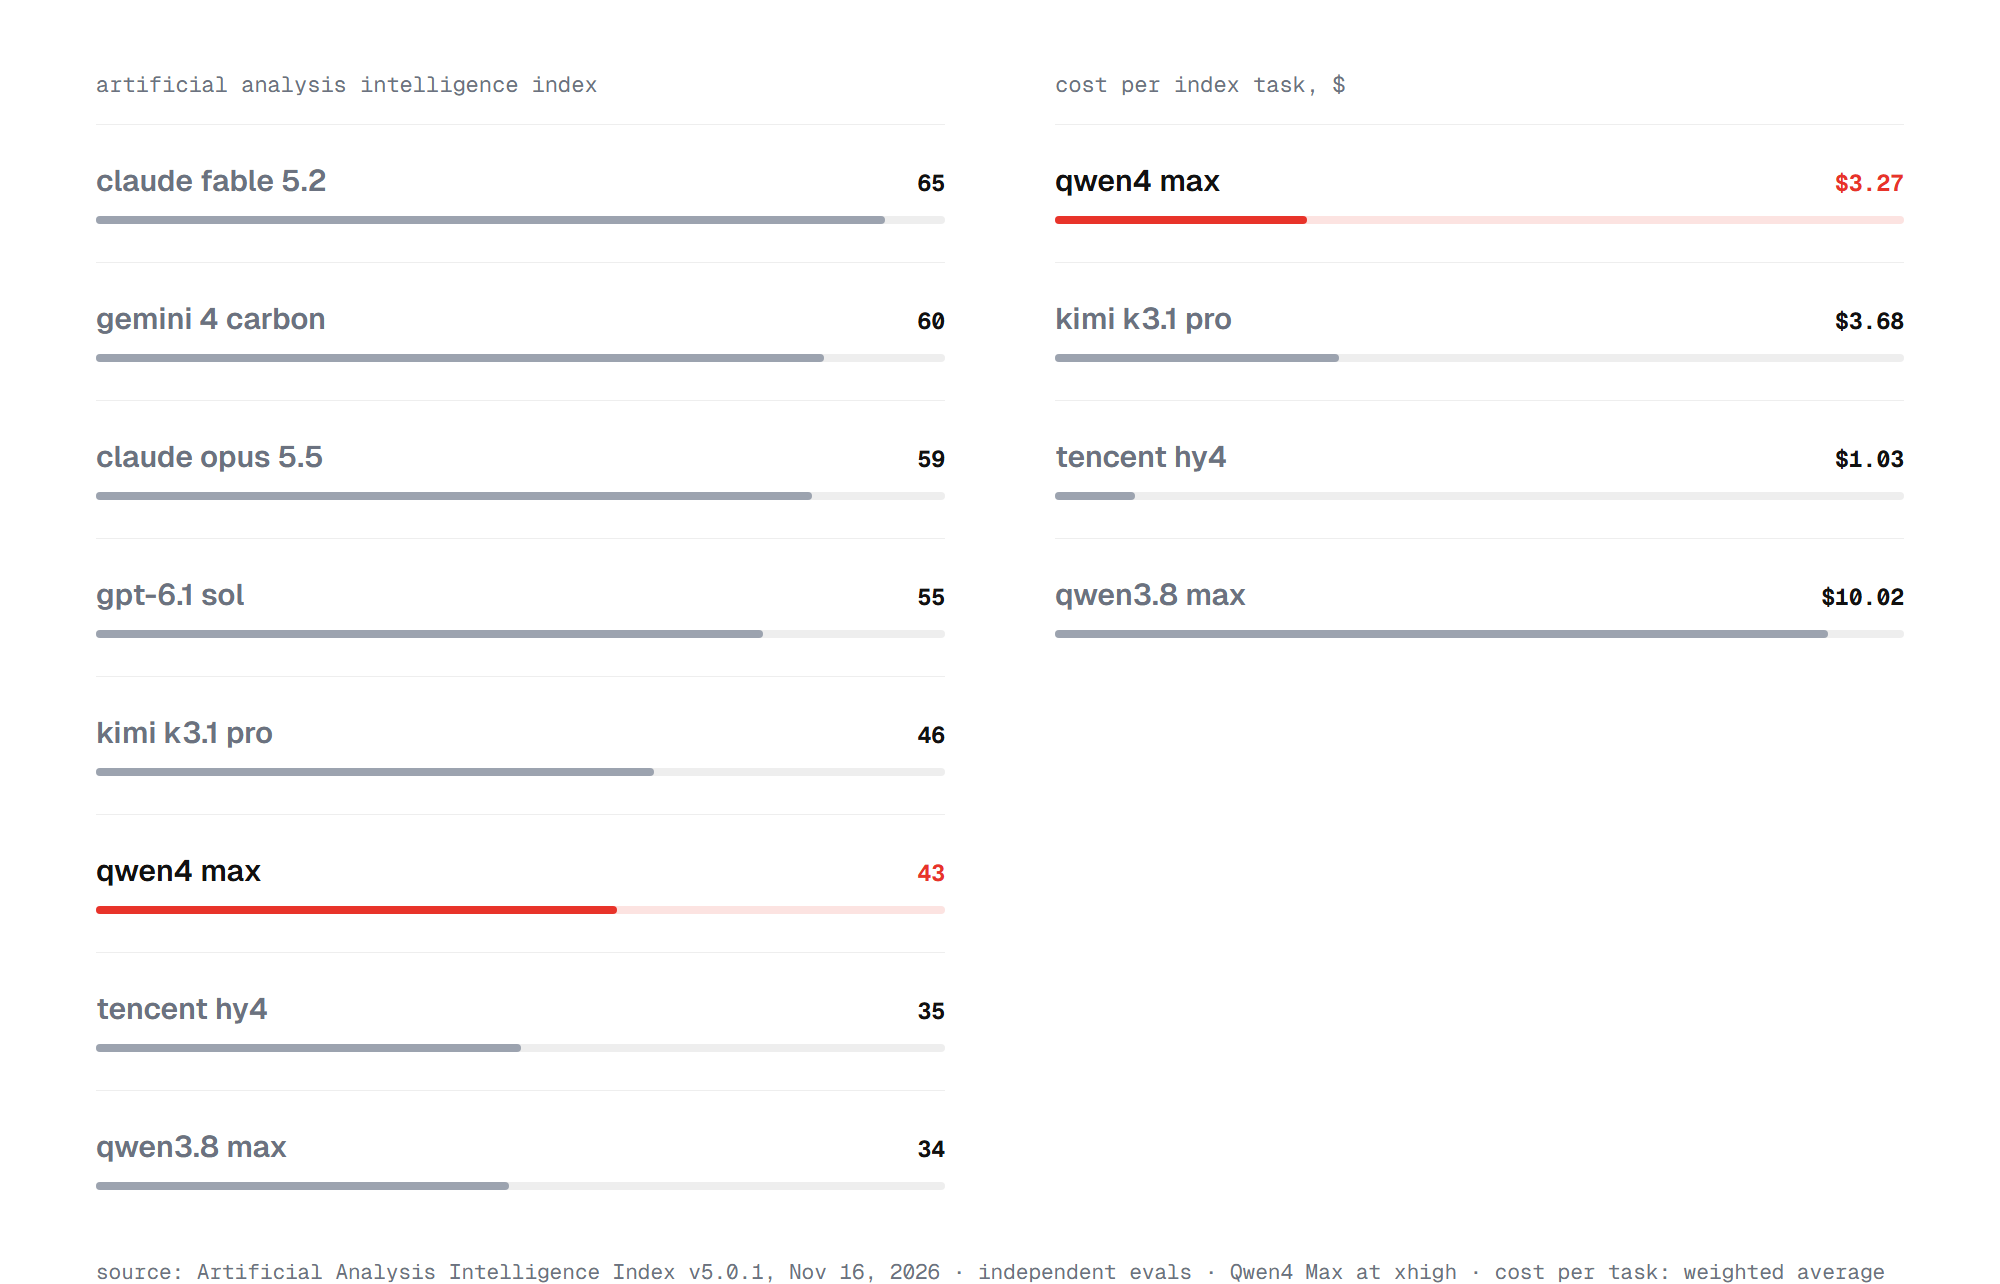
That is 9 points above Qwen3.8-Max and an improvement on every evaluation in the index. The biggest jumps came on HLE-Diamond, from 24% to 45%, on AA-Omniscience, up 18 points, and on AutomationBench-AA, up 17 points. On AA-Briefcase, which tests agent work on real business files, Qwen4-Max reached 1686 Elo, just ahead of Kimi K3.1 Pro at 1674.
Cost is the strongest part of the result. One index task costs $3.27 with Qwen4-Max, about 3x less than Qwen3.8-Max at $10.02 and 11% less than Kimi K3.1 Pro at $3.68. Qwen4-Max uses about 105,000 output tokens per task against 171,000 for its predecessor. Kimi still uses fewer, about 72,000.
The weak spot is coding. Qwen4-Max scored 48% on Terminal-Bench 4.0, far below Kimi K3.1 Pro at 67%. On FrontierCode 2.0, Cognition's private test of real-world coding, it scored 26%. That ties Kimi and trails Tencent's Hy4 at 31%.
The ranking puts Qwen4-Max in the middle of the pack. Claude Fable 5.2 leads with 65, followed by Gemini 4 Carbon at 60 and Opus 5.5 at 59. Among Chinese models, Kimi K3.1 Pro still leads, and Qwen4-Max sits just behind Meta's Muse Wonder at 44.
That gap between Alibaba's charts and the index drove the first reactions.
Why some call Qwen 4 a weak release
AI commentator Chubby (@kimmonismus) was blunt. "Qwen 4 is not a good release," he wrote on November 16. He noted that the model looks level with Opus 5.5 on key benchmarks, but "the AA Index paints a completely different picture."
He also repeated a theory he raised during the preview: that Qwen is struggling because it has been cut off from distilling stronger models. Distillation means training on another model's outputs. In June, Anthropic accused operators linked to Qwen of running about 28.8 million exchanges with Claude, according to Bloomberg. Anthropic says new defenses now block most such attempts. No one has shown that this affected Qwen4-Max, and Alibaba has not commented on the accusation.
The preview week already set expectations low. Testers complained about very long generation times and a viral 3D pelican with a broken wheel. Others found the model strong on long agent tasks. The final release fixes the missing numbers but does not change that mixed picture.
How Qwen4-Max compares with other Chinese models
The more useful comparison is with Qwen4-Max's direct rivals in China, since none of them reach the top US tier on the index either.
| Model | AA Intelligence Index | Cost per index task | Output tokens per task |
|---|---|---|---|
| Kimi K3.1 Pro | 46 | $3.68 | ~72K |
| Qwen4-Max | 43 | $3.27 | ~105K |
| Tencent Hy4 | 35 | $1.03 | ~78K |
| Qwen3.8-Max | 34 | $10.02 | ~171K |
Kimi K3.1 Pro stays the strongest Chinese model, especially for coding. Tencent Hy4 is three times cheaper per task but 8 points lower. Qwen4-Max lands between them, with the best knowledge-work score of the group. We compared the previous generation in our Hy4, GLM-5.3 and Qwen 3.8 Max test.
Is Qwen4-Max a good release
As a frontier model, no. It does not come close to Claude Opus 5.5, Fable 5.2 or Gemini 4 Carbon on independent tests, whatever Alibaba's charts suggest. It is not even the best Chinese model: Kimi K3.1 Pro beats it on the index and by a wide margin on coding.
As an upgrade, yes. Qwen4-Max is 9 points smarter than Qwen3.8-Max on the index, costs a third as much per task and leads its group on business-file work. For teams already on Alibaba Cloud doing documents, analysis or legal work, it is a cheap and real improvement. For coding agents, Kimi K3.1 Pro and the US models remain the better choice.
FAQ
What is Qwen4-Max?
Qwen4-Max is Alibaba's flagship AI model, released on November 16, 2026. It uses a new mixture-of-experts architecture with native vision and a 1 million-token context window.
How much does Qwen4-Max cost?
$1.50 per 1M input tokens, $4.50 per 1M output tokens and $0.075 per 1M cached input tokens on Alibaba's API. All three are lower than Qwen3.8-Max.
Is Qwen4-Max better than Claude Opus 5.5?
Not on independent tests. Qwen4-Max scores 43 on the Artificial Analysis Intelligence Index against 59 for Opus 5.5. It beats Opus on some of Alibaba's own benchmarks, such as DeepSWE and legal agent work, but trails it on Terminal-Bench, ProgramBench and Humanity's Last Exam.
Is Qwen4-Max open source?
No. Qwen4-Max is available only through Alibaba's API and apps. Alibaba says it will release open weights for smaller Qwen4 models later, including Qwen4-27B, according to Unsloth.
Sources
- Qwen's post on X – November 16, 2026
- Qwen4-Max, Qwen blog – November 16, 2026
- Qwen4-Max model page, QwenCloud
- Artificial Analysis's post on X – November 16, 2026
- Unsloth's post on X – November 16, 2026
- Chubby's post on X – November 16, 2026
- Anthropic alleges Alibaba's Qwen lab ran 28.8 million queries, Crypto Briefing