Felix Laurent
Claude Fable 5.2 Agent Arena results put Anthropic's new model at #1 with what Arena calls an unprecedented lead. Arena.ai reported on November 11 that Fable 5.2 (Max) scores a +30.4% net improvement. That is about 1.6 times the +19.5% of the runner-up, Claude Opus 5.5 (Max).
The result is based on about 4,700 real agent sessions from Arena's users. Fable 5.2 also ranks first in all three task categories Arena tracks: code, work and chat. Anthropic released the model two days earlier, on November 9.
How Agent Arena measures AI agents
Agent Arena ranks models by how they perform in real agent sessions on arena.ai, where they can use web search, files and a terminal. Users do not vote between two answers. Arena collects signals from each session and estimates how much a model improves results compared with an average model.
That estimate is the net improvement score. A model at +30.4% does about 30% better than an average model in the pool, by Arena's measure. Arena reports four of those signals. They track whether users praise or complain and whether the model follows their steering. The other two track confirmed task success and how reliably its terminal commands run.
Because the data comes from real sessions, the scores reflect everyday use rather than a fixed test. On that measure, the gap at the top is unusually large.
Claude Fable 5.2 vs Opus 5.5, Gemini 4 and GPT-6
Fable 5.2 leads Opus 5.5 by almost 11 points. Google's Gemini 4 Carbon (High) is third at +17.0%, and Claude Sonnet 5.5 (Max) fourth at +16.0%. Anthropic holds four of the top five places.
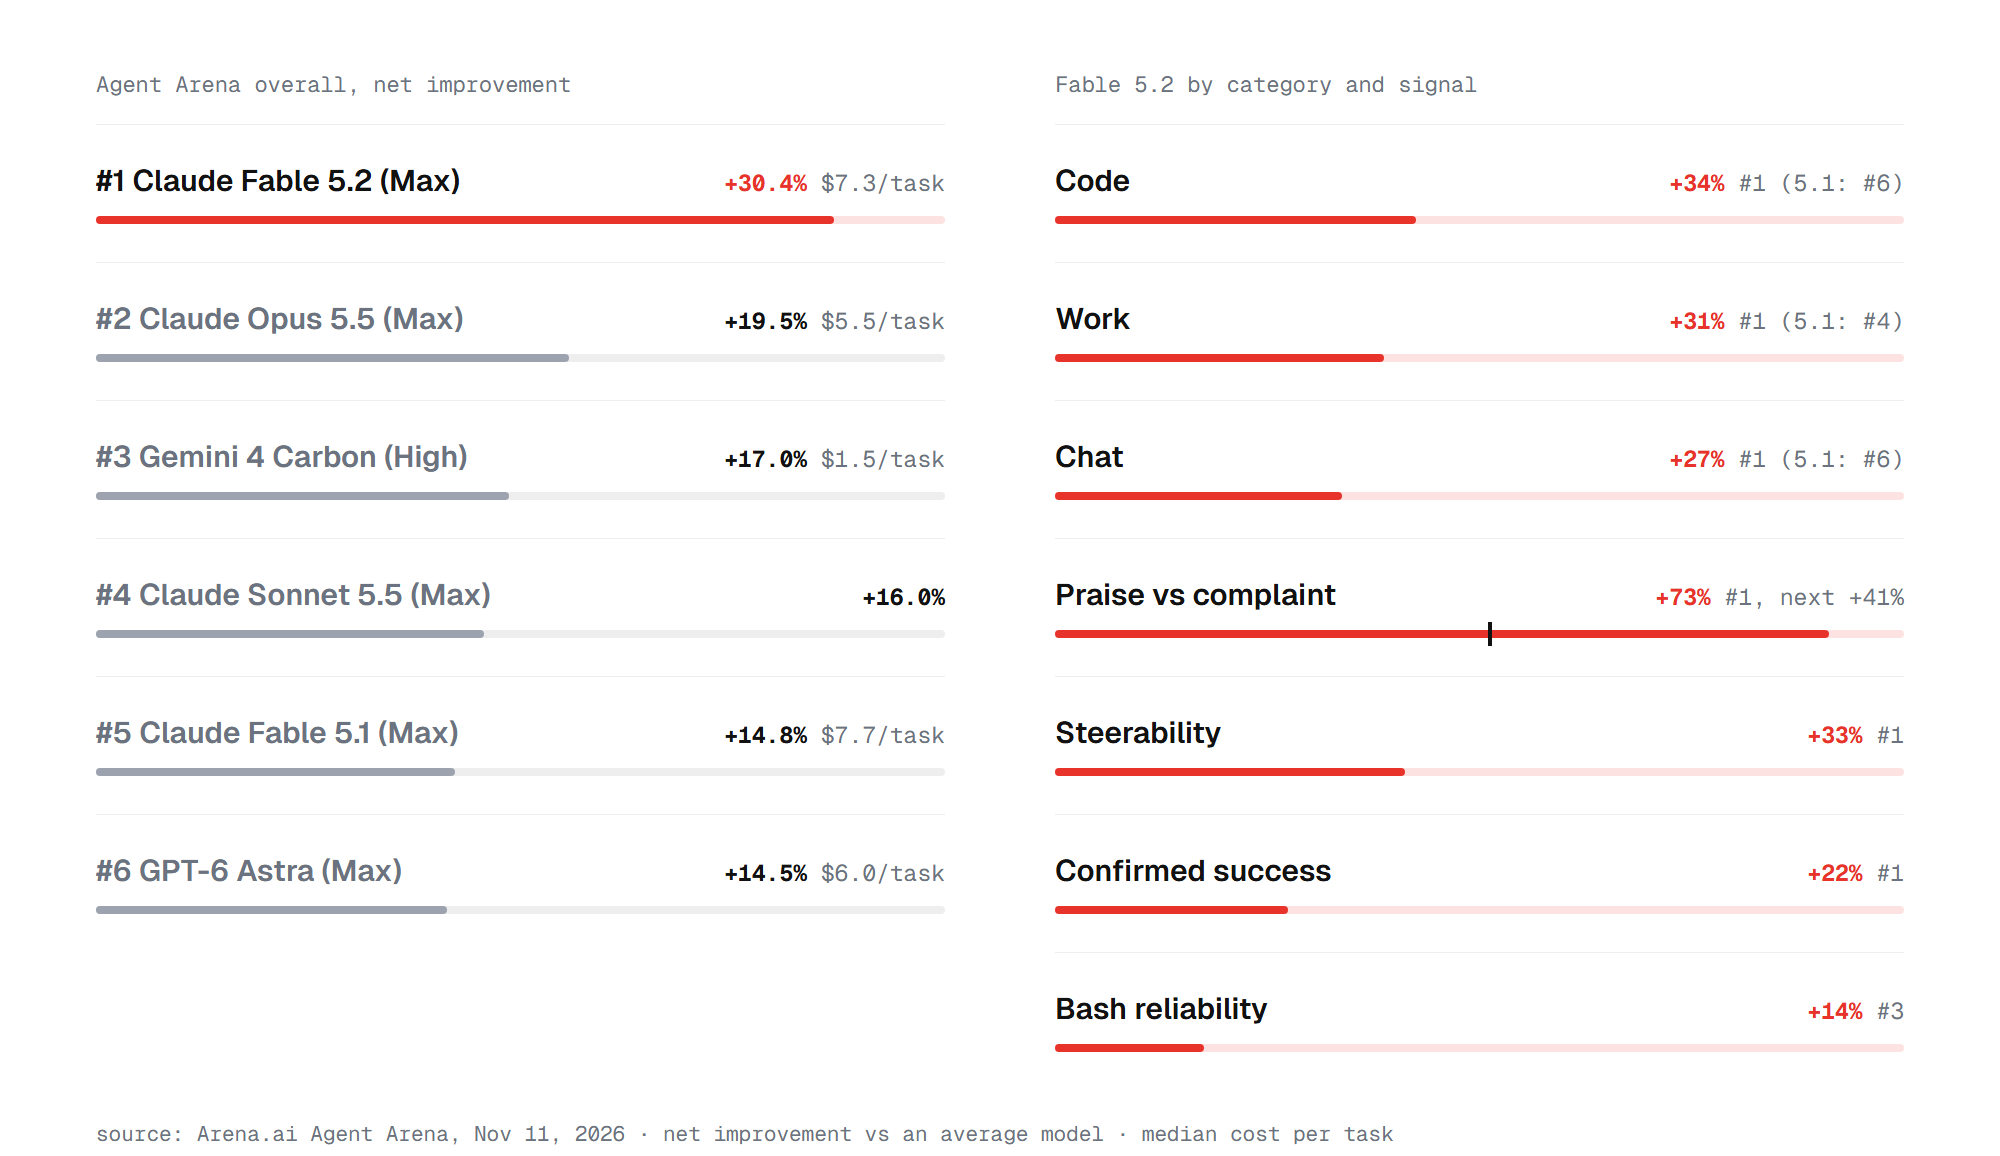
OpenAI's best entry is GPT-6 Astra (Max) in sixth place at +14.5%. GPT-6.1 Sol and GPT-6.1 Terra follow at +12.5% and +12.0%. Meta's Muse Wonder Full (Max) is tenth at +9.0%. The top open model, Kimi K3.1 Pro, sits 15th at +4.9%.
Arena's chart shows error bars for each model. Fable 5.2's range is wider than most, which is normal for a model with only two days of data. Even at the low end of that range, it stays clearly ahead of Opus 5.5.
The comparison with its own predecessor is just as telling.
How much Fable 5.2 improves on Fable 5.1
Fable 5.1 (Max) ranked fifth with +14.8%. Fable 5.2 roughly doubles that score and moves up four places. Arena says the new model improves on all four signals, with the largest gains in user satisfaction and steerability.
The praise-versus-complaint signal shows the biggest jump. Fable 5.2 scores +73% there, against +41% for the next model. It is also first on steerability at +33% and on confirmed success at +22%. Bash reliability is the one signal where it ranks only third, at +14%.
By category, Fable 5.2 scores +34% in code, +31% in work and +27% in chat. Fable 5.1 had ranked sixth in code, fourth in work and sixth in chat. Anthropic's own benchmarks had promised big gains in coding, and real users now report the same.
The other surprise in Arena's data concerns cost.
What Fable 5.2 costs per task
Arena puts Fable 5.2's median cost at $7.30 per task, 6% below Fable 5.1's $7.70. Anthropic cut the API price by 20%, to $8 per million input tokens and $40 per million output tokens. A smaller drop in cost per task than in price suggests the model uses somewhat more tokens per task.
It is still not the cheapest option. Opus 5.5 costs a median $5.50 per task, GPT-6 Astra $6.00 and Gemini 4 Carbon only $1.50. Gemini 4 Carbon delivers more than half of Fable 5.2's improvement for about a fifth of the cost.
The picture differs at the very top setting. On the Artificial Analysis Intelligence Index, Fable 5.2 at Max effort cost $26.54 per task, twice as much as Fable 5.1. That test uses long, hard tasks, where the model's verbosity adds up. We covered those results in our Claude Fable 5.2 release breakdown.
So the answer depends on the workload, which brings us to the main question.
Is Claude Fable 5.2 the best AI agent right now
Yes, by the best evidence available. Agent Arena measures real sessions, and Fable 5.2 leads by the widest margin on the board, in every category. It also beats its predecessor on every signal while costing slightly less per typical task.
The caveats are the sample and the price. About 4,700 sessions in two days is enough for a clear lead but will move as more data arrives. For teams on a budget, Opus 5.5 and Gemini 4 Carbon remain strong and much cheaper. For the hardest agent work, Fable 5.2 is the model to beat.
FAQ
Here are short answers to common questions about the result.
What is Claude Fable 5.2's Agent Arena score?
Fable 5.2 (Max) scores a +30.4% net improvement over an average model and ranks first. Claude Opus 5.5 (Max) is second at +19.5%.
How much does Claude Fable 5.2 cost?
The API costs $8 per million input tokens and $40 per million output tokens. In Agent Arena sessions, its median cost was $7.30 per task.
Is Claude Fable 5.2 better than GPT-6 Astra?
In Agent Arena, yes. GPT-6 Astra (Max) ranks sixth at +14.5%, less than half of Fable 5.2's score.