 Addy Crezee
fable 5 just put 16 points between anthropic and openai on hle.
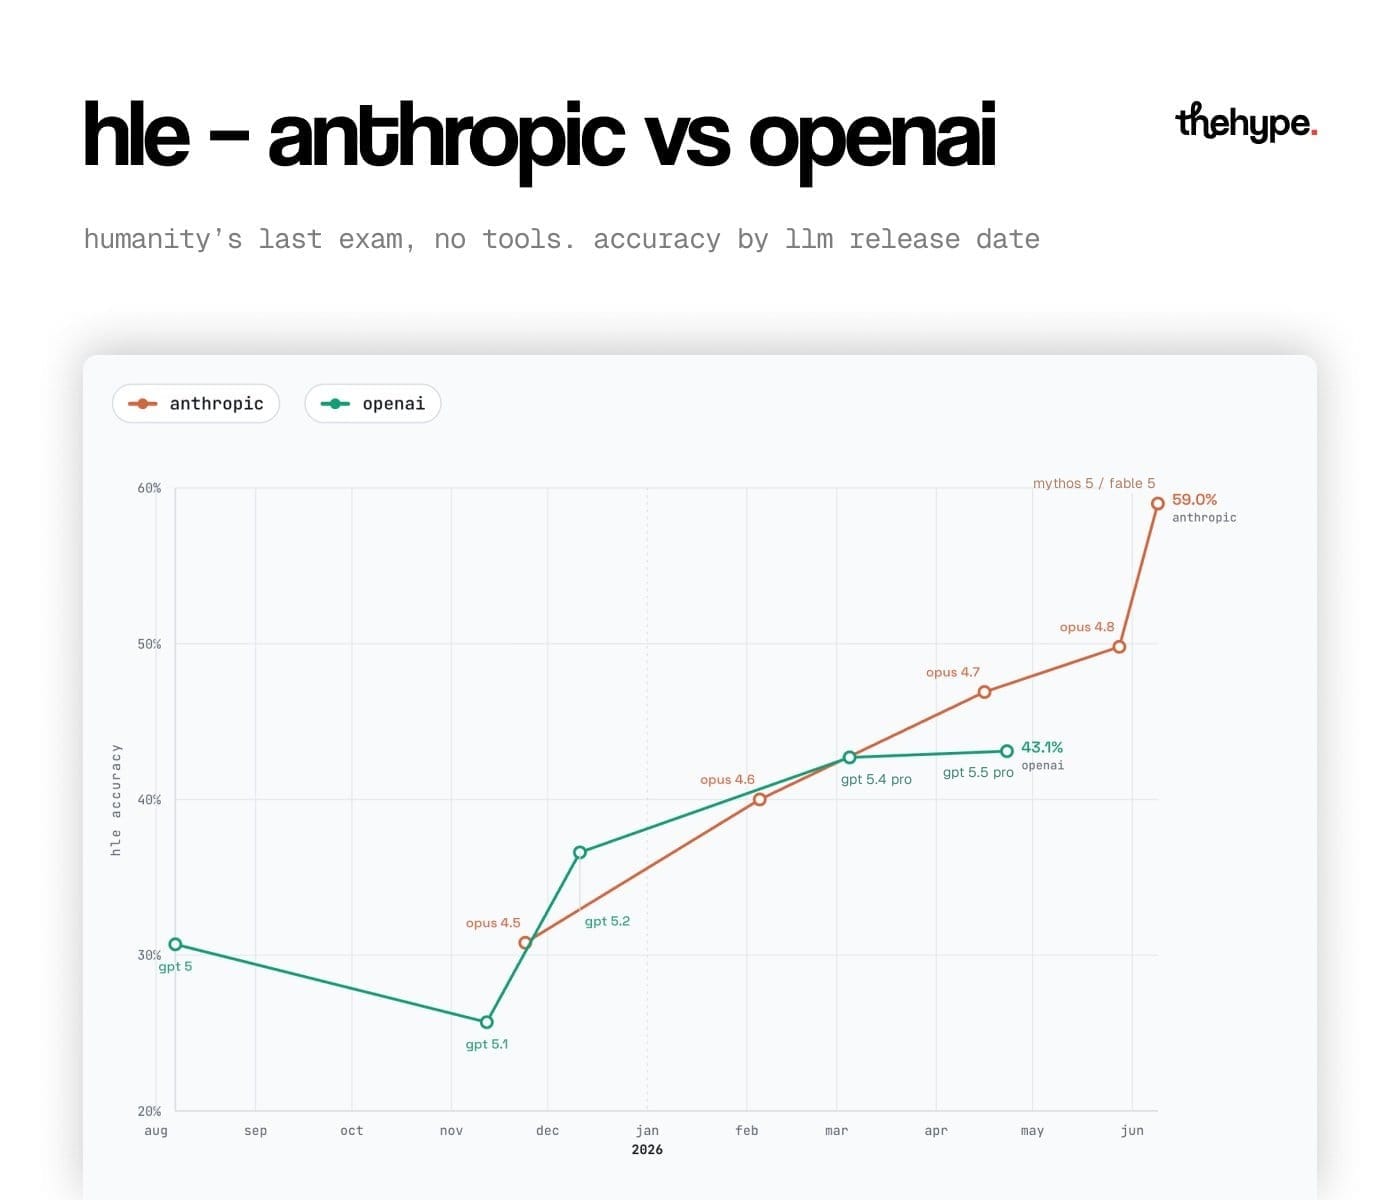
• anthropic mythos 5 / fable 5: 59%.
• openai gpt-5.5 pro: 43.1%.
that's a 15.9 point gap.
since november, anthropic has gone 30.8 → 59, gaining roughly 4 points a month and still accelerating.
openai's last two pro releases moved 42.7 → 43.1, essentially flat.
closing a lead that size would take a single jump larger than anything either lab has posted so far – not the current trend.
where the numbers come from
humanity's last exam (hle) is a set of 2,500 expert-written questions in math, science and the humanities. the scores here are "no tools": the model answers without search or code.
the 59% comes from anthropic's june 9 launch table for claude mythos 5 and fable 5. the table shows one score for both models, the higher of the two. on hle it carries an asterisk: fable 5 sends some biology and chemistry questions to opus 4.8, so its own score is lower.
openai's line on the chart uses its pro models. the 43.1% is gpt-5.5 pro, and the 42.7% before it is gpt-5.4 pro, both from openai's gpt-5.5 launch on april 23. the standard gpt-5.5 scored 41.4%.
how the gap opened
the two lines crossed in march. after that, anthropic released claude opus 4.7 at 46.9%, opus 4.8 at 49.8% and then fable 5. openai's pro models went from 42.7% to 43.1% over the same period.
update, october 16, 2026: the gap is narrowing
both labs shipped new models after june. in september, anthropic launched fable 5.1 and reported 60.9% on hle without tools, up from 57.8% for fable 5 alone. openai launched gpt-6 sol and gpt-6 astra but has not published a no-tools hle score for them.
artificial analysis runs hle on every model itself, with the same setup. its current top scores:
| model | lab | hle, no tools |
|---|---|---|
| claude opus 5.5 | anthropic | 61.4% |
| claude fable 5.1 | anthropic | 59.1% |
| gemini 4 argon | 57.1% | |
| gpt-6 astra | openai | 54.7% |
on the same runs, fable 5 scores 55.5% and gpt-5.5 scores 45.8%, a 9.7-point gap. today the best models of the two labs are 6.7 points apart. anthropic gained 5.9 points since june, and openai gained 8.9.
anthropic still leads on hle. but openai is closing the gap, and google's gemini 4 argon now sits between them.
sources
- claude fable 5 and claude mythos 5 – anthropic, june 9, 2026, benchmark table
- introducing gpt-5.5 – openai, april 23, 2026, gpt-5.5 and gpt-5.5 pro scores
- claude fable 5.1 and claude mythos 5.1 – anthropic, september 2026
- humanity's last exam on artificial analysis – independent runs, october 16, 2026
- humanity's last exam – the benchmark