 Felix Abagnale
mistral released voxtral 3 on october 20, 2026: three speech-to-text models, a text-to-speech model and a voice agent sdk in one api. mistral says the new transcription models beat elevenlabs scribe v2, gemini 3.5 transcribe and whisper. we checked that claim against the artificial analysis speech-to-text leaderboard. voxtral small transcribe 3 is third there with a 2.1% word error rate, behind microsoft and alibaba.
what mistral announced
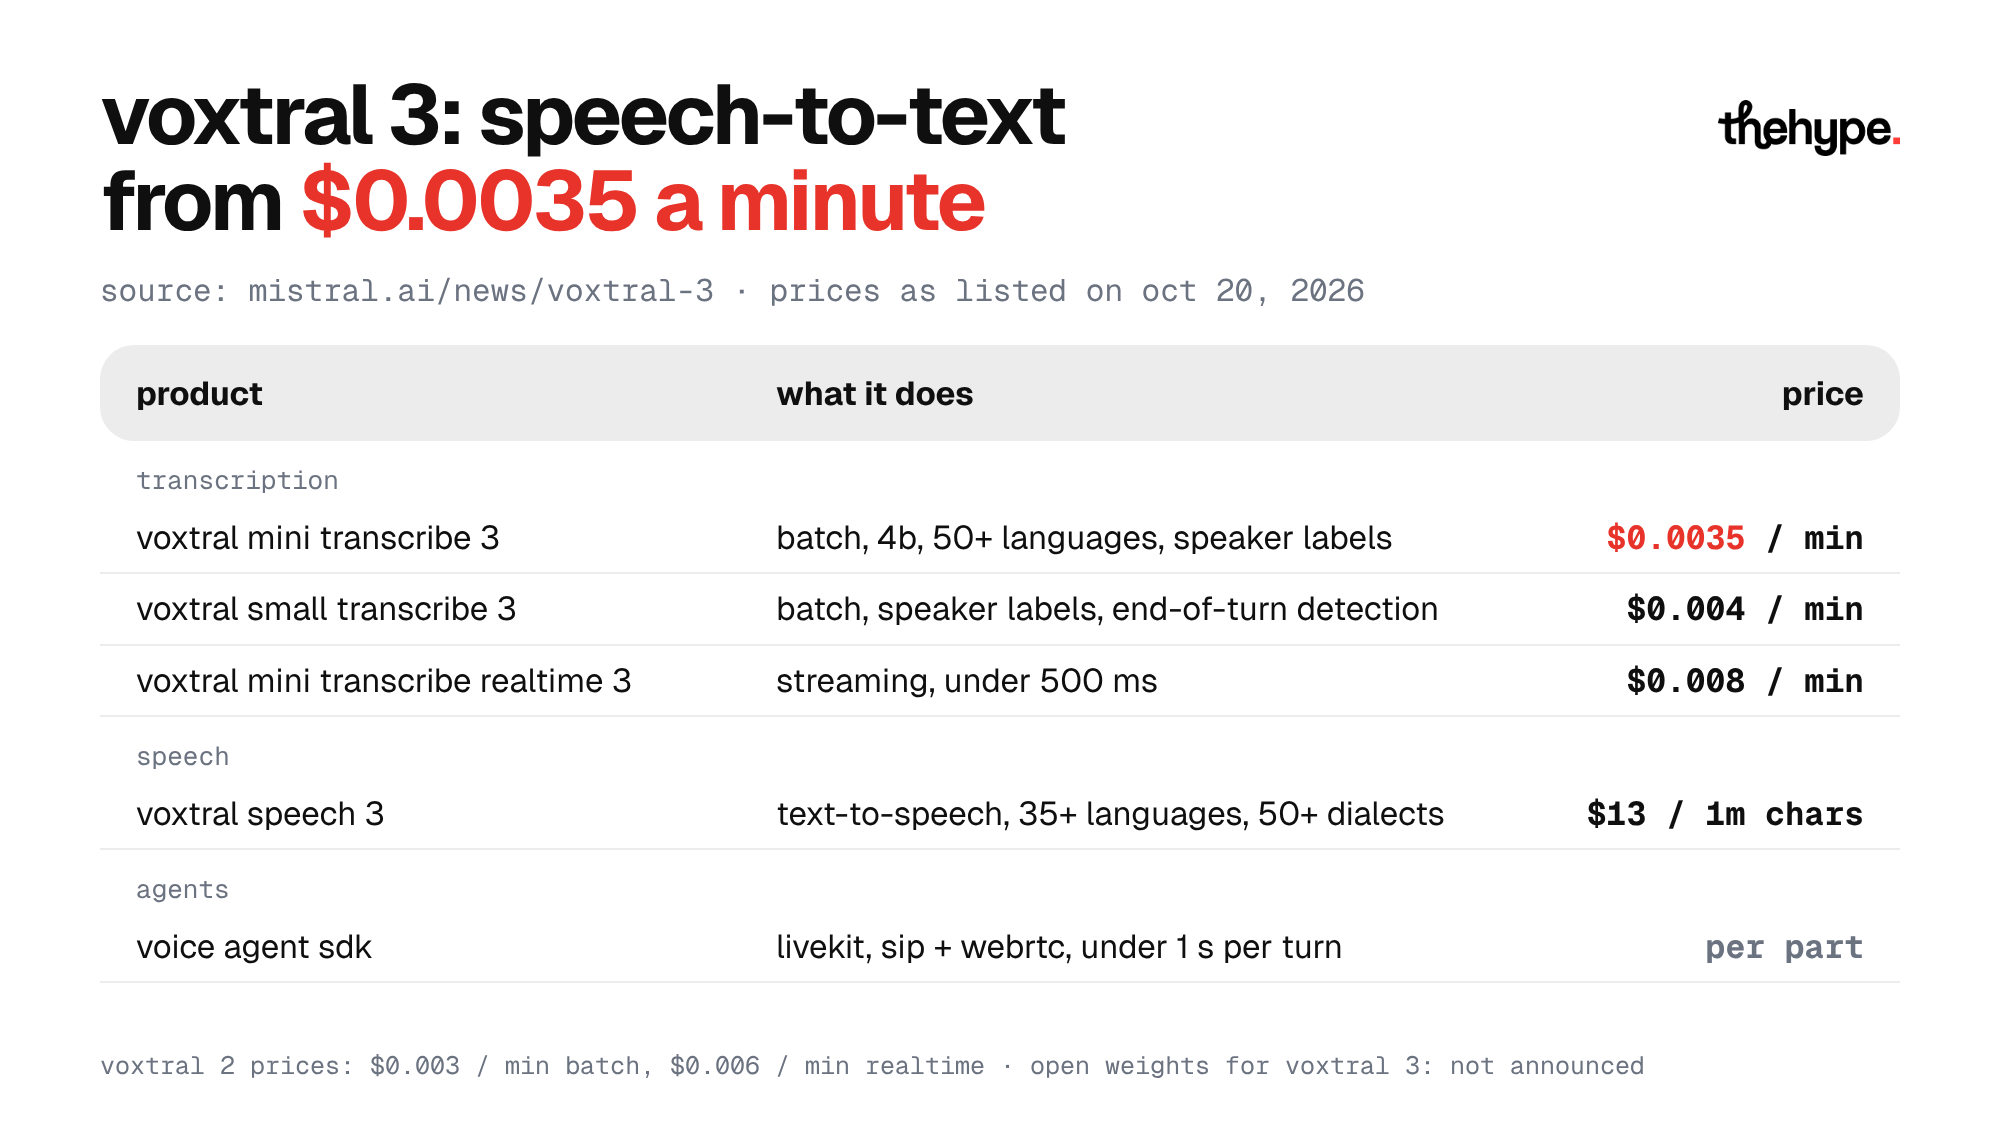
voxtral 3 is the third generation of mistral's speech models, and the first one built as a full voice stack. the release covers batch transcription, live transcription, speech synthesis and an sdk that chains them into a phone or app agent. batch transcription costs $0.0035 a minute on the mini model and $0.004 on the small one. live transcription costs $0.008 a minute, and speech costs $13 per 1m characters. the agent sdk is billed by the parts it uses.
mistral gives a parameter count only for the mini model. the other sizes are not on the announcement page.
what is new in voxtral 3
the release is aimed at call centers, meeting tools and voice agents. most of the new features solve problems those products run into:
- speaker labels are built into transcription, so a call transcript says who spoke when
- context biasing takes a list of names and terms as plain text, with no fine-tuning
- end-of-turn detection reads both sound and meaning, so an agent cuts in less often
- the tts model takes controls for emotion, pacing and emphasis, plus phoneme hints for hard words
- a pro voice clone needs about 30 minutes of recorded audio
- the agent sdk is built on livekit and handles phone calls over sip and apps over webrtc
mistral says a full agent turn takes under one second, and the agent stops talking when the caller interrupts. the models run on eu, us and global endpoints, or on a company's own servers through mistral sales.
what mistral has published
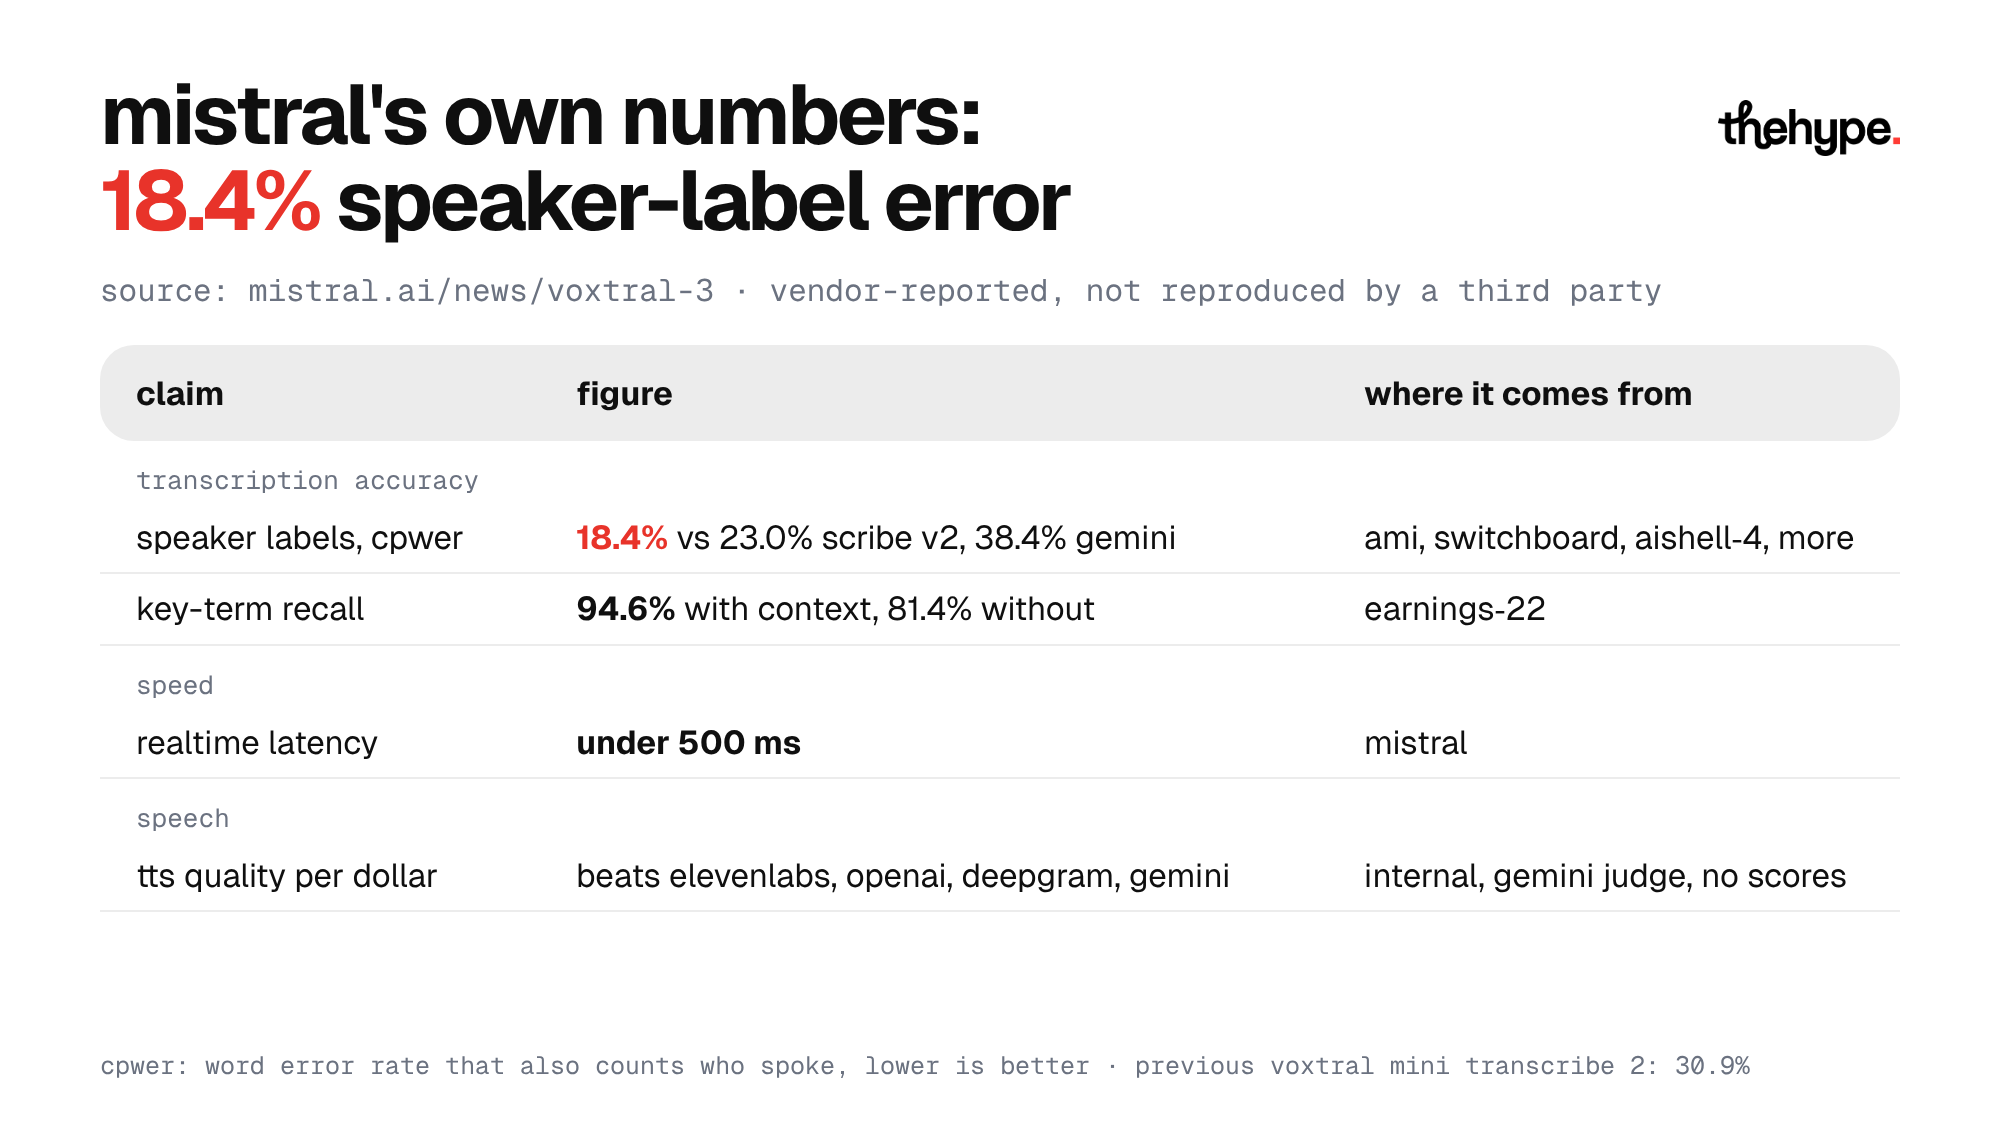
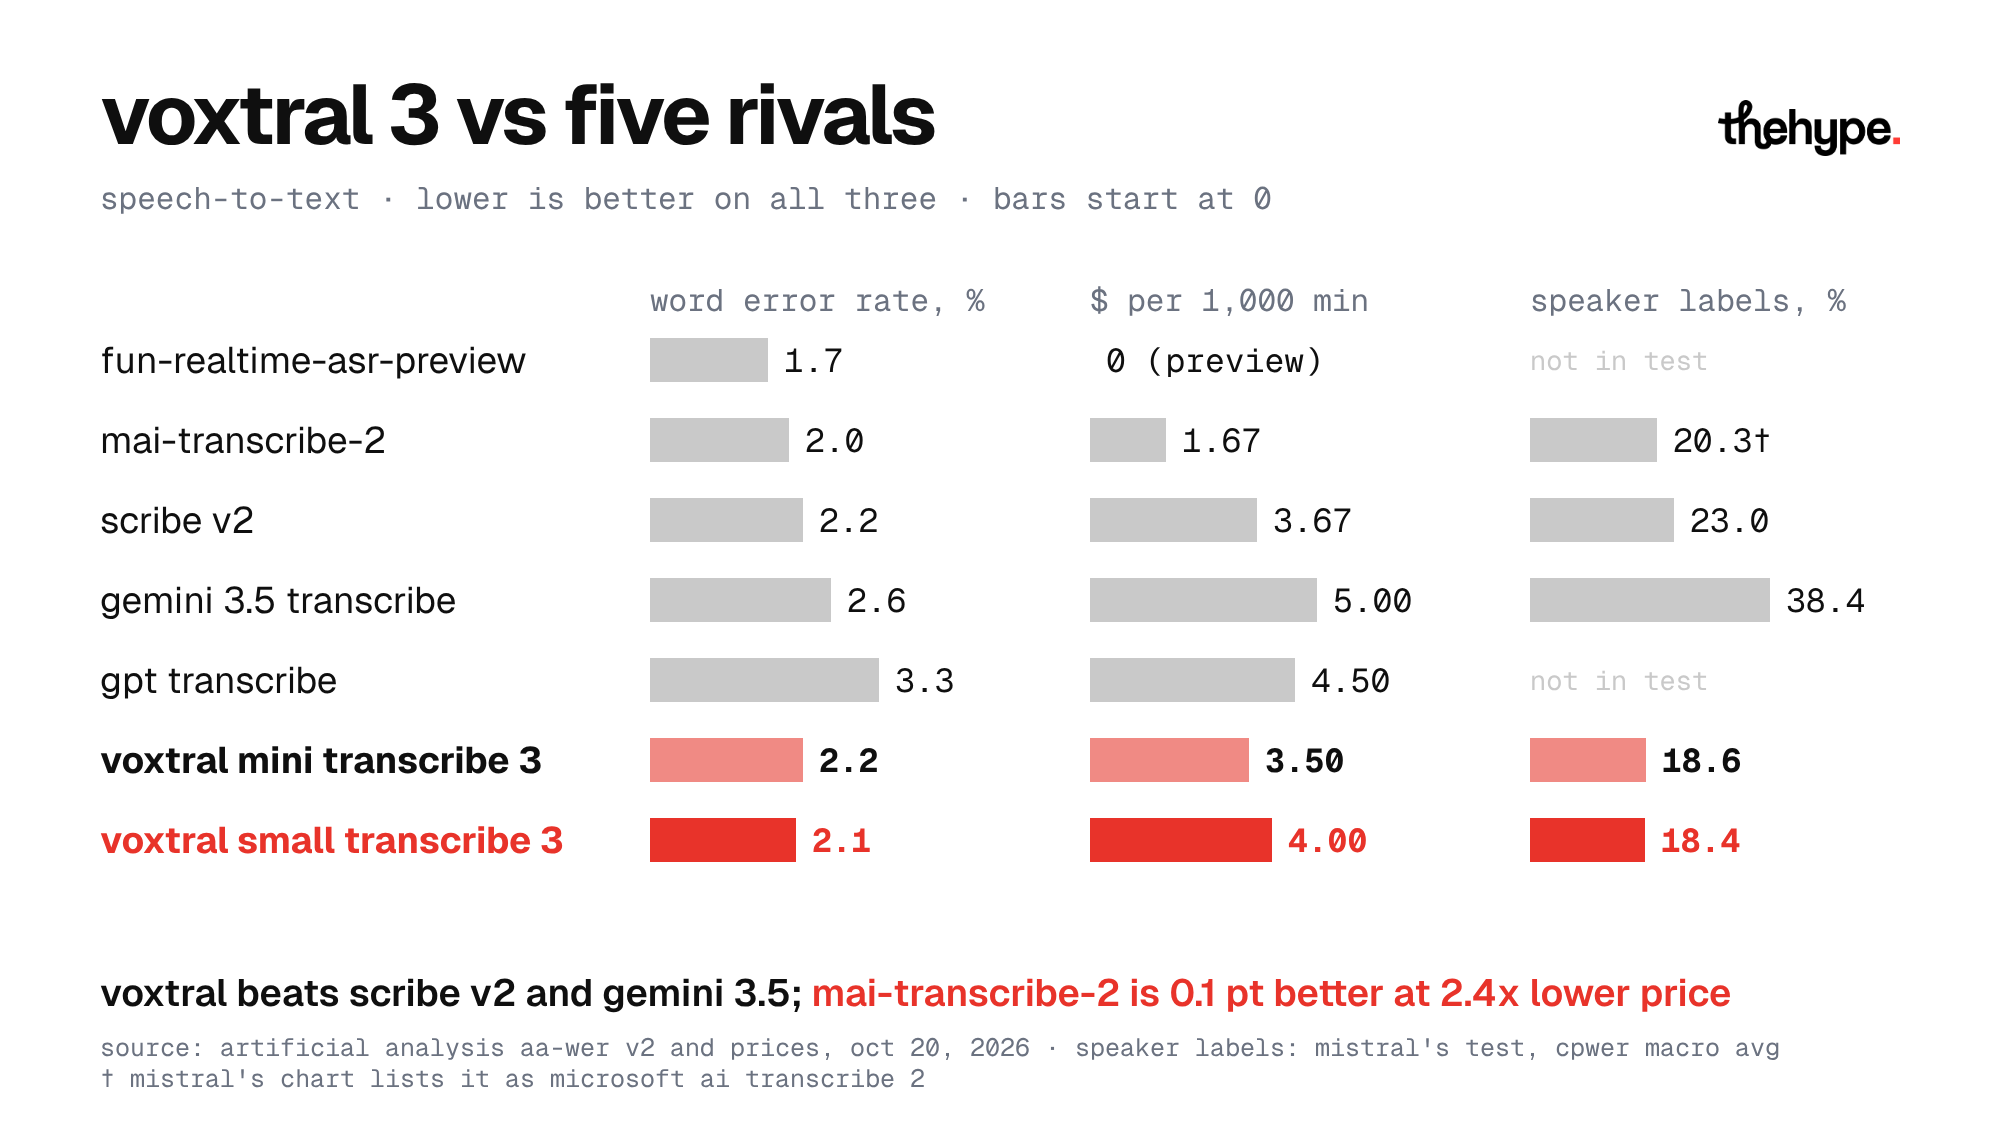
mistral backs the launch with its own benchmark charts, and no third party has reproduced them yet. on speaker labels, voxtral small transcribe 3 scores 18.4% cpwer. scribe v2 scores 23.0%, and gemini 3.5 transcribe scores 38.4%. given a list of terms, key-term recall on earnings calls rises from 81.4% to 94.6%. realtime latency is under 500 ms. the tts comparison is an internal test judged by a gemini model, with no scores published.
the speaker-label result is the strongest of these. voxtral small transcribe 3 edges past pyannote at 19.0%, a model built only for that job. the previous voxtral mini transcribe 2 scored 30.9% on the same test.
what the independent test shows
artificial analysis runs its own word error rate index, aa-wer, on about eight hours of audio. half of it is agent-style conversation, and the rest is parliament speech and earnings calls. lower is better.
alibaba's fun-realtime-asr-preview leads at 1.7% as a free preview. microsoft mai-transcribe-2 follows at 2.0% for $1.67 per 1,000 minutes. voxtral small transcribe 3 is third at 2.1% for $4.00, and the mini model ties scribe v2 at 2.2%. gemini 3.5 transcribe scores 2.6%, and gpt transcribe scores 3.3%.
the claim holds against the rivals mistral named. voxtral small transcribe 3 beats scribe v2, gemini 3.5 transcribe and gpt transcribe. it does not beat microsoft mai-transcribe-2, which is 0.1 points ahead and costs 2.4 times less.
voxtral 3 costs more than voxtral 2
the new models are priced above the previous generation. voxtral mini transcribe 2 cost $0.003 per minute in february 2026, and voxtral realtime cost $0.006. the new batch model is 17% more expensive, and the realtime model is 33% more expensive. mistral is now priced near elevenlabs rather than at the bottom of the market.
what is still missing
the announcement does not say whether any voxtral 3 weights are open. voxtral realtime from february shipped under apache 2.0, so the open-weight story is not settled. the tts comparison has no published scores, only charts judged by another lab's model. the mistral docs also note a limit: speaker labels and turn detection cannot run in the same realtime session.
sources
- voxtral 3 announcement, mistral blog – models, prices, mistral's benchmarks, october 20, 2026
- speech-to-text overview, mistral docs – features and the realtime session limit
- speech-to-text leaderboard, artificial analysis – aa-wer v2 and prices, read october 20, 2026
- voxtral transcribe 2 announcement, mistral blog – previous prices and the apache 2.0 license, february 4, 2026