 Yana Lialuke
grok voice 3.0 dubbed two animated movie scenes for $0.012. gpt audio charged $0.111 for the same lines - about 9x more. we voiced the red pill monologue from the matrix and eris losing her temper in sinbad with both models and put each track on the same ai-generated video.
the setup
we rebuilt both scenes as new animation, then voiced them twice. the text, the video and the timing were the same for both models.
- video: bytedance seedance 2.0 via openrouter, one prompt per scene
- grok voice 3.0
- gpt audio: openrouter, model
openai/gpt-audio - voices: grok – zagan for the mentor, leo for the sailor, celeste for eris. gpt audio - onyx, ash, shimmer
- every line was trimmed and placed on the lip timing by hand, then checked with speech-to-text
only the voice track changes between the two takes.
the numbers
grok bills $15 per 1m characters, emotion tags included. gpt audio bills by audio output tokens, about $0.003 per second of speech in our run.
| scene | grok voice | gpt audio |
|---|---|---|
| eris, sinbad | $0.006 | $0.050 |
| red pill, the matrix | $0.006 | $0.061 |
| both scenes | $0.012 | $0.111 |
eris, sinbad
the scene is a sailor on a cliff and a giant storm goddess who turns from cold contempt to a furious shout.
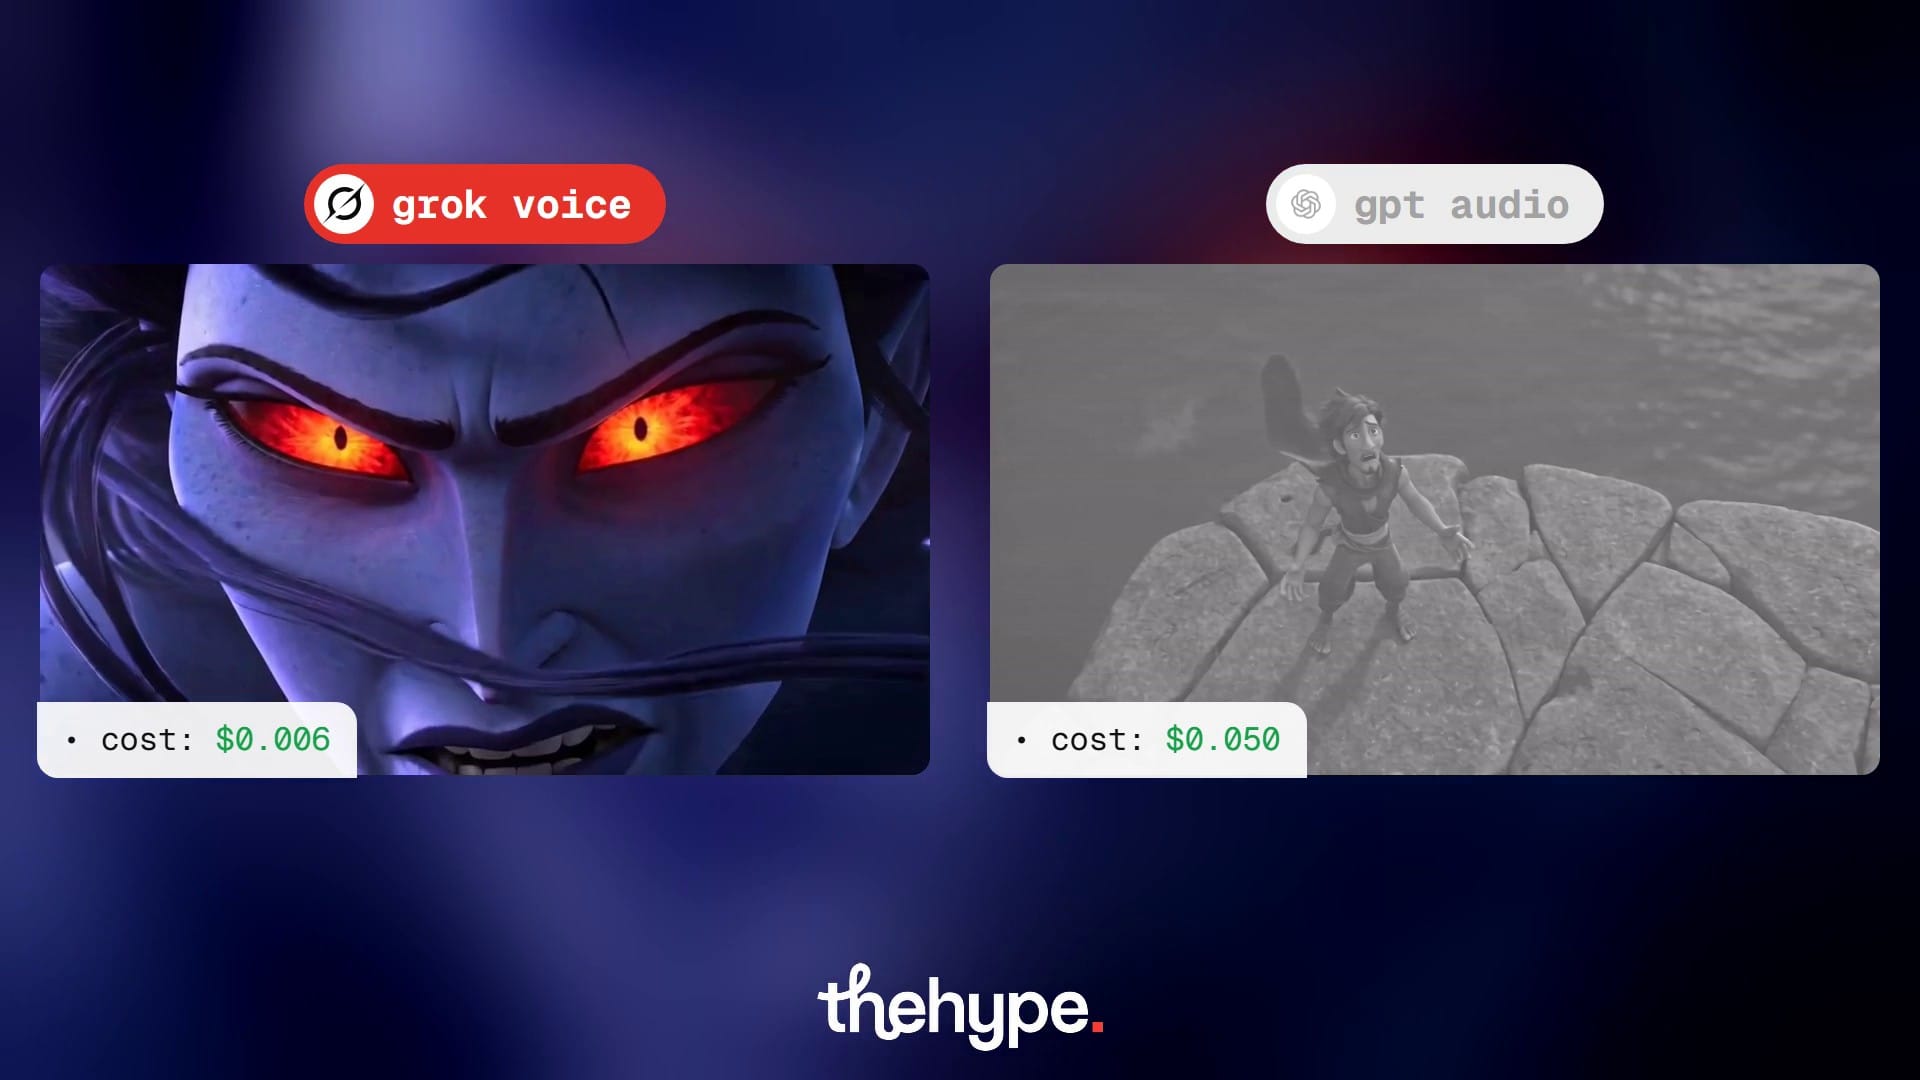
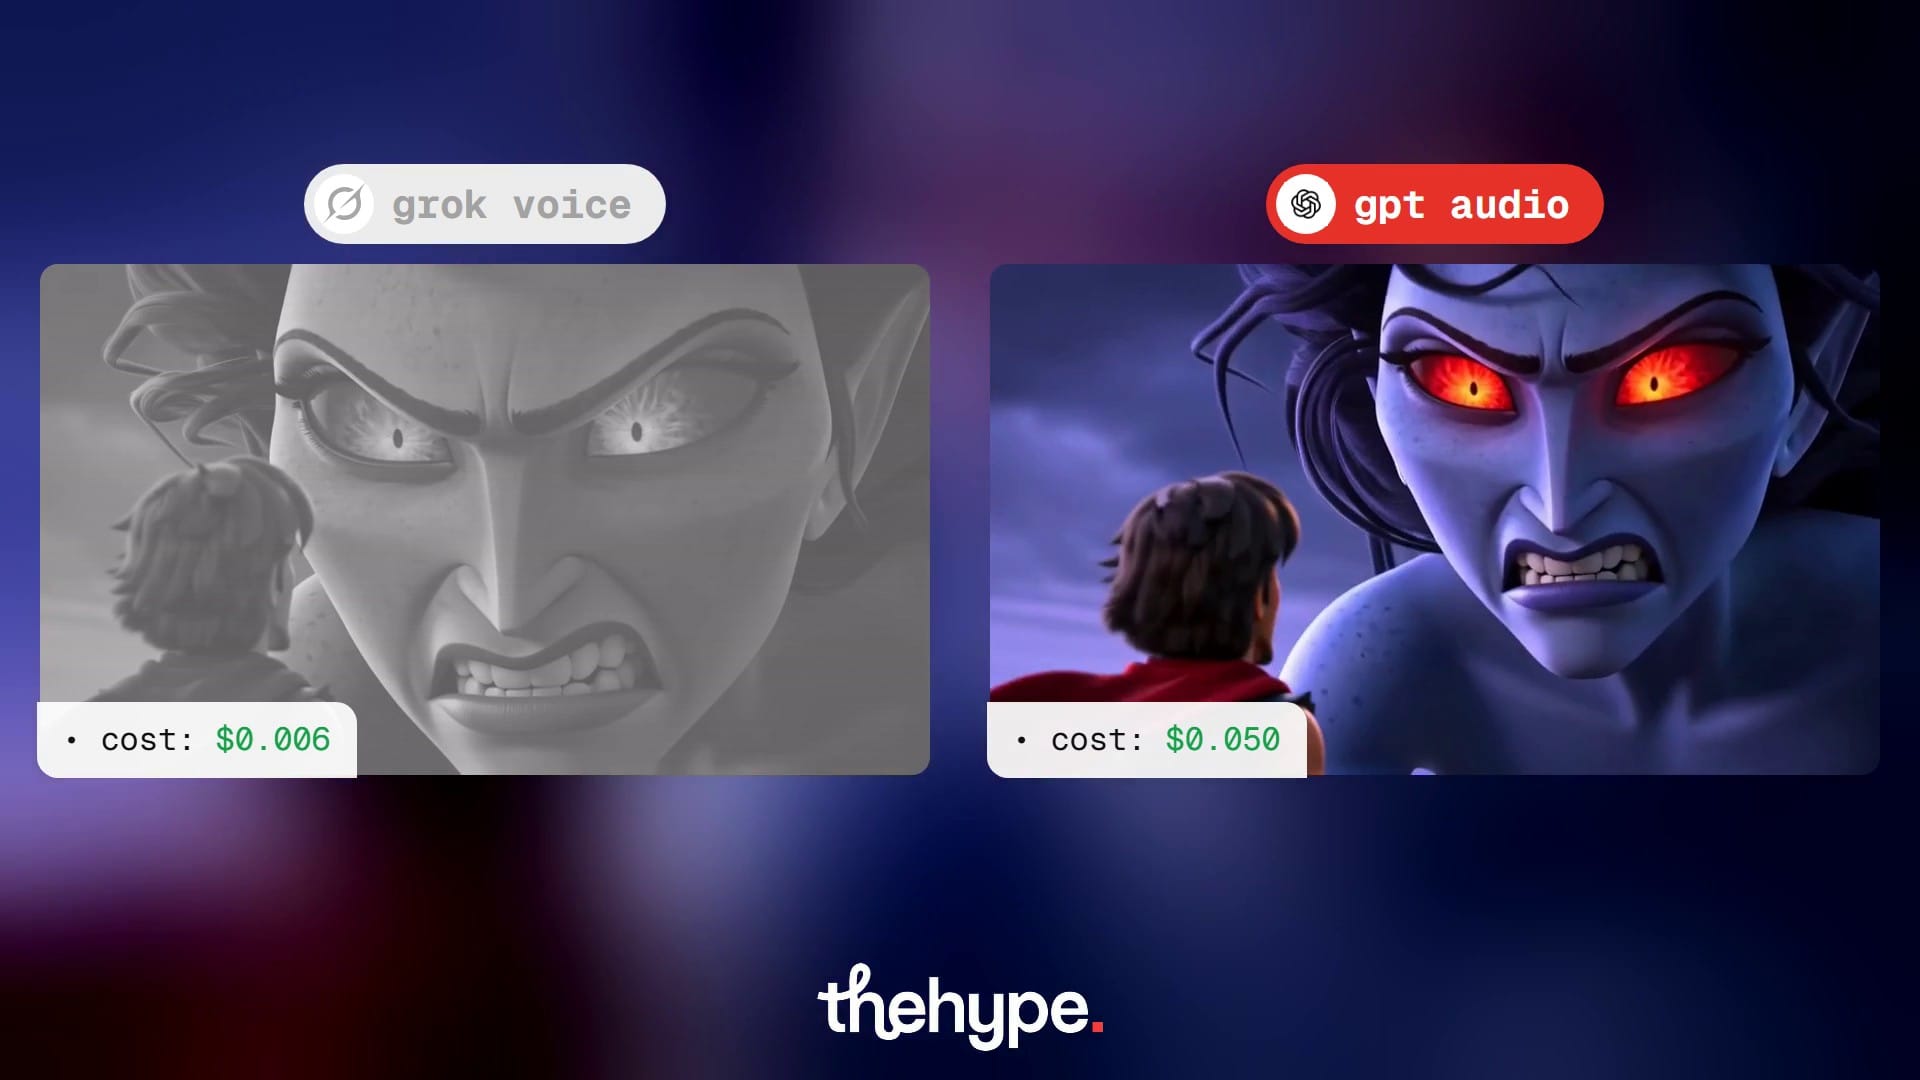
seedance first refused a prompt that named the original film's style, citing copyright, and charged nothing. the scene went through in a generic 3d cartoon style. for lip-sync, seedance got the dialogue track and three character stills:
High-quality stylized 3D animation, modern feature-film CGI look, same characters and style as the reference images: image 1 is the SAILOR, images 2 and 3 are the giant storm GODDESS. Night, stormy purple-blue sky, cracked stone platform at a cliff edge above a dark sea. 16:9.
The reference audio is the dialogue track. Lip-sync every line exactly to the reference audio: mouths move only while that character's voice is heard and stay closed in silence.

SHOT 1 [0.0-3.2s] Top-down view on the sailor on the cracked stone floor, looking up, confused, spreading his arms. He speaks his line from the audio (0.6-2.9s), lips synced.
SHOT 2 [3.2-8.0s] Wide shot: the tiny sailor on the platform, the giant goddess leaning over him, claws on the stone, hair swirling like smoke. She speaks coldly and contemptuously (3.7-7.8s), lips clearly synced to every word.
SHOT 3 [8.0-10.6s] Close-up of the goddess's face, red glowing eyes, she says her line through a sneer (8.2-9.9s), lips synced.
SHOT 4 [10.6-15.0s] Over-the-shoulder from behind the sailor, the goddess's enormous furious face fills the frame; she shouts her final line in rage (11.0-14.7s), mouth articulating each word, not just screaming.
grok gets emotion from tags inside the text. these are the exact lines we sent:
leo:     <higher-pitch>Eris?!</higher-pitch>
leo:     <emphasis>I don't understand!</emphasis>
celeste: [tsk] <soft>Don't play coy with me.</soft>
celeste: <lower-pitch>Maybe you can fool <emphasis>these</emphasis> people,</lower-pitch>
celeste: <soft>but I know <emphasis>who</emphasis> you are.</soft>
celeste: <build-intensity>You're a selfish, unprincipled <loud><emphasis>liar!</emphasis></loud></build-intensity>
gpt audio gets the plain text plus one system prompt per line that reads like a brief to a voice actor:
You are a voice actor. Read the user's text aloud exactly as written, word for word, adding nothing. Delivery:
ash:     a young adventurous man, genuinely confused and a bit scared, natural pace.
shimmer: a seductive, cold, contemptuous goddess villain, silky and menacing, natural pace, no long pauses.
shimmer: a goddess villain exploding in fury, loud furious shout, fast.
the red pill, the matrix
the scene is the mentor offering a blue and a red pill to a young man in a red armchair.
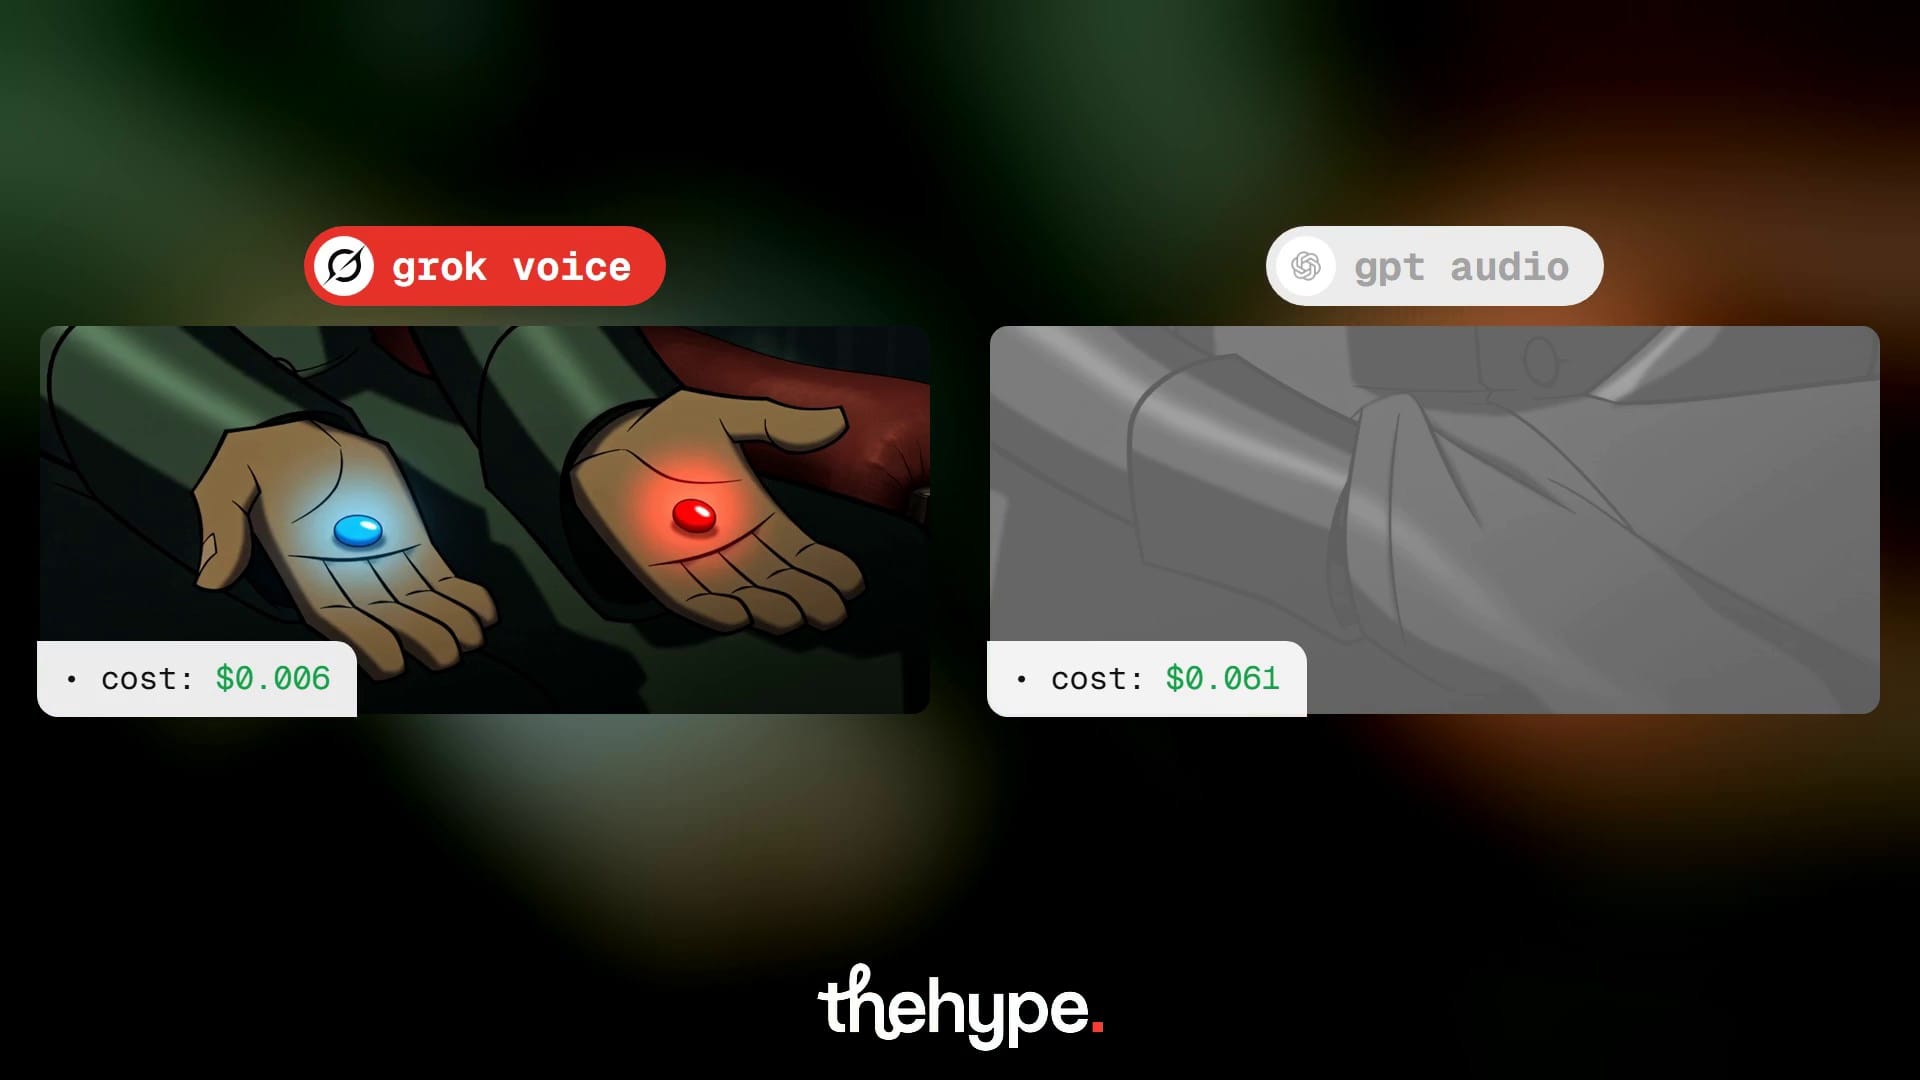
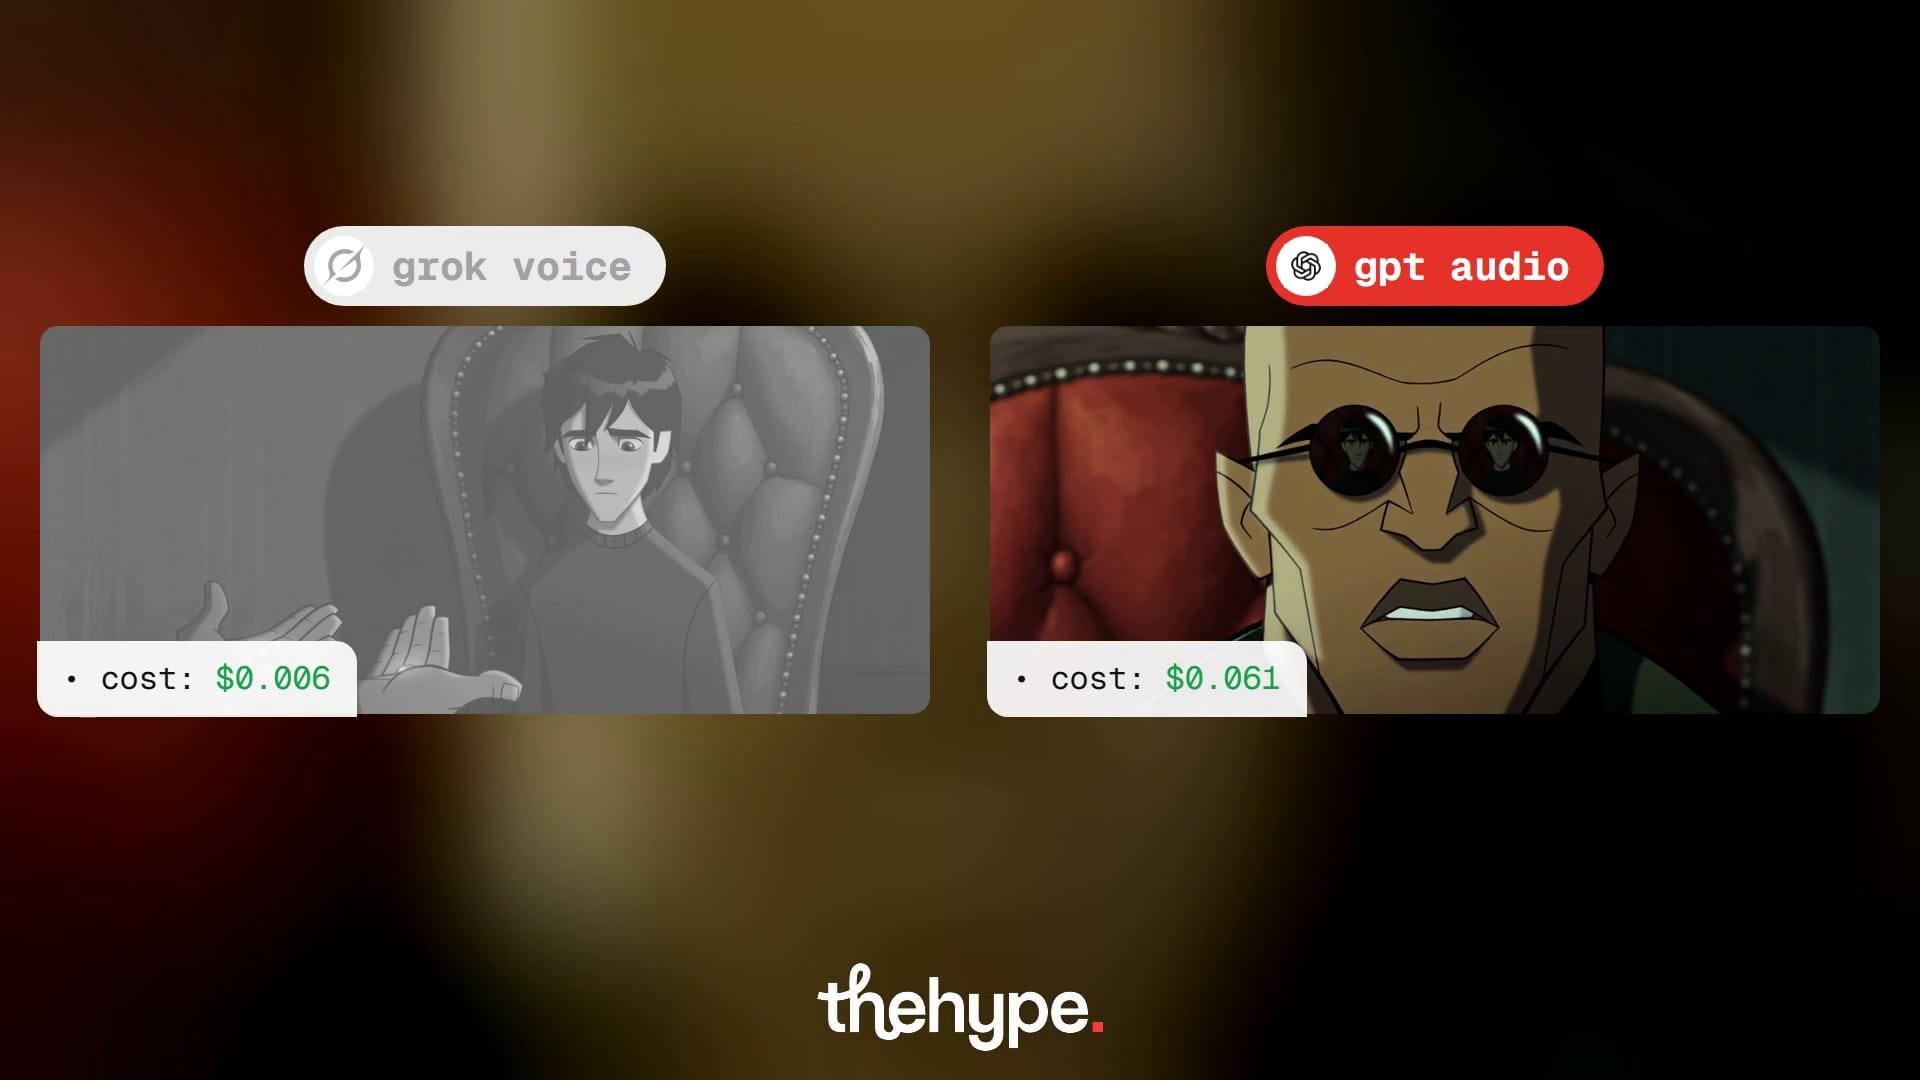
this video was generated silent in a 2d adventure-cartoon style, so the lips are not synced to either voice:
Hand-drawn 2D animation in the style of the 2003 animated film "Sinbad: Legend of the Seven Seas": bold clean ink outlines, stylized angular characters with expressive faces, painted backgrounds, rich cel-shading, cinematic adventure-cartoon look. Ultra-wide 21:9 frame. Setting: a dark old room, two deep red tufted leather armchairs, dim green-tinted light, deep shadows, single soft key light from the side.
Characters: MENTOR - tall bald dark-skinned man, small round black pince-nez sunglasses with no arms, long dark-green leather coat, calm and confident. YOUNG MAN - pale, short black hair, black sweater, sitting in the red armchair, tense and quiet.
Six static shots with hard cuts, locked-off camera, no camera movement:

SHOT 1 [0.0-1.4s] Tight close-up, low angle on the mentor's lap: his right hand slowly opens palm up, a small glossy BLUE capsule pill lies on the palm, faint blue glow.
SHOT 2 [1.4-4.2s] Extreme close-up of the mentor's face filling the frame from the forehead to the lips, red leather armchair edge blurred on the left. His round black lenses each show a tiny reflection of the young man sitting in the armchair. His lips move slowly as he speaks calmly.
SHOT 3 [4.2-5.8s] Medium close-up of the young man in the red armchair, framed on the right side of the frame, dark empty wall on the left. He stares forward, silent, barely blinking.
SHOT 4 [5.8-7.0s] Close-up of both of the mentor's hands held out side by side, palms up: a glossy RED capsule pill in the left hand, the BLUE pill in the right hand.
SHOT 5 [7.0-11.4s] Same extreme close-up of the mentor's face as shot 2. In the left lens the reflection of the young man looking at the red pill, in the right lens at the blue pill. His lips keep moving slowly as he speaks.
SHOT 6 [11.4-12.0s] Same medium close-up of the young man as shot 3, eyes lowered toward the pills, silent.

Silent video, no audio.
grok's lines for the mentor, voice zagan:
<lower-pitch>You take the blue pill</lower-pitch> [pause] and the story ends. <soft>You wake in your bed and you believe whatever you want to believe.</soft>
<lower-pitch>You take the red pill</lower-pitch> [pause] you stay in Wonderland, and I show you <emphasis>how deep</emphasis> the rabbit-hole goes.
[breath] Remember, [pause] all I am offering is the truth. <soft>Nothing more.</soft>
gpt audio, voice onyx, with this system prompt:
You are a voice actor. Read the user's text aloud exactly as written, word for word, adding nothing. Delivery: a deep, calm, confident, mysterious male mentor voice at a natural conversational pace, only short pauses at commas, no long pauses, quiet intensity, cinematic.gpt audio's first take ran 27s with "slow, deliberate pauses" in the prompt. "natural pace, short pauses" brought it to 20s.
our take
grok voice is about 9x cheaper for the same lines, and its tags give line-by-line control: a whisper here, a shout there. gpt audio takes direction like an actor, in plain words, but bills by the second of speech, so slow delivery costs more. for dubbing at volume, grok's per-character price wins.
sources
- grok text to speech, xai docs - the tts api and its speech tags
- gpt audio on openrouter - the model we called
- seedance 2.0 on openrouter - the video model for both scenes
- prompts, voice tracks and costs: our test, oct 14, 2026