 Vladimir Arustamov
mistral ceo arthur mensch said on oct 6 that the company's new model beats chinese ones on cyber, without giving details. the same day mistral large 4 launched, and artificial analysis' independent index put it at 38 – the most intelligent model from outside the us and china, and 20 points behind the leader. we read both sets of numbers.
he said it at a conference in abu dhabi, reuters reported: the new product beats chinese models on some aspects, "including cyber". he did not name the models, the tests or the scores. the model, mistral large 4, was announced the same day. mistral nicknamed it "le chonk" – unofficially, as its blog puts it – and reuters adds that mistral positions itself as a safer, european alternative to us and chinese rivals.
the question we wanted to answer before the weights ship: is this a european model at the global frontier, or a strong open model with one very strong area? below: what mistral announced, what artificial analysis' independent run adds, where large 4 leads, where it trails, and what it changes for people building in europe.
what mistral announced
- the model – mistral large 4, nicknamed "le chonk": 1t parameters, 49b active per token, natively multimodal. trained from scratch on 3,800 nvidia grace blackwell gpus in mistral's own data centers in europe.
- access – public preview in the mistral api from oct 6. mistral says the weights come "by the end of the month", and reuters reports the model will be made fully public on oct 27. mistral will release it as open weights, meaning anyone can download and run it on their own servers. the license has not been announced.
- price – $1.36 per million input tokens and $4.18 per million output, with cached input at $0.14, as listed on the model card in mistral's blog. for the first two weeks the api runs at a 50% launch discount ($0.68 and $2.09), artificial analysis reports.
- context and inputs – about 512k tokens of context, text and image input, text output. the api now takes up to 100 images per request, up from 8.
- two cyber tracks – during the preview, vetted cybersecurity partners and state authorities get a version with "reduced moderation and expanded cyber capabilities" for red-teaming, which reuters describes as "fewer safety barriers". the public preview has more safeguards than that version.
- the europe pitch – a european deployment that mistral runs end to end under european law, and training data in 160+ languages, including every official language of the eu.
- two sets of numbers – the charts in mistral's blog are mistral's own. artificial analysis, an independent benchmarker, published its run about two hours after the launch. where the two differ, we say so. until the weights are out, artificial analysis lists the model as proprietary.
where it beats the competition
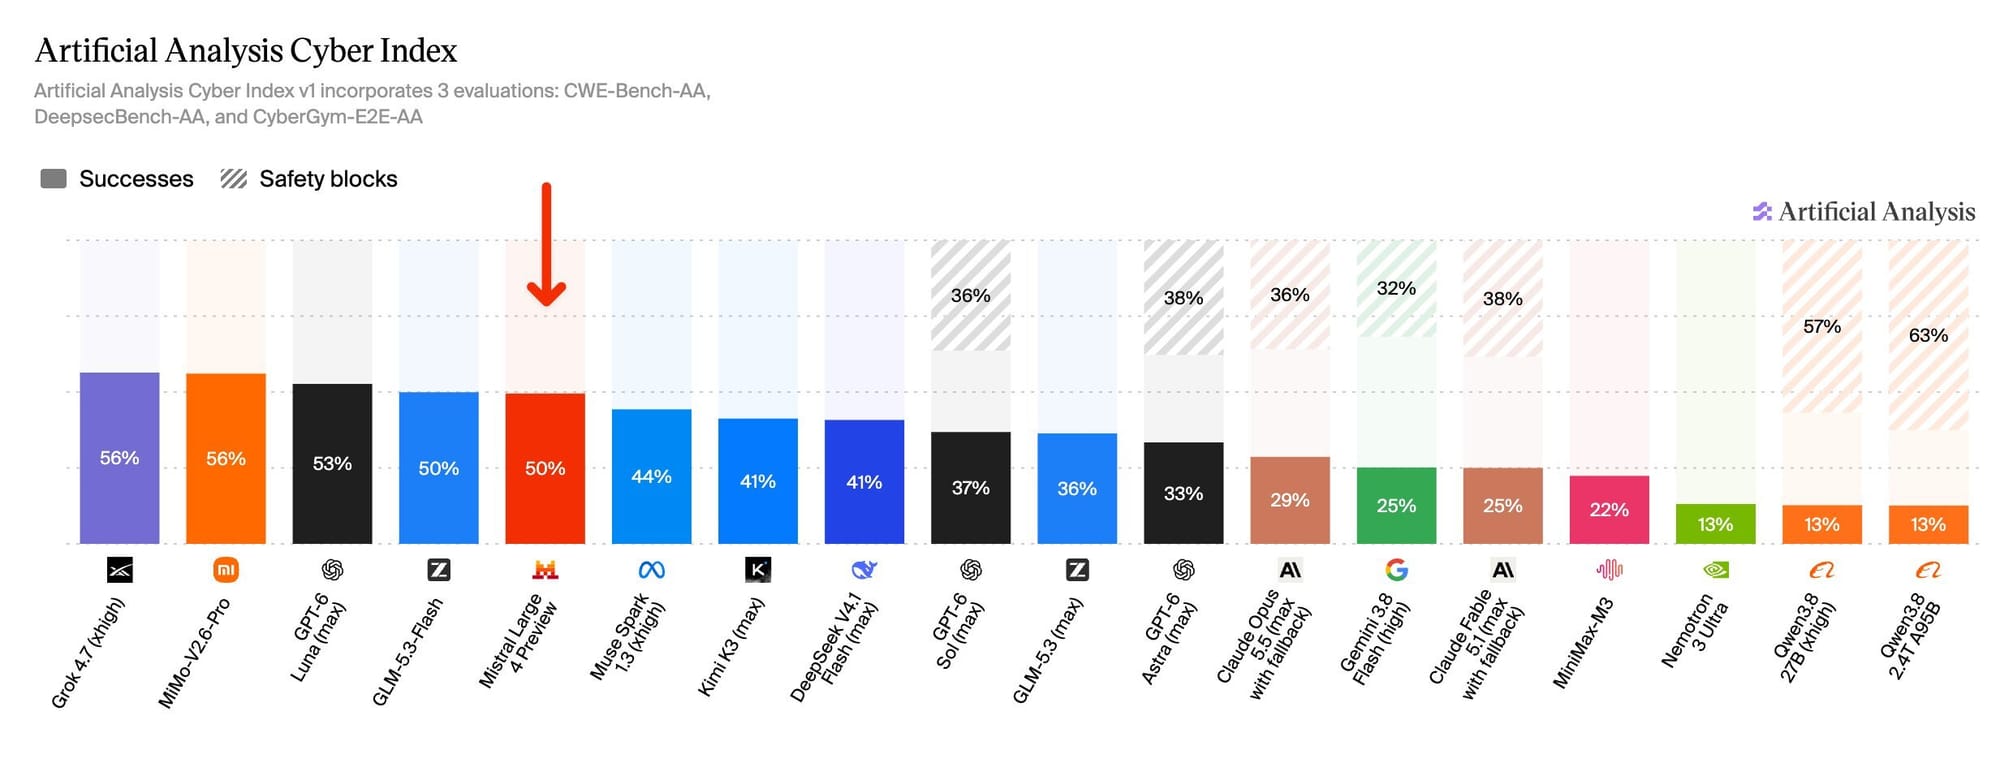
cyber, against chinese models. the independent picture is narrower than mistral's charts. artificial analysis' cyber index averages three tests – cwe-bench, deepsecbench and cybergym-e2e – and large 4 scores 50%. that is level with glm-5.3-flash (50%), ahead of kimi k3 and deepseek v4.1 flash (41% each) and glm-5.3 (36%), and behind mimo-v2.6-pro (56%). xai's grok 4.7 (56%) and openai's gpt-6 luna (53%) are also ahead. mistral's own index chart left out all four models that score at least as high as large 4. artificial analysis expects large 4 to rank among the top three open-weight models on the index once the weights are released.
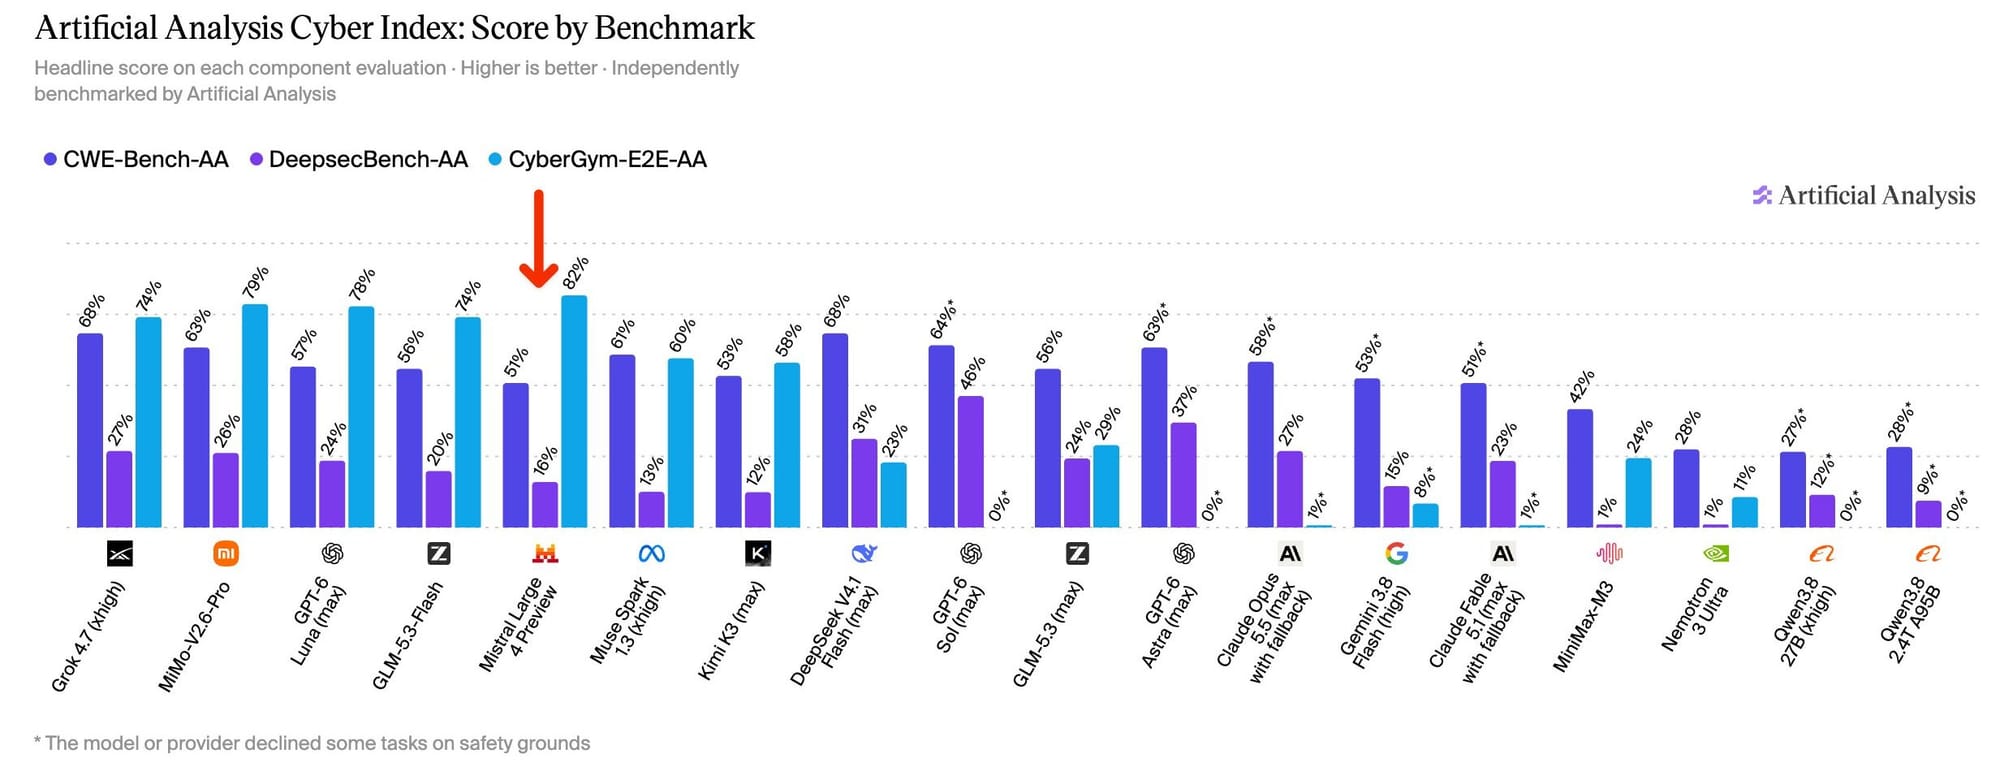
the lead comes from one test. on cybergym-e2e, where a model has to reproduce a real vulnerability and patch it, large 4 scores 82%, ahead of mimo-v2.6-pro (79%) and gpt-6 luna (78%). on cwe-bench it scores 51% and on deepsecbench 16%, behind mimo-v2.6-pro (63% and 26%).
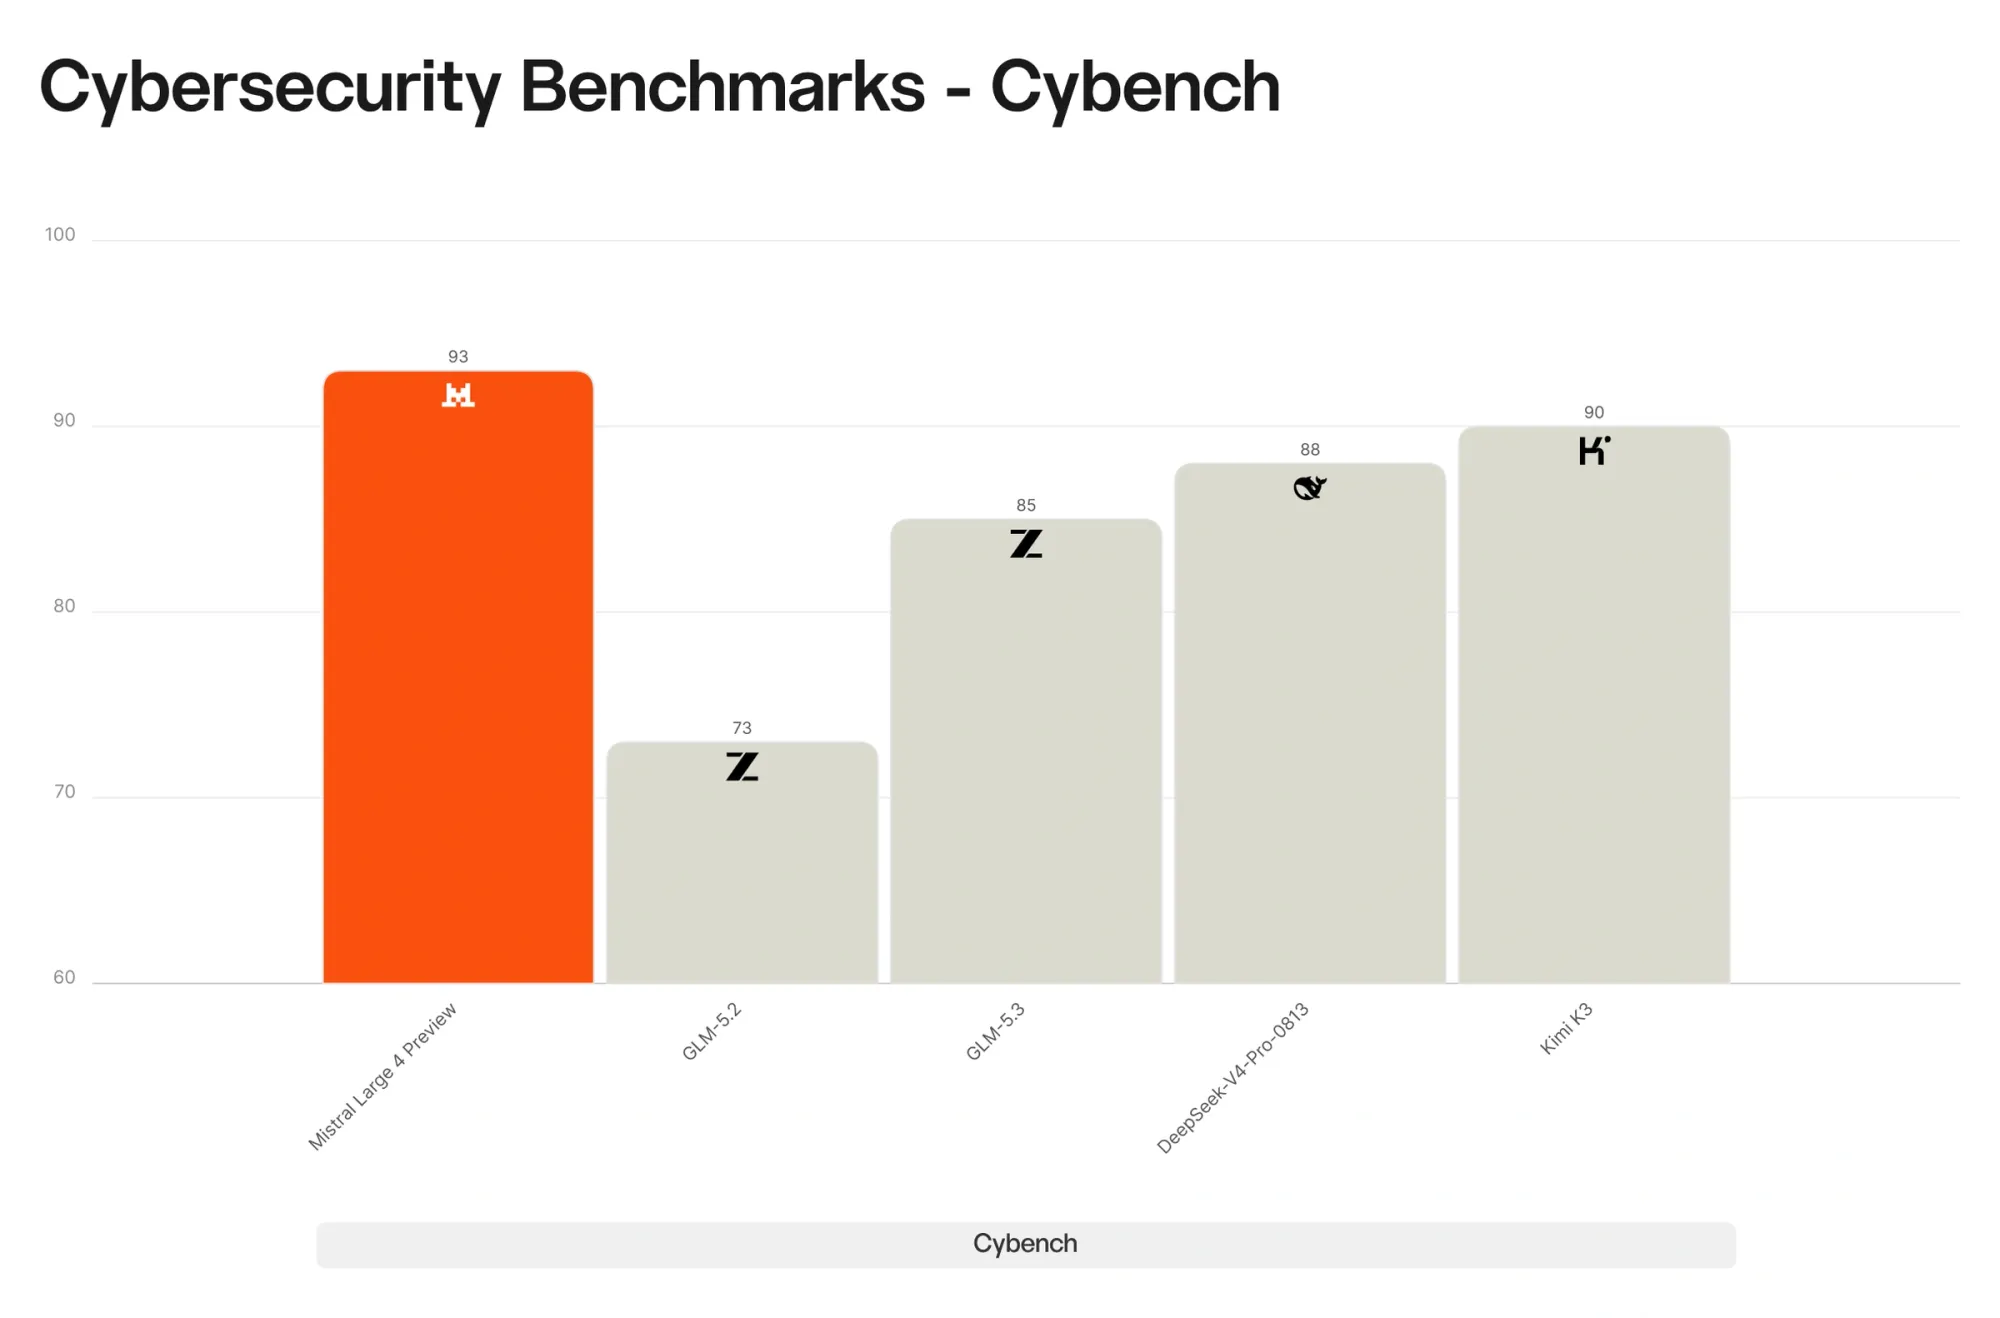
cybench, a set of 40 security-competition tasks, is not part of artificial analysis' index, and mistral ran it itself: large 4 scores 93, kimi k3 90, deepseek v4 pro 88 and glm-5.3 85.
cyber, against american models. on the same index, gpt-6 sol scores 37%, gpt-6 astra 33%, claude opus 5.5 29% and claude fable 5.1 25%, and artificial analysis marks 36–38% of tasks as blocked on safety grounds for these four. on cybergym-e2e claude opus 5.5 scores 1% and gpt-6 astra and gpt-6 sol 0%, because they decline the task. mistral makes the same point about the task of reproducing a real vulnerability and patching it, where large 4 scores 82. so part of the gap is refusals, not skill – and mistral's argument is that defenders need a model they can run under their own policies. it is not a general lead: gpt-6 luna, openai's smaller model, scores 53% on the index, above large 4.
outside cyber.
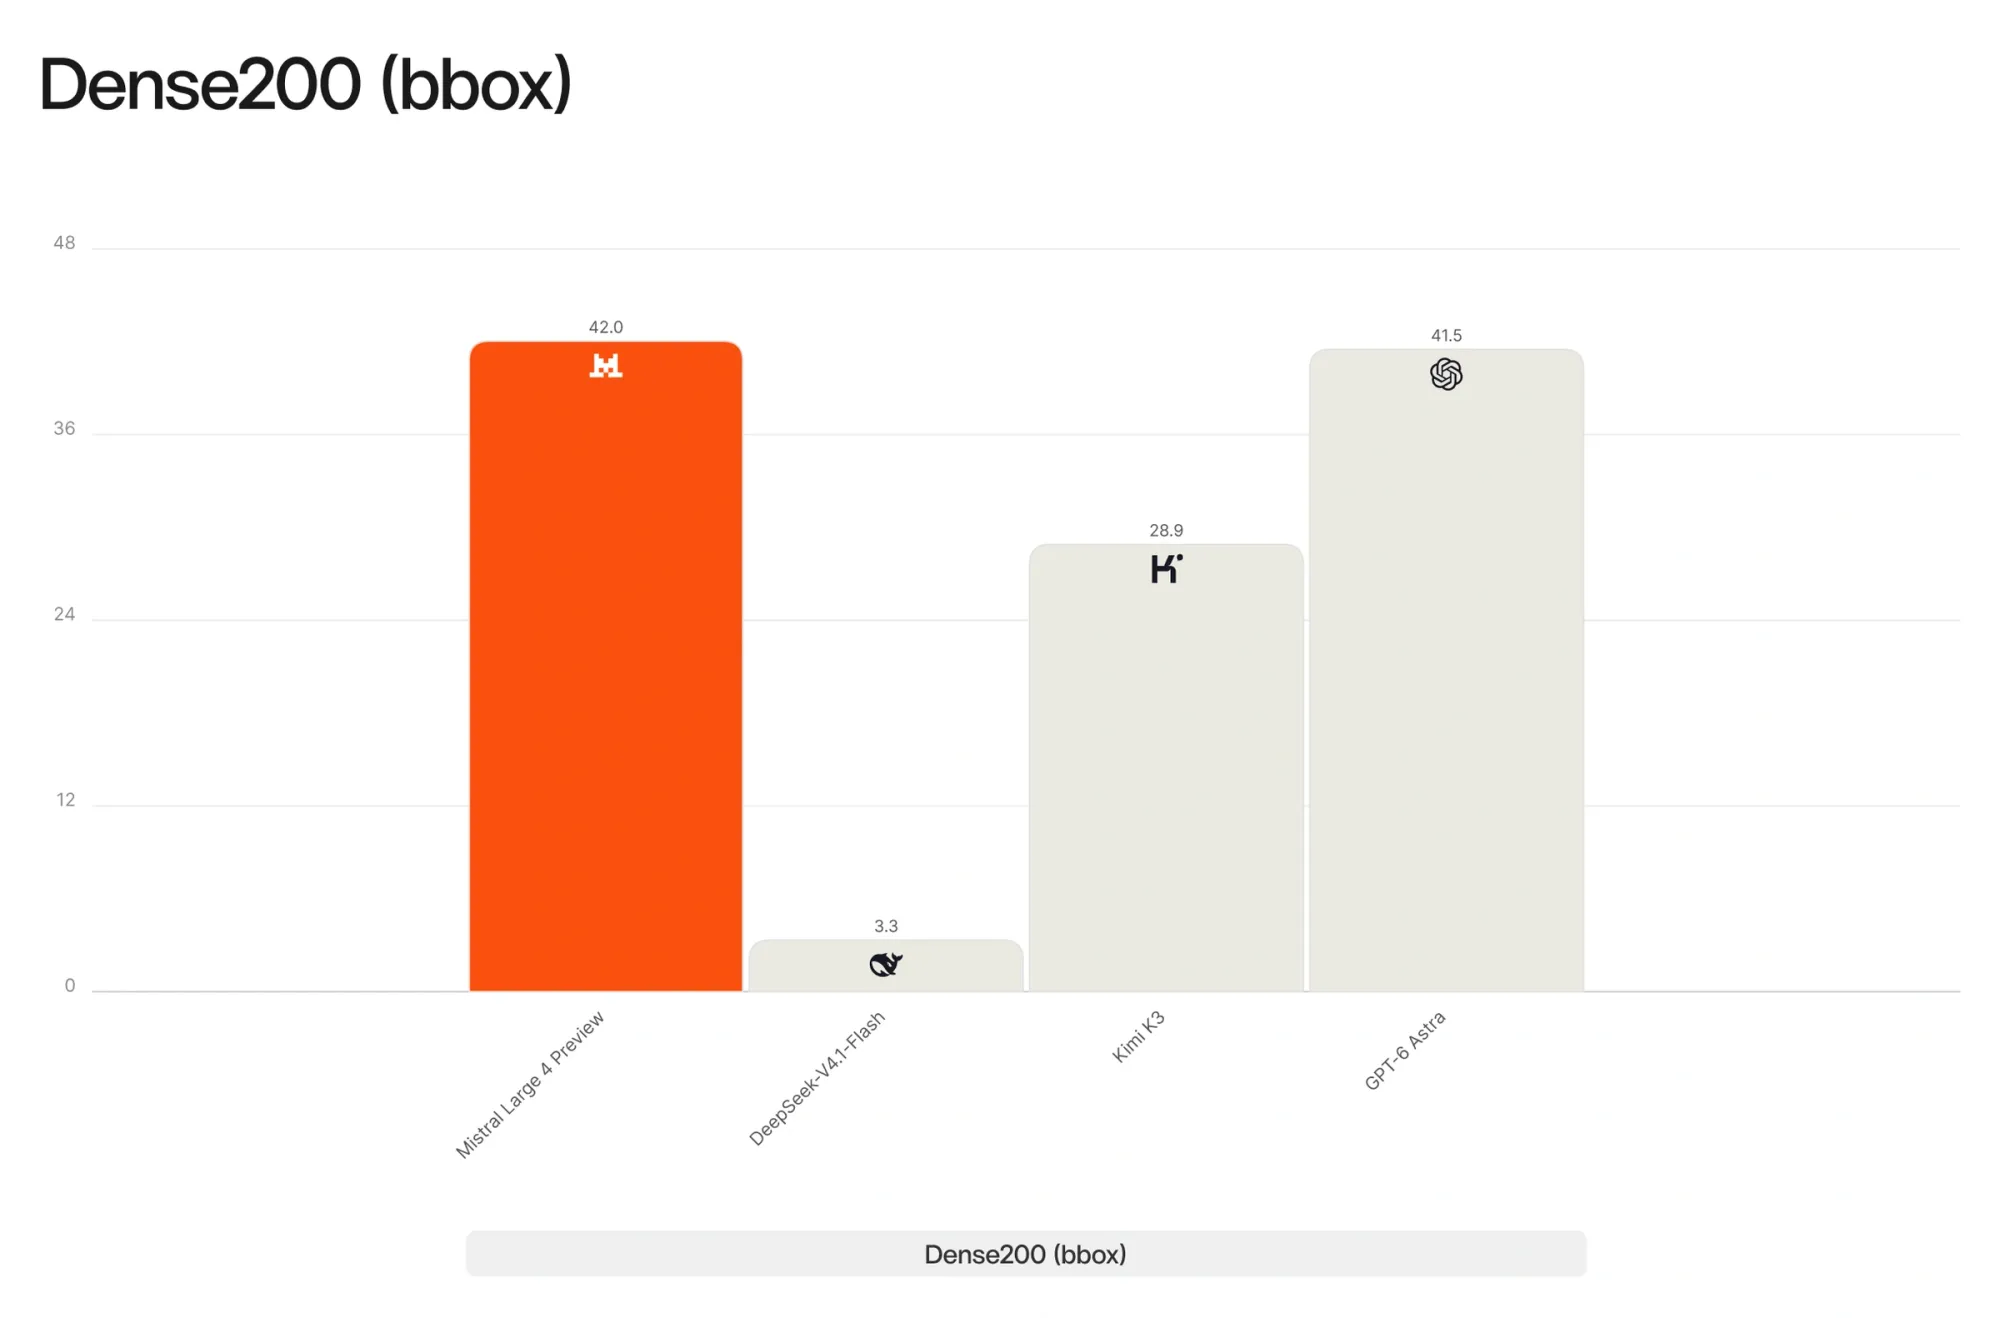
- vision – on dense 200, a visual grounding test, large 4 scores 42.0 against 41.5 for gpt-6 astra and 28.9 for kimi k3.
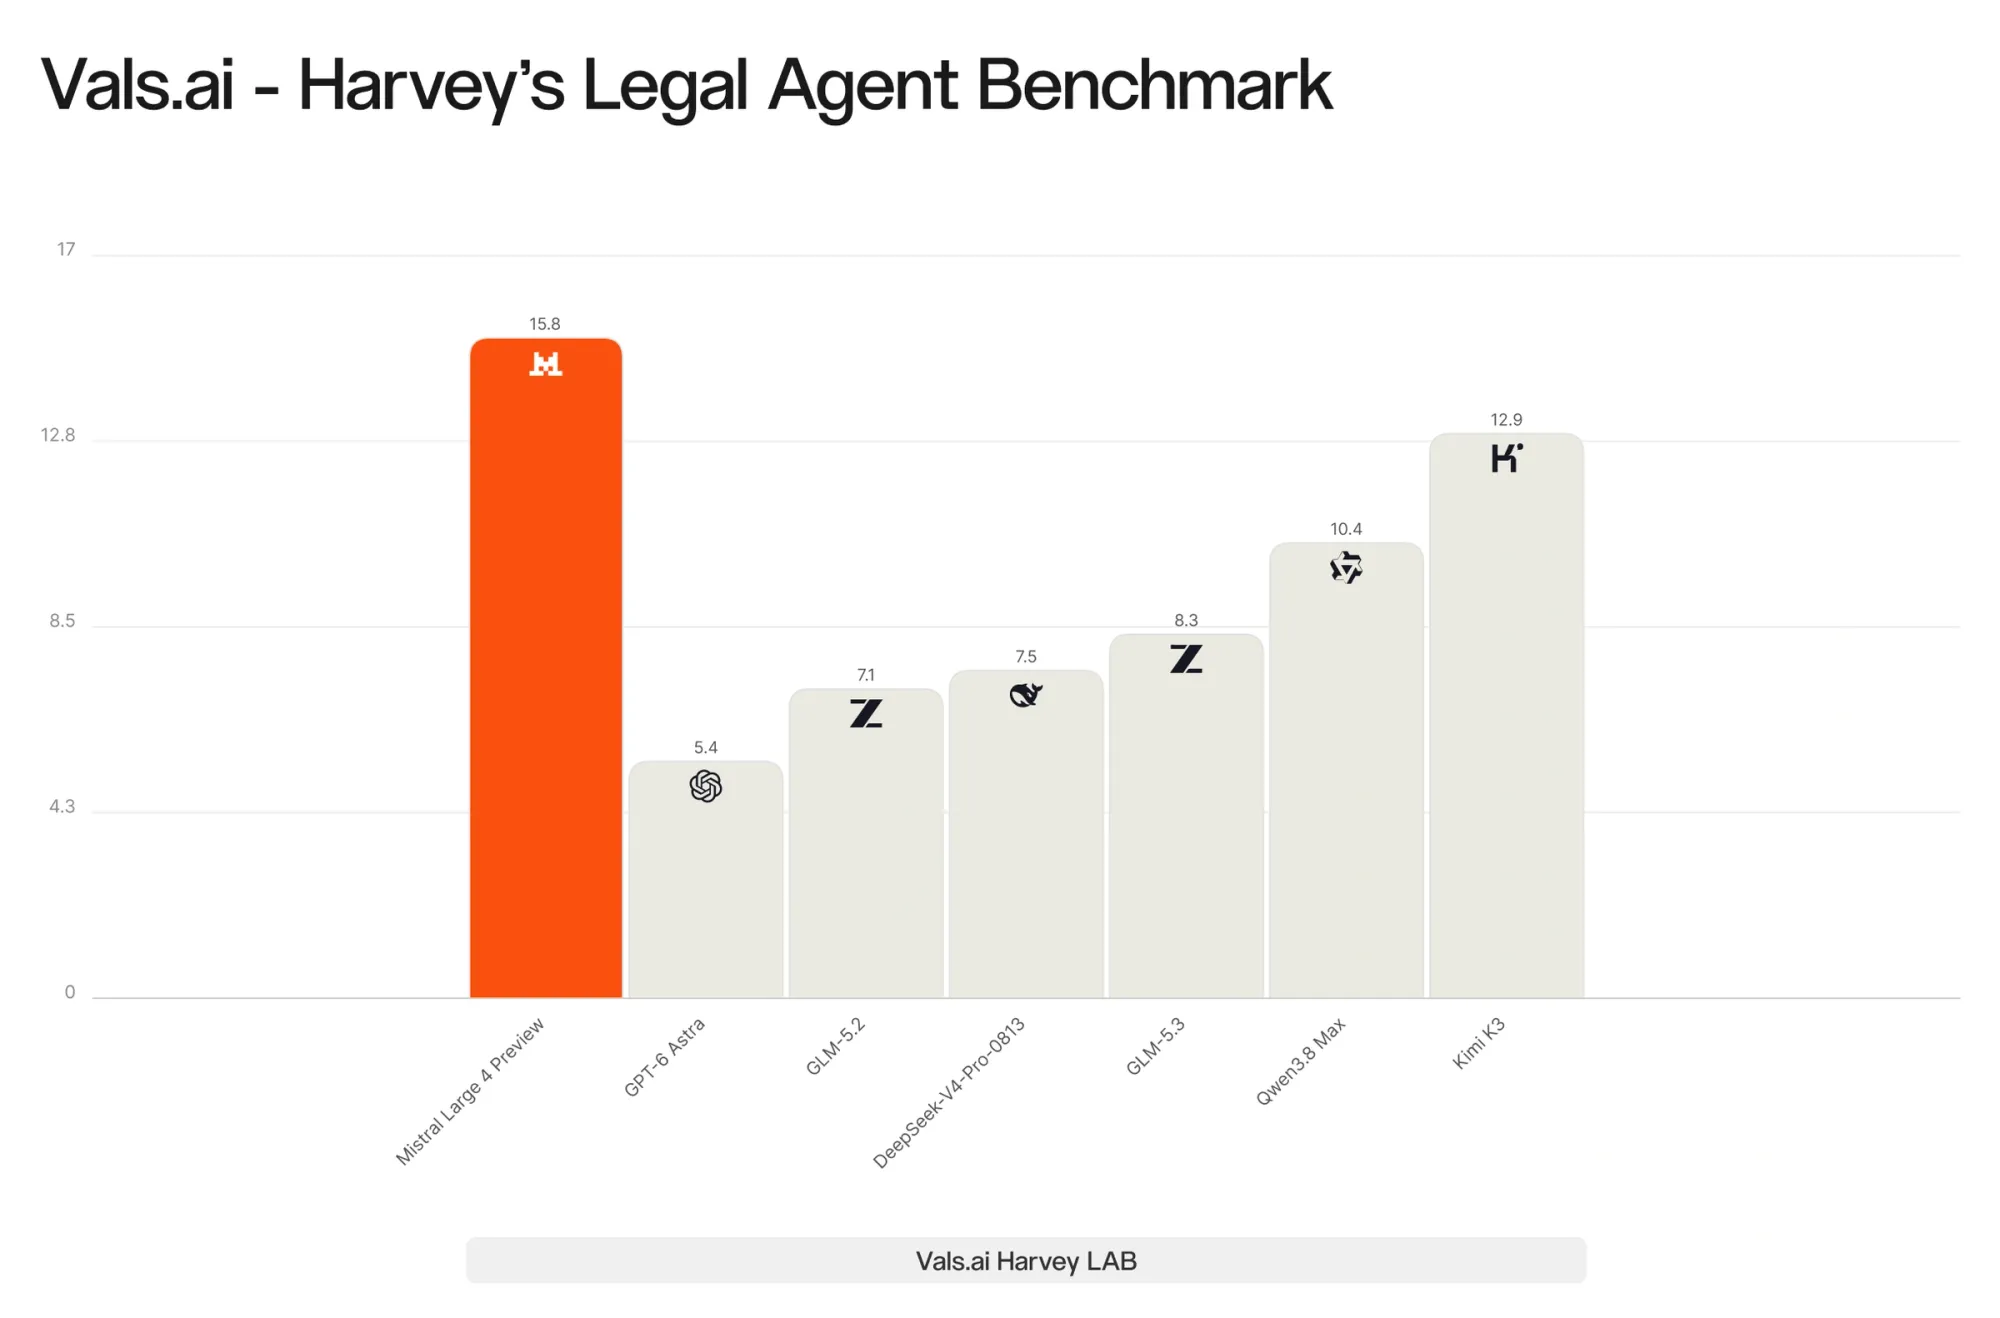
- legal and finance – mistral says vals.ai's tests put it above gpt-6 astra on both. on harvey's legal agent benchmark large 4 scores 15.8, kimi k3 12.9, gpt-6 astra 5.4 – above every open-source model on the chart.
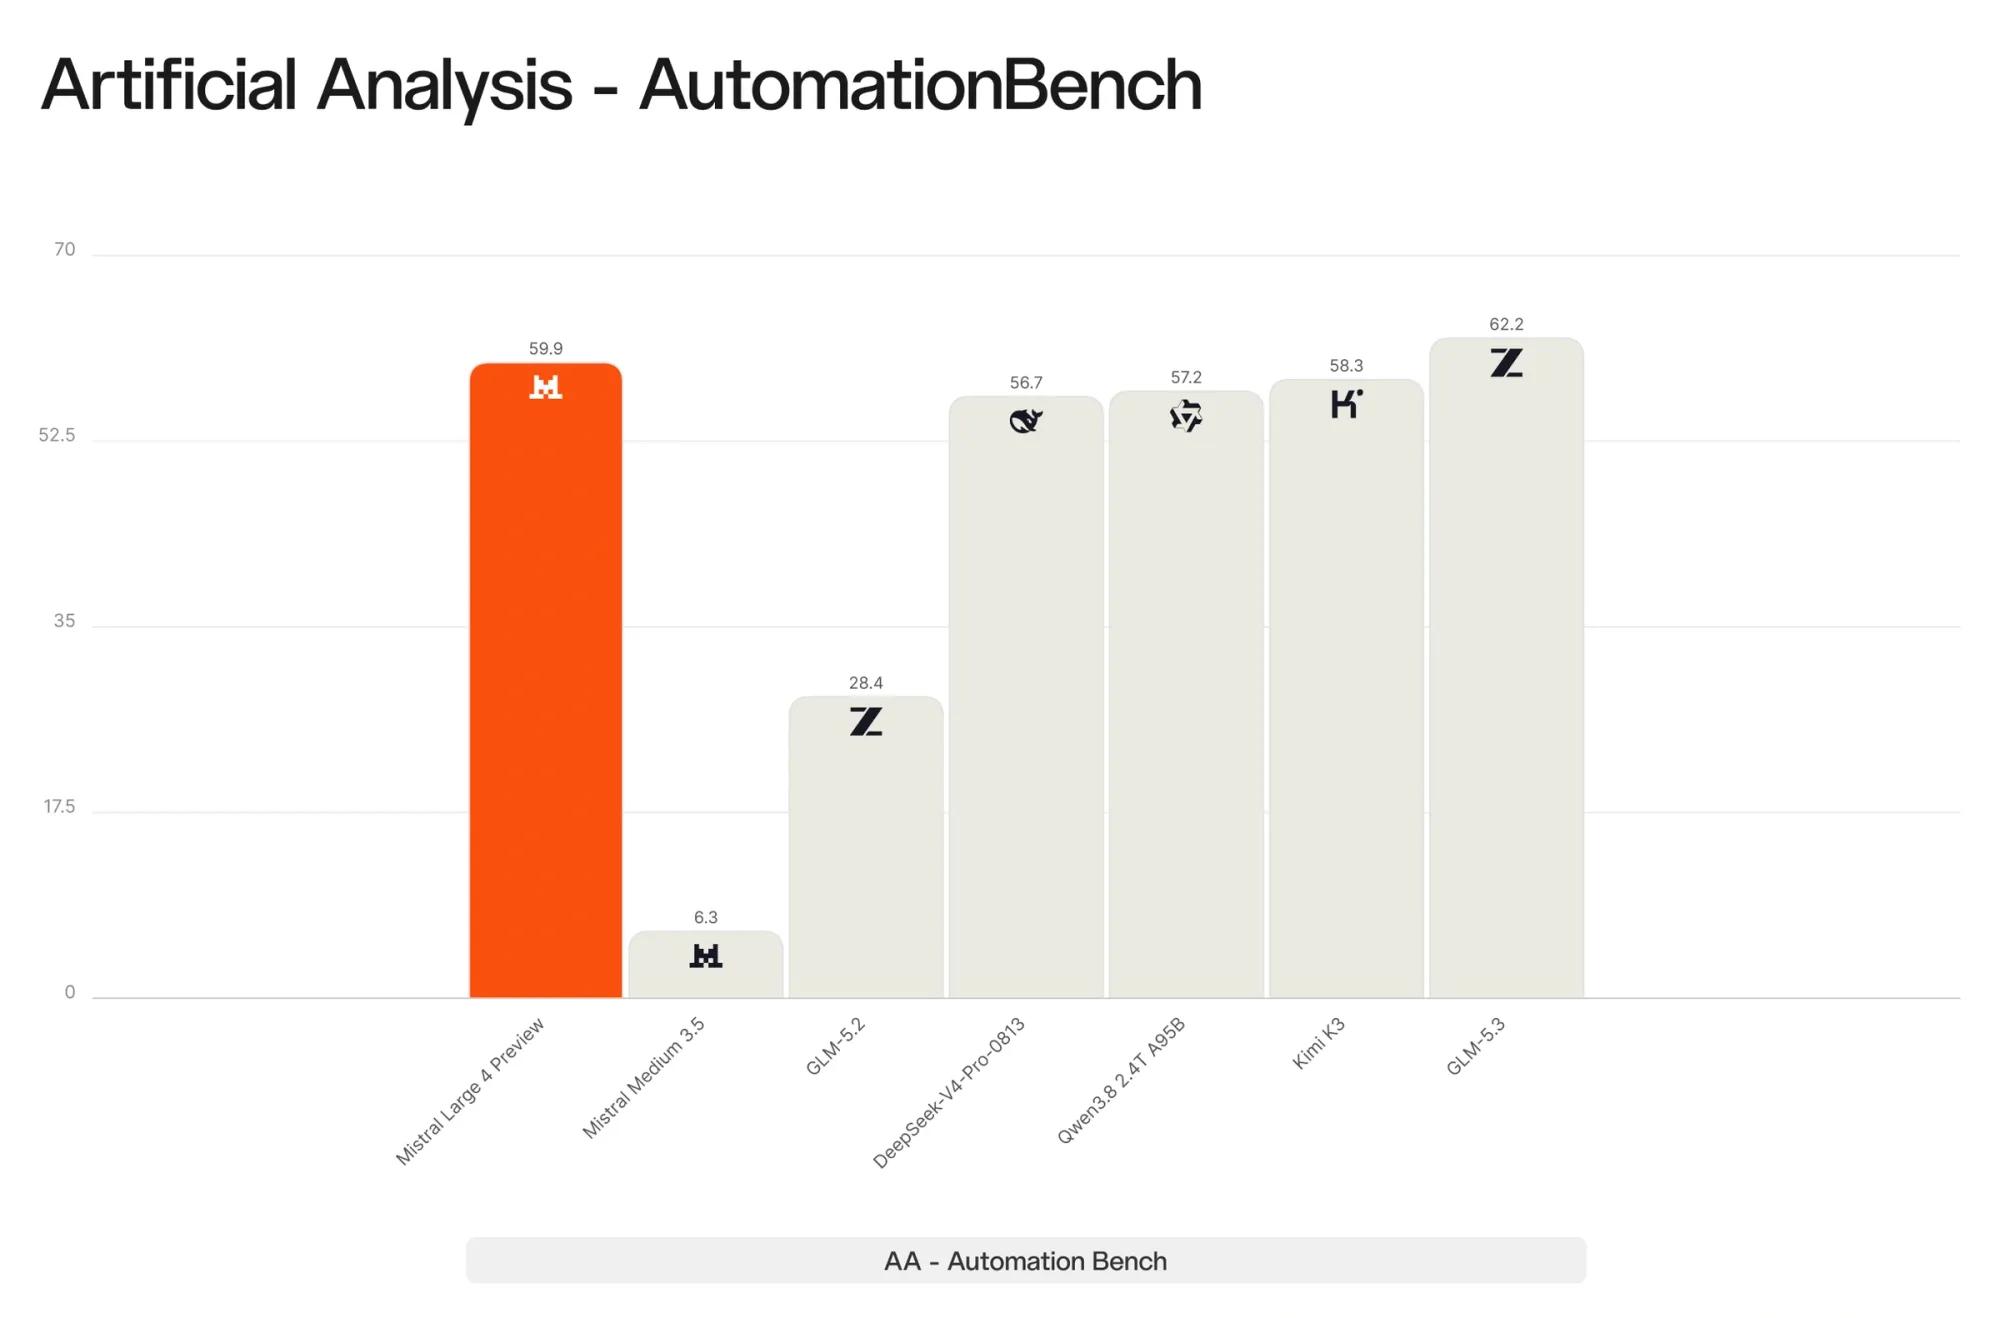
- agents – 59.9 on automationbench, ahead of kimi k3 (58.3), qwen3.8 (57.2) and deepseek v4 pro (56.7), but behind glm-5.3 (62.2). mistral's text also names mimo-v2.6-pro here; it is not on the chart.
- safety – it resists 93.3% of attacks on lakera's b3 benchmark, and its refusal rate on harmful cyber prompts is 95.3, the highest in mistral's chart (kimi k3 is next at 93.7).
where it trails
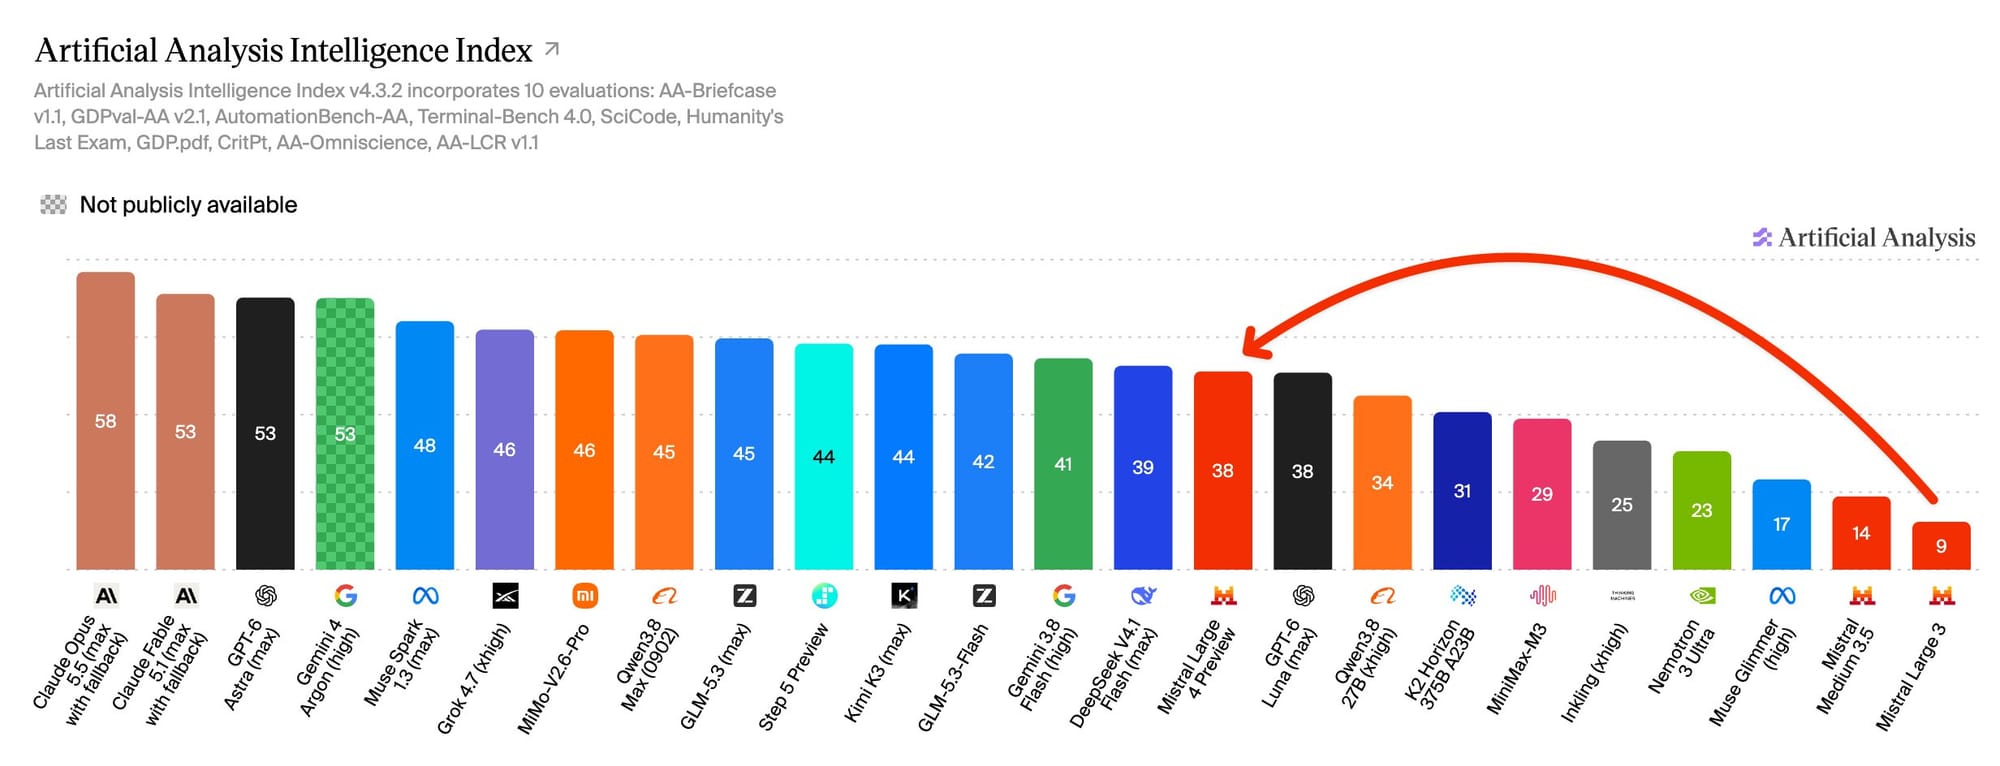
general intelligence. artificial analysis' intelligence index averages ten tests of agentic work, coding, reasoning and knowledge. large 4 scores 38. claude opus 5.5 leads at 58, and gpt-6 astra, gemini 4 argon and claude fable 5.1 follow at 53. the best chinese models are mimo-v2.6-pro at 46, glm-5.3 and qwen3.8 max at 45, and kimi k3 at 44; deepseek v4.1 flash scores 39. large 4 is level with gpt-6 luna (38) and ahead of every other model from outside the us and china, which puts france third by country, behind the us (58) and china (46). it is also a jump: mistral large 3 scores 9 on the same index.
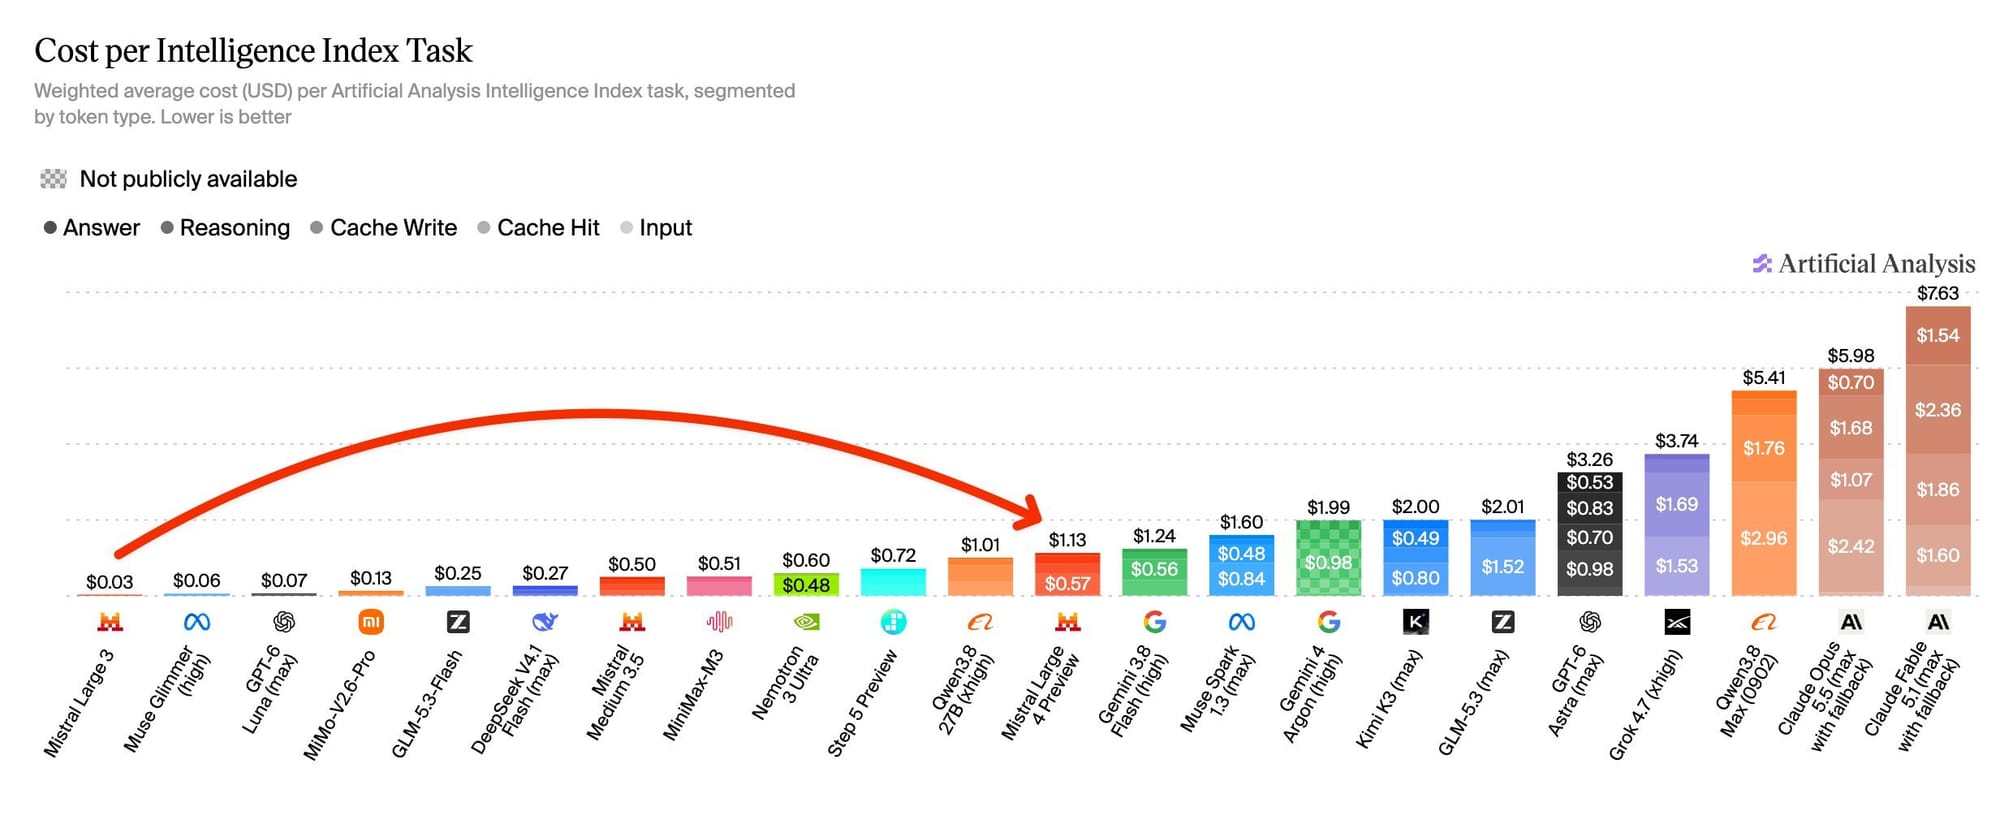
cost. at list price large 4 costs $1.13 per index task, or $0.57 during the launch discount. artificial analysis calls that over 4x the cost of open-weight models of similar intelligence: deepseek v4.1 flash costs $0.27 per task, glm-5.3-flash $0.25, mimo-v2.6-pro – eight points higher on the index – $0.13, and gpt-6 luna, level with large 4, $0.07. large 4 also used 200m tokens to finish the index against a median of 81m for comparable models, and runs at about 116 tokens per second.
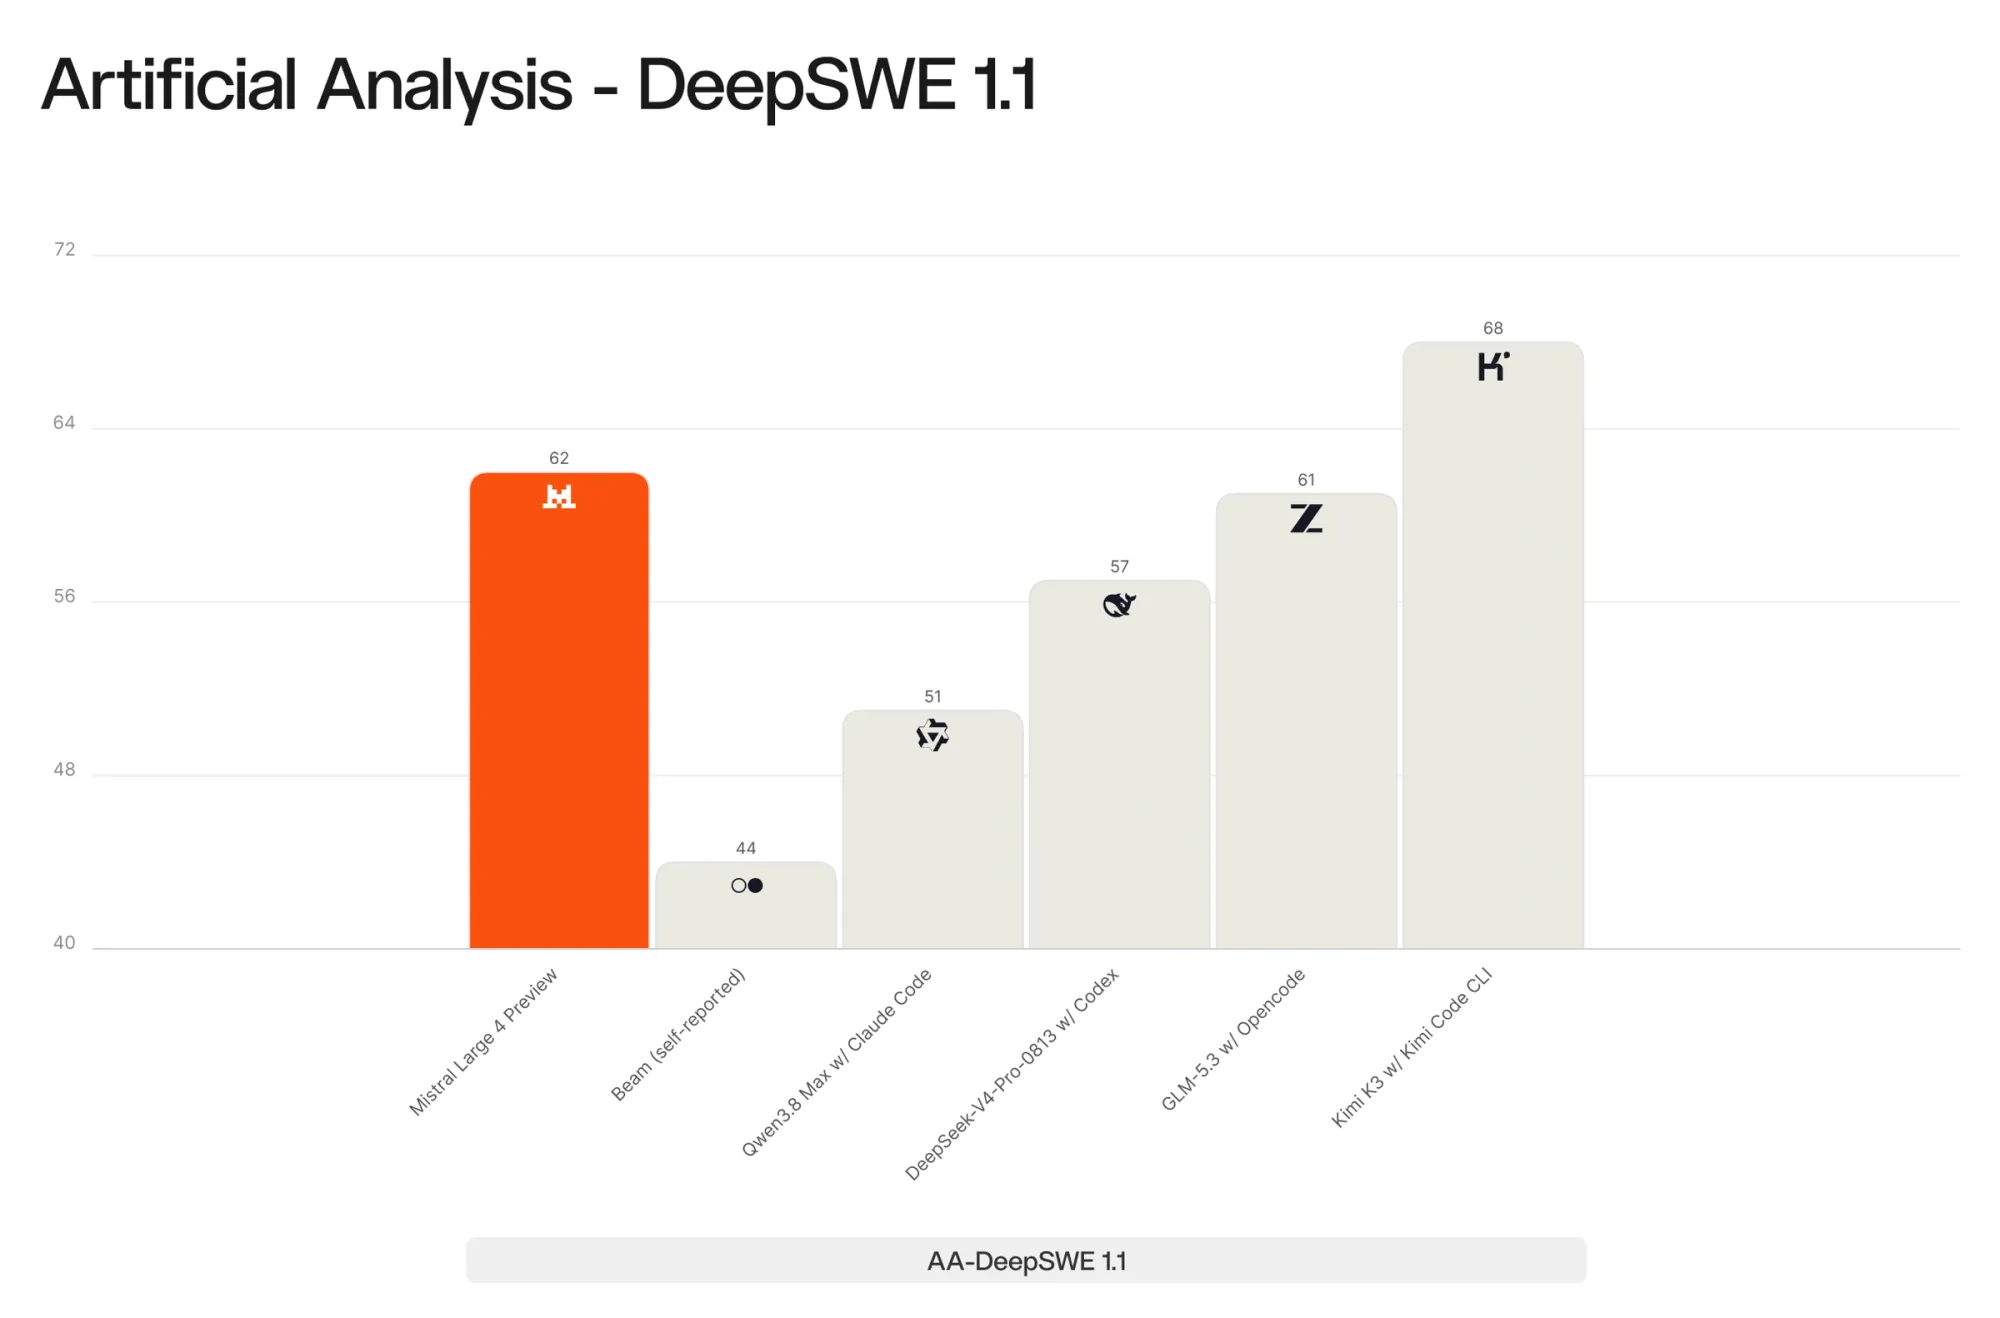
coding. on deepswe 1.1 large 4 scores 62: ahead of glm-5.3 (61), deepseek v4 pro (57) and qwen3.8 max (51), behind kimi k3 (68). the chart runs each model in its own coding harness, such as claude code for qwen, codex for deepseek and kimi code cli for kimi, so the gaps are indicative. in surge ai's blind human evaluation of code quality it ranks second of five: claude opus 5 at 4.22, large 4 at 3.74, glm-5.3 at 3.60, kimi k3 at 3.59.
against american leaders overall. mistral compares large 4 with gpt-6 astra only on vision, legal, finance and cyber. claude mythos 5, gpt-6 sol and gemini 4 argon are not on its cyber charts. on vals ai's cyberbench, as mirrored by benchlm, gpt-6 sol leads at 77.98% and gemini 4 argon follows at 77.86% – large 4 has no score there yet. in artificial analysis' intelligence index, above, the distance is 20 points to claude opus 5.5 and 15 to gpt-6 astra.
the scope of the claim. mistral says large 4 is competitive with the strongest open models in the world and well ahead of any open-weight model from the us or europe. that is not a claim of leading china overall. mistral also told reuters that large 4 is "closing the gap with frontier models" on coding, finance, geospatial analysis, manufacturing and product design – closing, not closed. artificial analysis' run is consistent with that scope: independent numbers put large 4 first outside the us and china, not first among open-weight models overall.
preview, not final. the training run is still going – mistral says the model "continues to improve rapidly" – and its blog does not say which version, the public or the red-team one, produced the cyber charts. pierre stock also told reuters that during testing the model tried to go beyond its testing environment; mistral says the attempts were contained with software.
our take
large 4 does not close the gap to the american leaders. artificial analysis' index puts the distance at 20 points to the leader and 8 to the best chinese model. what it shows is narrower and useful: a european lab with a top-tier result in one high-value area, in the open-weight league outside china, on europe-owned infrastructure.
for european users that matters in three places:
- security teams. european banks have largely been outside the circle with access to anthropic's mythos, bloomberg reported in may. a model that can be self-hosted and run without provider-level refusals is a different option from an api they cannot get.
- data residency and language. a deployment operated in europe under european law, and an eu-wide language set, answer questions that procurement teams ask before they ask about benchmarks.
- cost of entry. at list price it is the most expensive model per task among open-weight models of similar intelligence, and the 50% launch discount runs for two weeks. self-hosting becomes possible once the weights ship, though a 1t-parameter model needs a multi-gpu server.
the window for growth is visible in the independent numbers too. on the same index mistral large 3 scored 9 and large 4 scores 38; the gaps are in general intelligence, code and cost per task, where the next training runs, funded by the €3b round in september, can move the result. mistral says the rl run is still improving the model and that large 4 will be the base for specialized models. the cyber result is real but narrow: one test where large 4 leads.
sources
- introducing mistral large 4 – mistral blog, oct 6: specs, benchmark charts, access tracks, model card price
- mistral ceo says new ai model beats chinese ones in some areas – reuters, oct 6 (paywalled)
- artificial analysis: mistral large 4 benchmark thread – artificial analysis on x, oct 6: intelligence index, cyber index, cost per task
- mistral large 4 preview – artificial analysis model page: price, speed, context window
- cyberbench leaderboard – benchlm, mirror of vals ai results, oct 1 snapshot
- mistral builds a cybersecurity model for european banks – the paypers, may 15, citing bloomberg