 Felix Laurent
Moonshot AI released Kimi K3.1 Pro on October 23. It is a post-trained version of Kimi K3 with the same 2.8T-parameter base. API prices are 33% lower than K3: $2 per million input tokens and $10 per million output tokens. On Moonshot's own chart the model leads 6 of 14 benchmarks, and open weights are promised by November 4.
What Moonshot announced
Kimi K3.1 Pro is a mixture-of-experts model with 2.8T total and 104B active parameters. It keeps K3's 1M-token context window and is multimodal. Moonshot says it spent much more post-training compute than on K3 and ran reinforcement learning across hundreds of domains.
The company lists four areas where the model improved. It builds whole game projects in Unreal, Unity and Godot. It does parametric 3D modeling in Blender and CAD tools. It is more reliable on finance work. It also matches the strongest closed models on coding, agentic and knowledge tests, by Moonshot's account.
Two versions shipped. K3.1 Pro is the standard model, and K3.1 Pro Highspeed runs 2–3x faster at double the price. Both are live on Kimi.ai, the Kimi apps, Kimi Work, Kimi Code and the Kimi API under the IDs kimi-k3.1-pro and kimi-k3.1-pro-highspeed.
Kimi K3.1 Pro API pricing: a third cheaper than K3
Moonshot published the new prices on its API platform the same day. The table compares them with K3, per million tokens.
| Model | Input | Output | Cached input |
|---|---|---|---|
| Kimi K3.1 Pro | $2.00 | $10.00 | $0.20 |
| Kimi K3.1 Pro Highspeed | $4.00 | $20.00 | $0.20 |
| Kimi K3 | $3.00 | $15.00 | $0.30 |
Input and output both drop by 33% against K3. Cache writes are billed by time-to-live: $2 per million tokens for 5 minutes and $4 for one hour on K3.1 Pro.
Moonshot also charted cost per task on Terminal-Bench 4.0. Read off that chart, K3.1 Pro at max effort scores about 66% for roughly $5.3 per task. Claude Opus 5.5 scores about 65% for roughly $14.3, which makes Kimi about 2.7x cheaper per task. Moonshot says the other models' cost and score come from tbench.ai.
Kimi K3.1 Pro benchmarks: where it leads
Moonshot's overview chart pits K3.1 Pro against Claude Opus 5.5, Claude Fable 5.1, GPT-6 Astra, GLM-5.3 and DeepSeek V4.1 Flash. The company notes that all models ran at max thinking effort. Many rival scores are cited from their own blogs and leaderboards, not re-run by Moonshot.
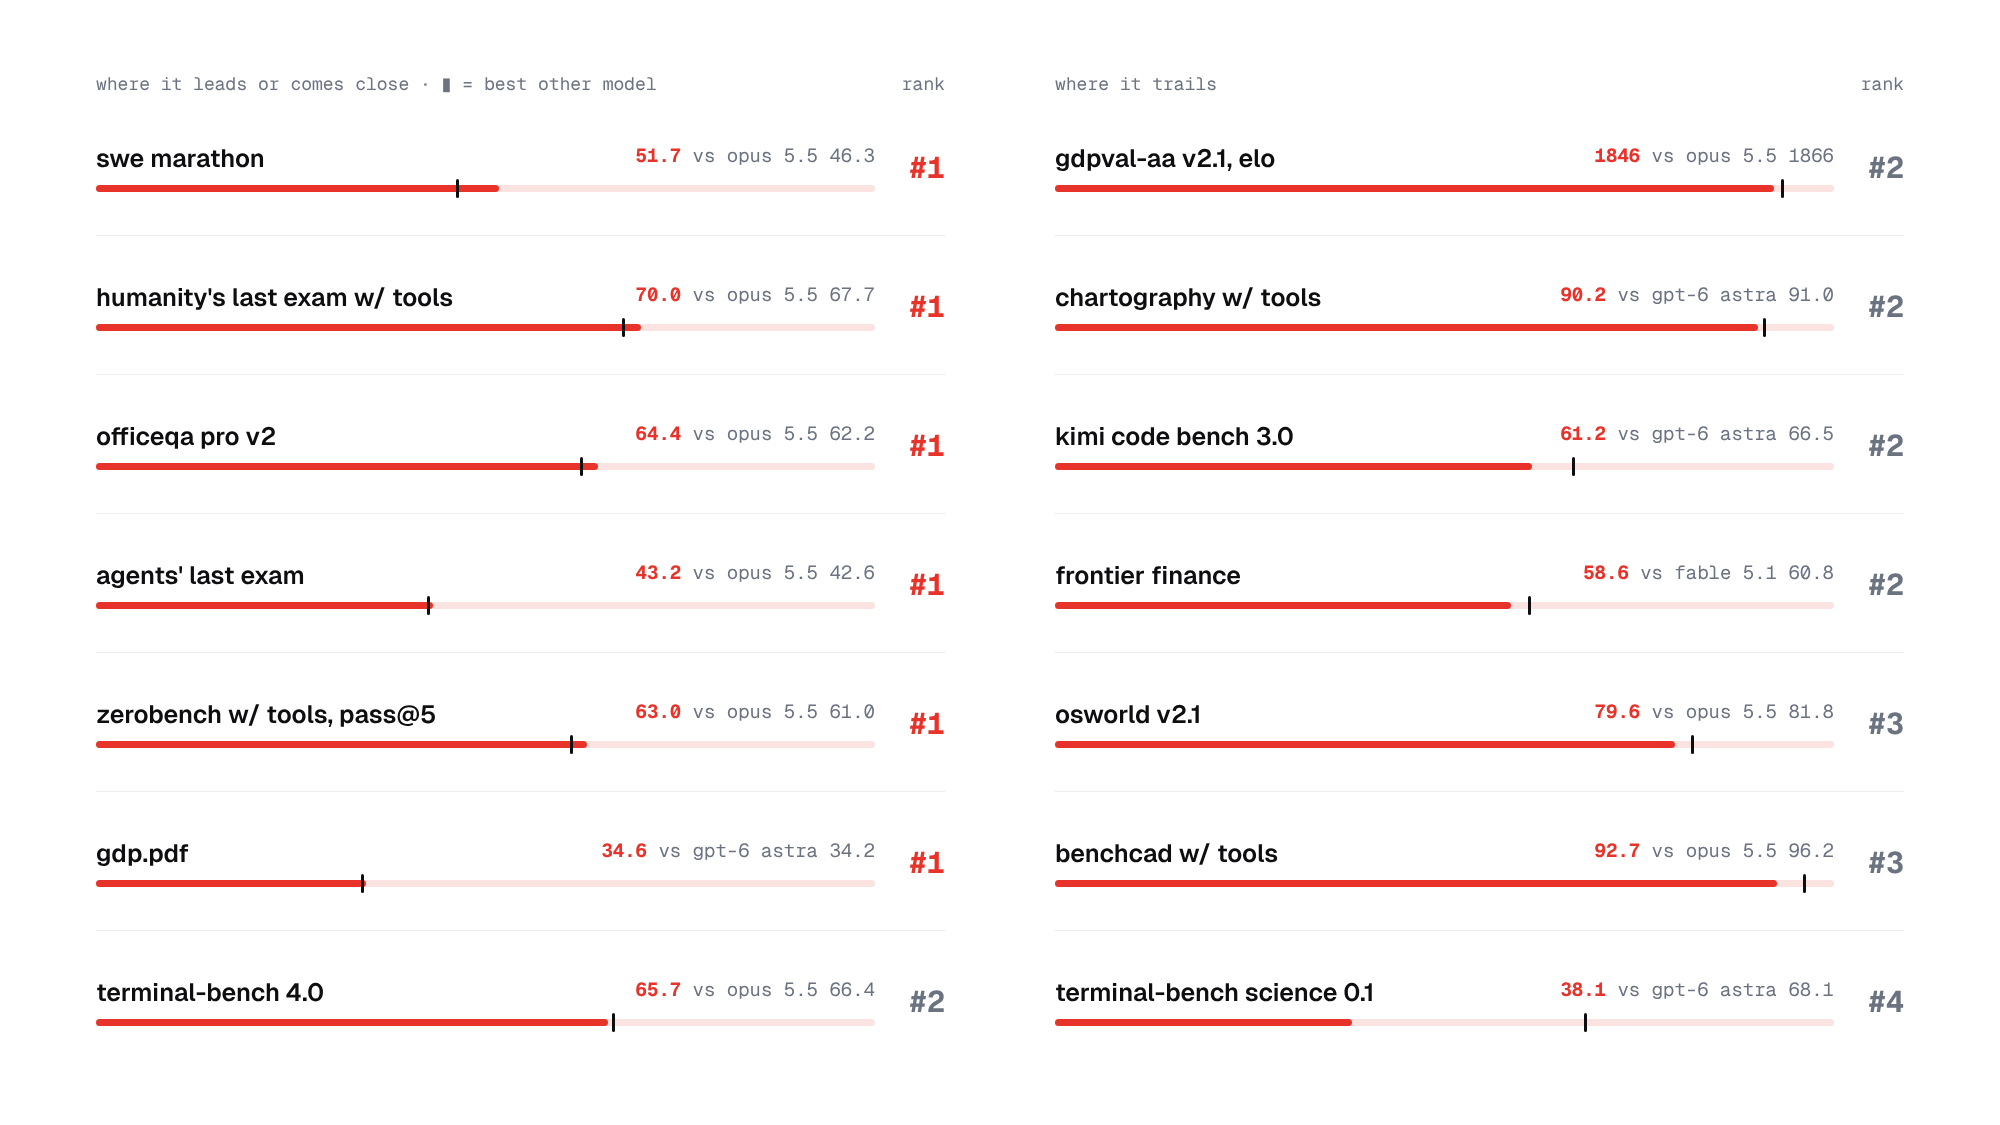
The widest gap is on SWE Marathon, a long-horizon software task, at 5.4 points. On the other five the lead is under 2.5 points.
The finance claim rests on Moonshot's own hallucination test. On Kimi Hallu Bench Hard, the claim-level error rate fell from 23.4% for K3 to 8.3% for K3.1 Pro. That is the 65% drop in the announcement. Moonshot says the test uses prompts built to provoke errors and does not show everyday error rates.
Where it trails
K3.1 Pro is second on five tests in the chart. The closest is Terminal-Bench 4.0: 65.7 against 66.4 for Opus 5.5. It is also second on GDPval-AA v2.1 (1,846 vs 1,866 Elo for Opus 5.5) and Chartography (90.2 vs 91.0 for GPT-6 Astra). Frontier Finance goes to Fable 5.1 at 60.8 against 58.6, and Kimi Code Bench 3.0 to GPT-6 Astra at 66.5 against 61.2.
The largest gap is Terminal-Bench Science 0.1. K3.1 Pro scores 38.1 there and places fourth, while GPT-6 Astra leads at 68.1. It also places third on OSWorld v2.1 (79.6 vs 81.8 for Opus 5.5) and BenchCAD (92.7 vs 96.2).
Kimi Code Bench 3.0 is Moonshot's internal benchmark. On it, K3.1 Pro rose from 55.95 for K3 to 61.2.
Moonshot also reports a deliberate limit on cyber skills. It removed cyber-related data from training for the open-weight release. K3.1 Pro scores 81.0 on its internal XDev-Bench-Hard test, behind the K3 checkpoint without that filtering at 90.5.
What early testers report
First users posted numbers within an hour of the rollout. One tester measured about 100 tokens per second on K3.1 Pro.
The plan limits drew complaints. One Kimi Code session on K3.1 Pro used up the 5-hour limit on 14.8M tokens. Almost all of it, 14.7M, was input that the agent re-read on each step. That session used 3% of the monthly limit. Another user says the $99 Max plan hit the 5-hour cap after 45 minutes on a single prompt.
What is still missing
Moonshot promises the full weights by November 4, 2026. The blog does not name the license yet. K3 shipped under a custom Kimi K3 license, so the terms for K3.1 Pro remain open until the release.
The 14-benchmark chart is Moonshot's own, and independent results are not out yet. K3.1 Pro is also off by default for Kimi Enterprise customers until an admin turns it on.
Sources
- Kimi K3.1 Pro tech blog, Moonshot AI – benchmarks, hallucination test, cyber limits, availability
- Kimi K3.1 Pro announcement, @Kimi_Moonshot on X – October 23, 2026
- Model inference pricing, Kimi API platform – prices as of October 23, 2026