inception launched mercury 3. the diffusion llm runs at 1,068 tokens per second, inception says, and beats gpt-6 luna and claude haiku 5.5. we read the launch post, the models page and the price pages of all three labs. we also checked what independent trackers show on day one.
in inception's own table, mercury 3 is first in 8 of 12 benchmarks. no independent benchmark exists yet. openrouter's live p50 throughput for the model read 383 tokens per second on launch evening.
what inception announced with mercury 3
mercury 3 is the fourth release in the mercury line, after mercury 1 (june 2025), mercury 2 and mercury 2.5. like the earlier models, it is a diffusion model. it drafts a block of tokens and refines them in parallel instead of writing one token at a time. that is where the speed comes from.
inception says mercury 3 has more than 40x the parameters of mercury 1 and runs at the same speed. it also says intelligence on standard benchmarks is 3x that of mercury 1 mini. there is no absolute parameter count and no open weights. co-founder stefano ermon says the limits to scaling diffusion are "compute and data, not fundamental algorithmic barriers."
the specs below come from inception's models page.
- speed: 1,068 tokens per second on nvidia gpus (hardware and batch size not stated)
- context: 1m tokens, up from 260k in mercury 2.5
- price: $0.20 per 1m input and $0.70 per 1m output tokens; cached input $0.02
- launch price: 50% off – $0.10 / $0.35, cached input $0.01; no end date is given
- access: inception's api (
mercury-3, openai api compatible, 100m free tokens for new accounts), openrouter, baseten and vercel
mercury 2 and 2.5 are closed to new users from oct 19. existing customers keep access until nov 15, 2026. enterprise contracts continue.
mercury 3 benchmarks: what inception has published
the launch post carries one benchmark table. it compares mercury 3, gpt-6 luna and claude haiku 5.5, all at medium settings, as run or compiled by inception.
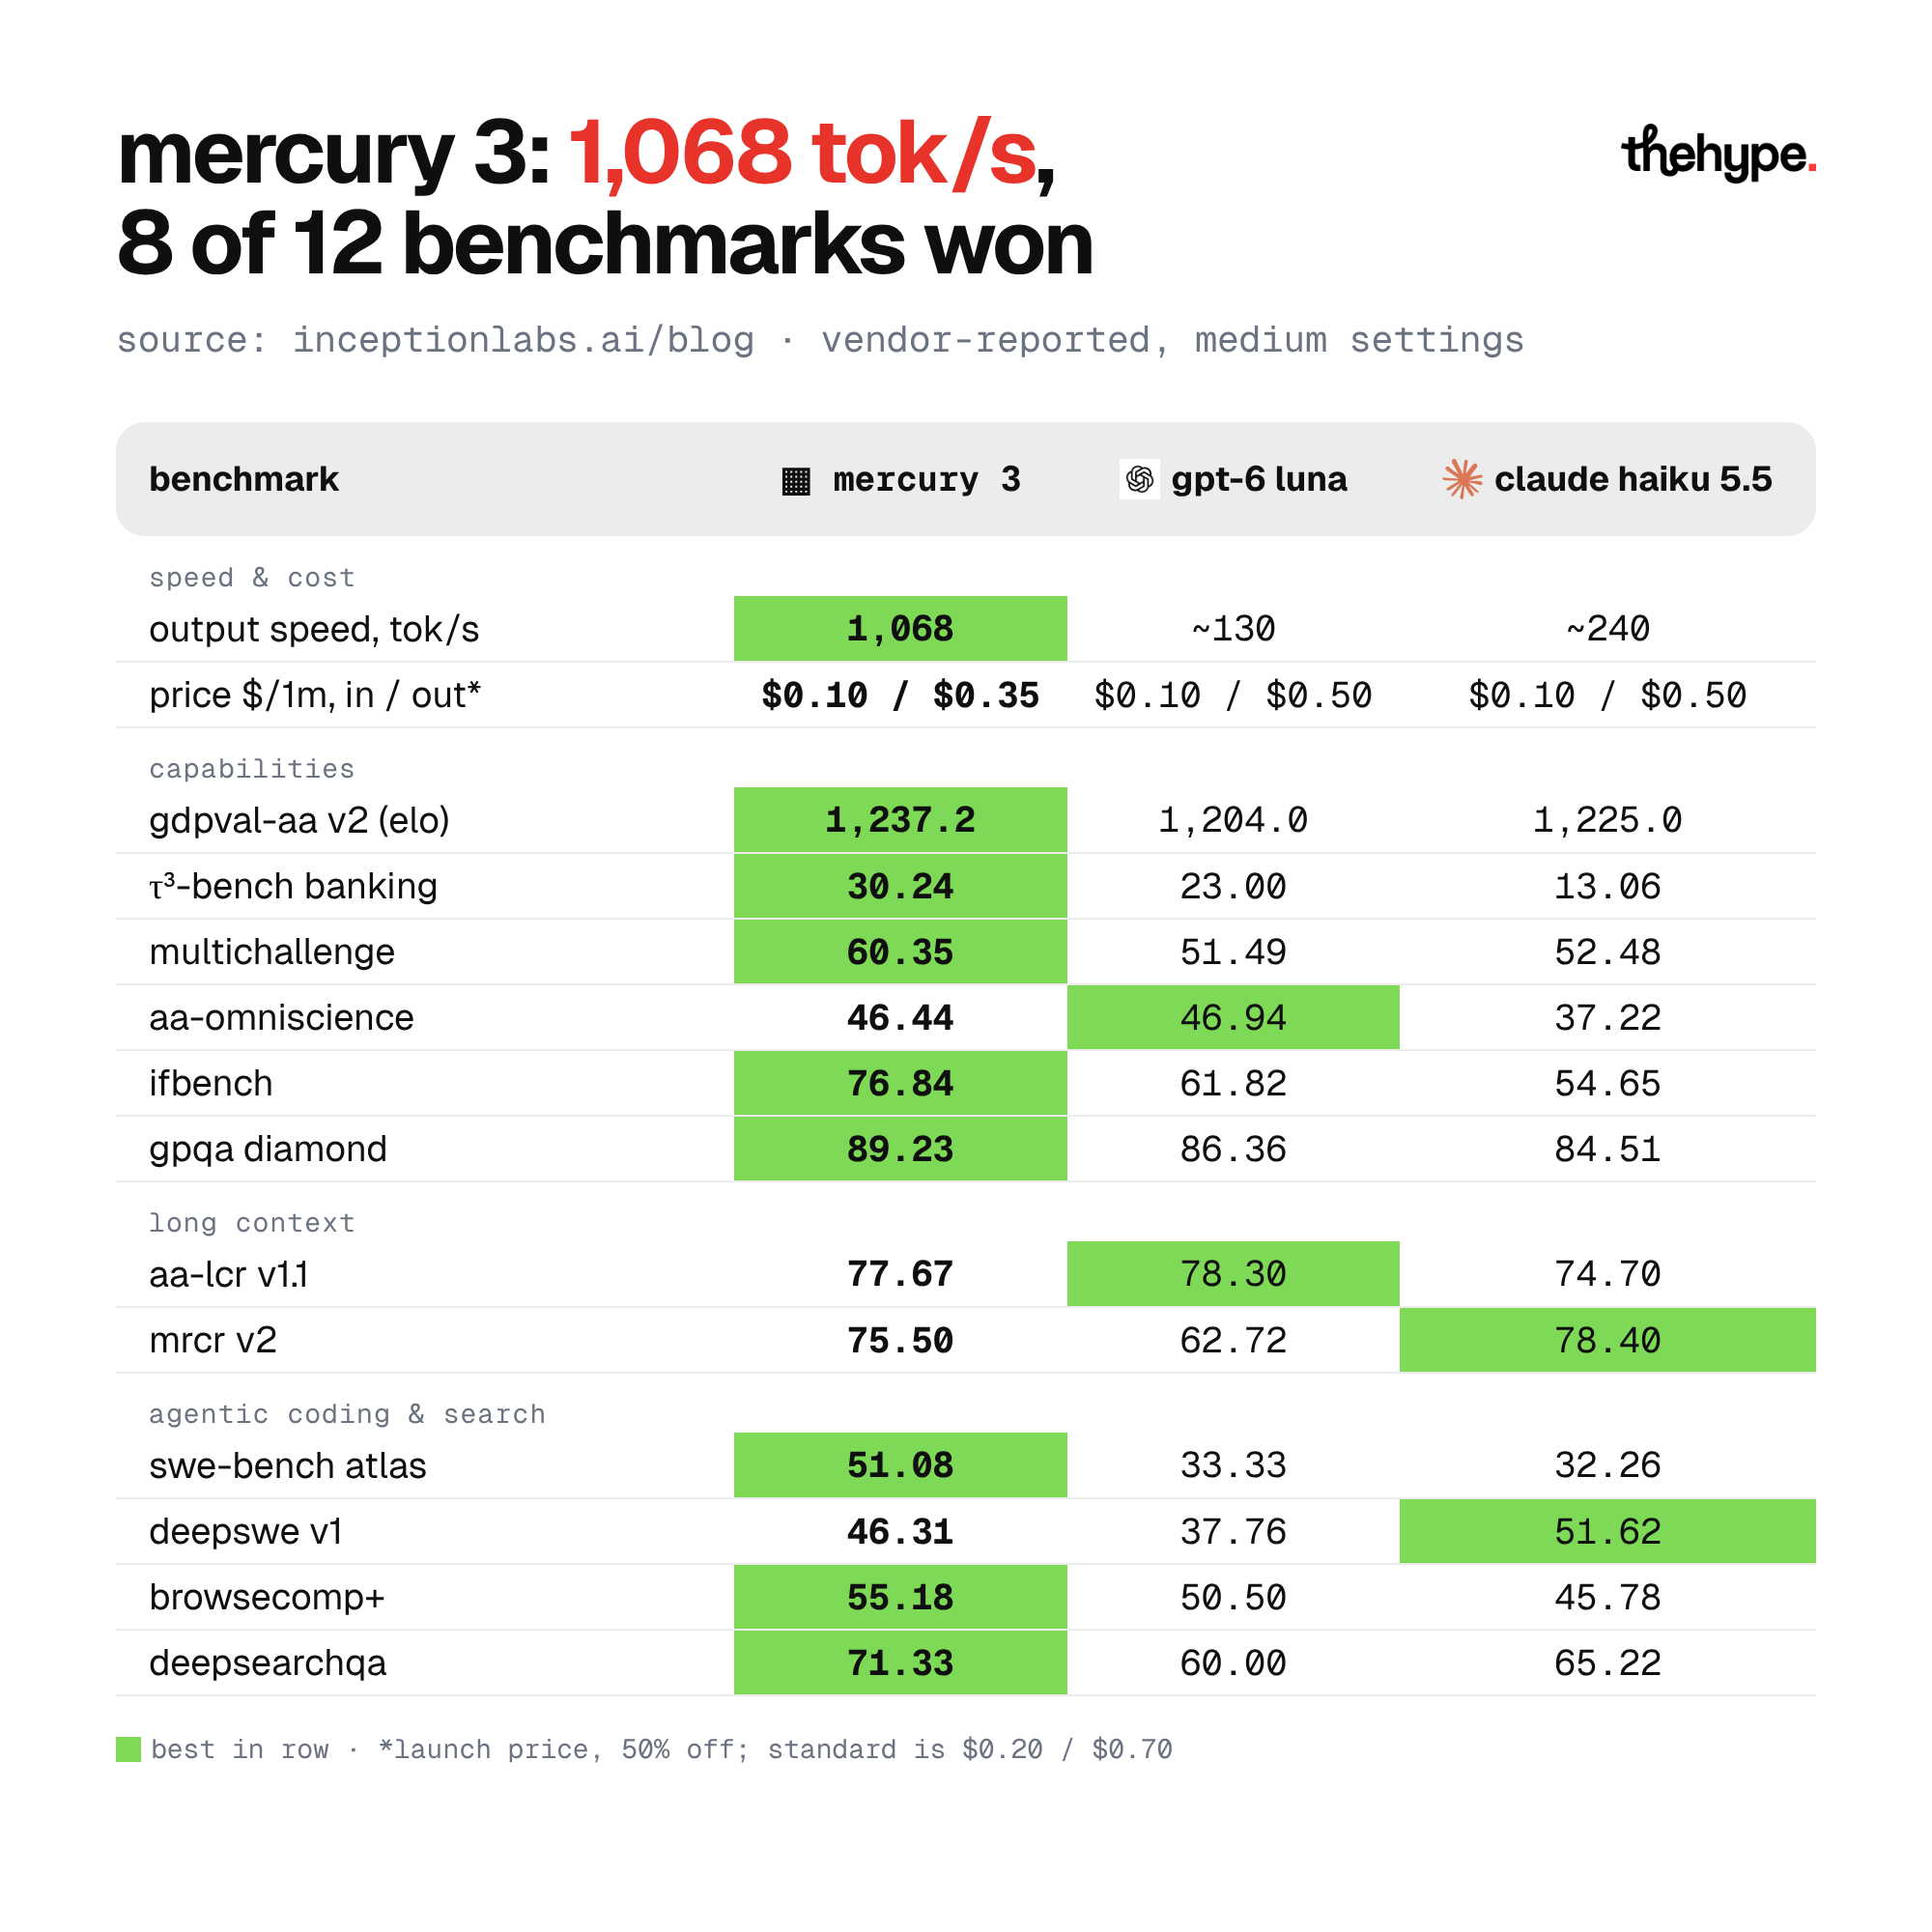
mercury 3 leads 8 of the 12 tests. luna leads aa-omniscience and aa-lcr. haiku 5.5 leads mrcr v2 and deepswe. the biggest gap is on swe-bench atlas: 51.08 against 33.33 and 32.26. the post does not say how many runs each score averages or which harness was used.
what early customers report
the rest of the evidence comes from early-access customers. none of it is an independent test.
tinyfish says mercury 3 completed 25 of 50 live mind2web navigation tasks. the run used inception's own web-agent harness. tinyfish says that is more than gpt-6.1-sol, but gives no score for it. octen measured a median generation time of 0.9 seconds and a median end-to-end response of 2.2 seconds in its search api. revisiondojo says hints and marked answers come back in about a second.
mercury 3 speed: what independent trackers show
artificial analysis has not listed mercury 3 yet. its inception page still covers mercury 2.5 – intelligence index 12, output speed 706 tokens per second. mercury 2 sits at index 11.
openrouter serves mercury 3 from one provider, inception. on the evening of oct 19, its model page showed a p50 throughput of 383 tokens per second. p50 latency was 19.44 seconds. its comparison page showed a median of 219 tokens per second. these are first-day readings on live traffic, not a controlled test, and they change by the hour. both sit well below 1,068.
mercury 3 pricing vs gpt-6 luna and claude haiku 5.5
at launch prices, mercury 3 is the cheapest of the three on output. at its standard price, short prompts cost more than on luna or haiku 5.5. on prompts above 100k tokens, it stays below haiku 5.5's long-prompt rate at either price.
what is still missing
three things are not public yet. there is no independent intelligence score and no throughput figure measured outside inception's own stack. the end date of the launch discount is not given either. existing mercury 2 and 2.5 users have until nov 15 to move.