 Nick Trenkler

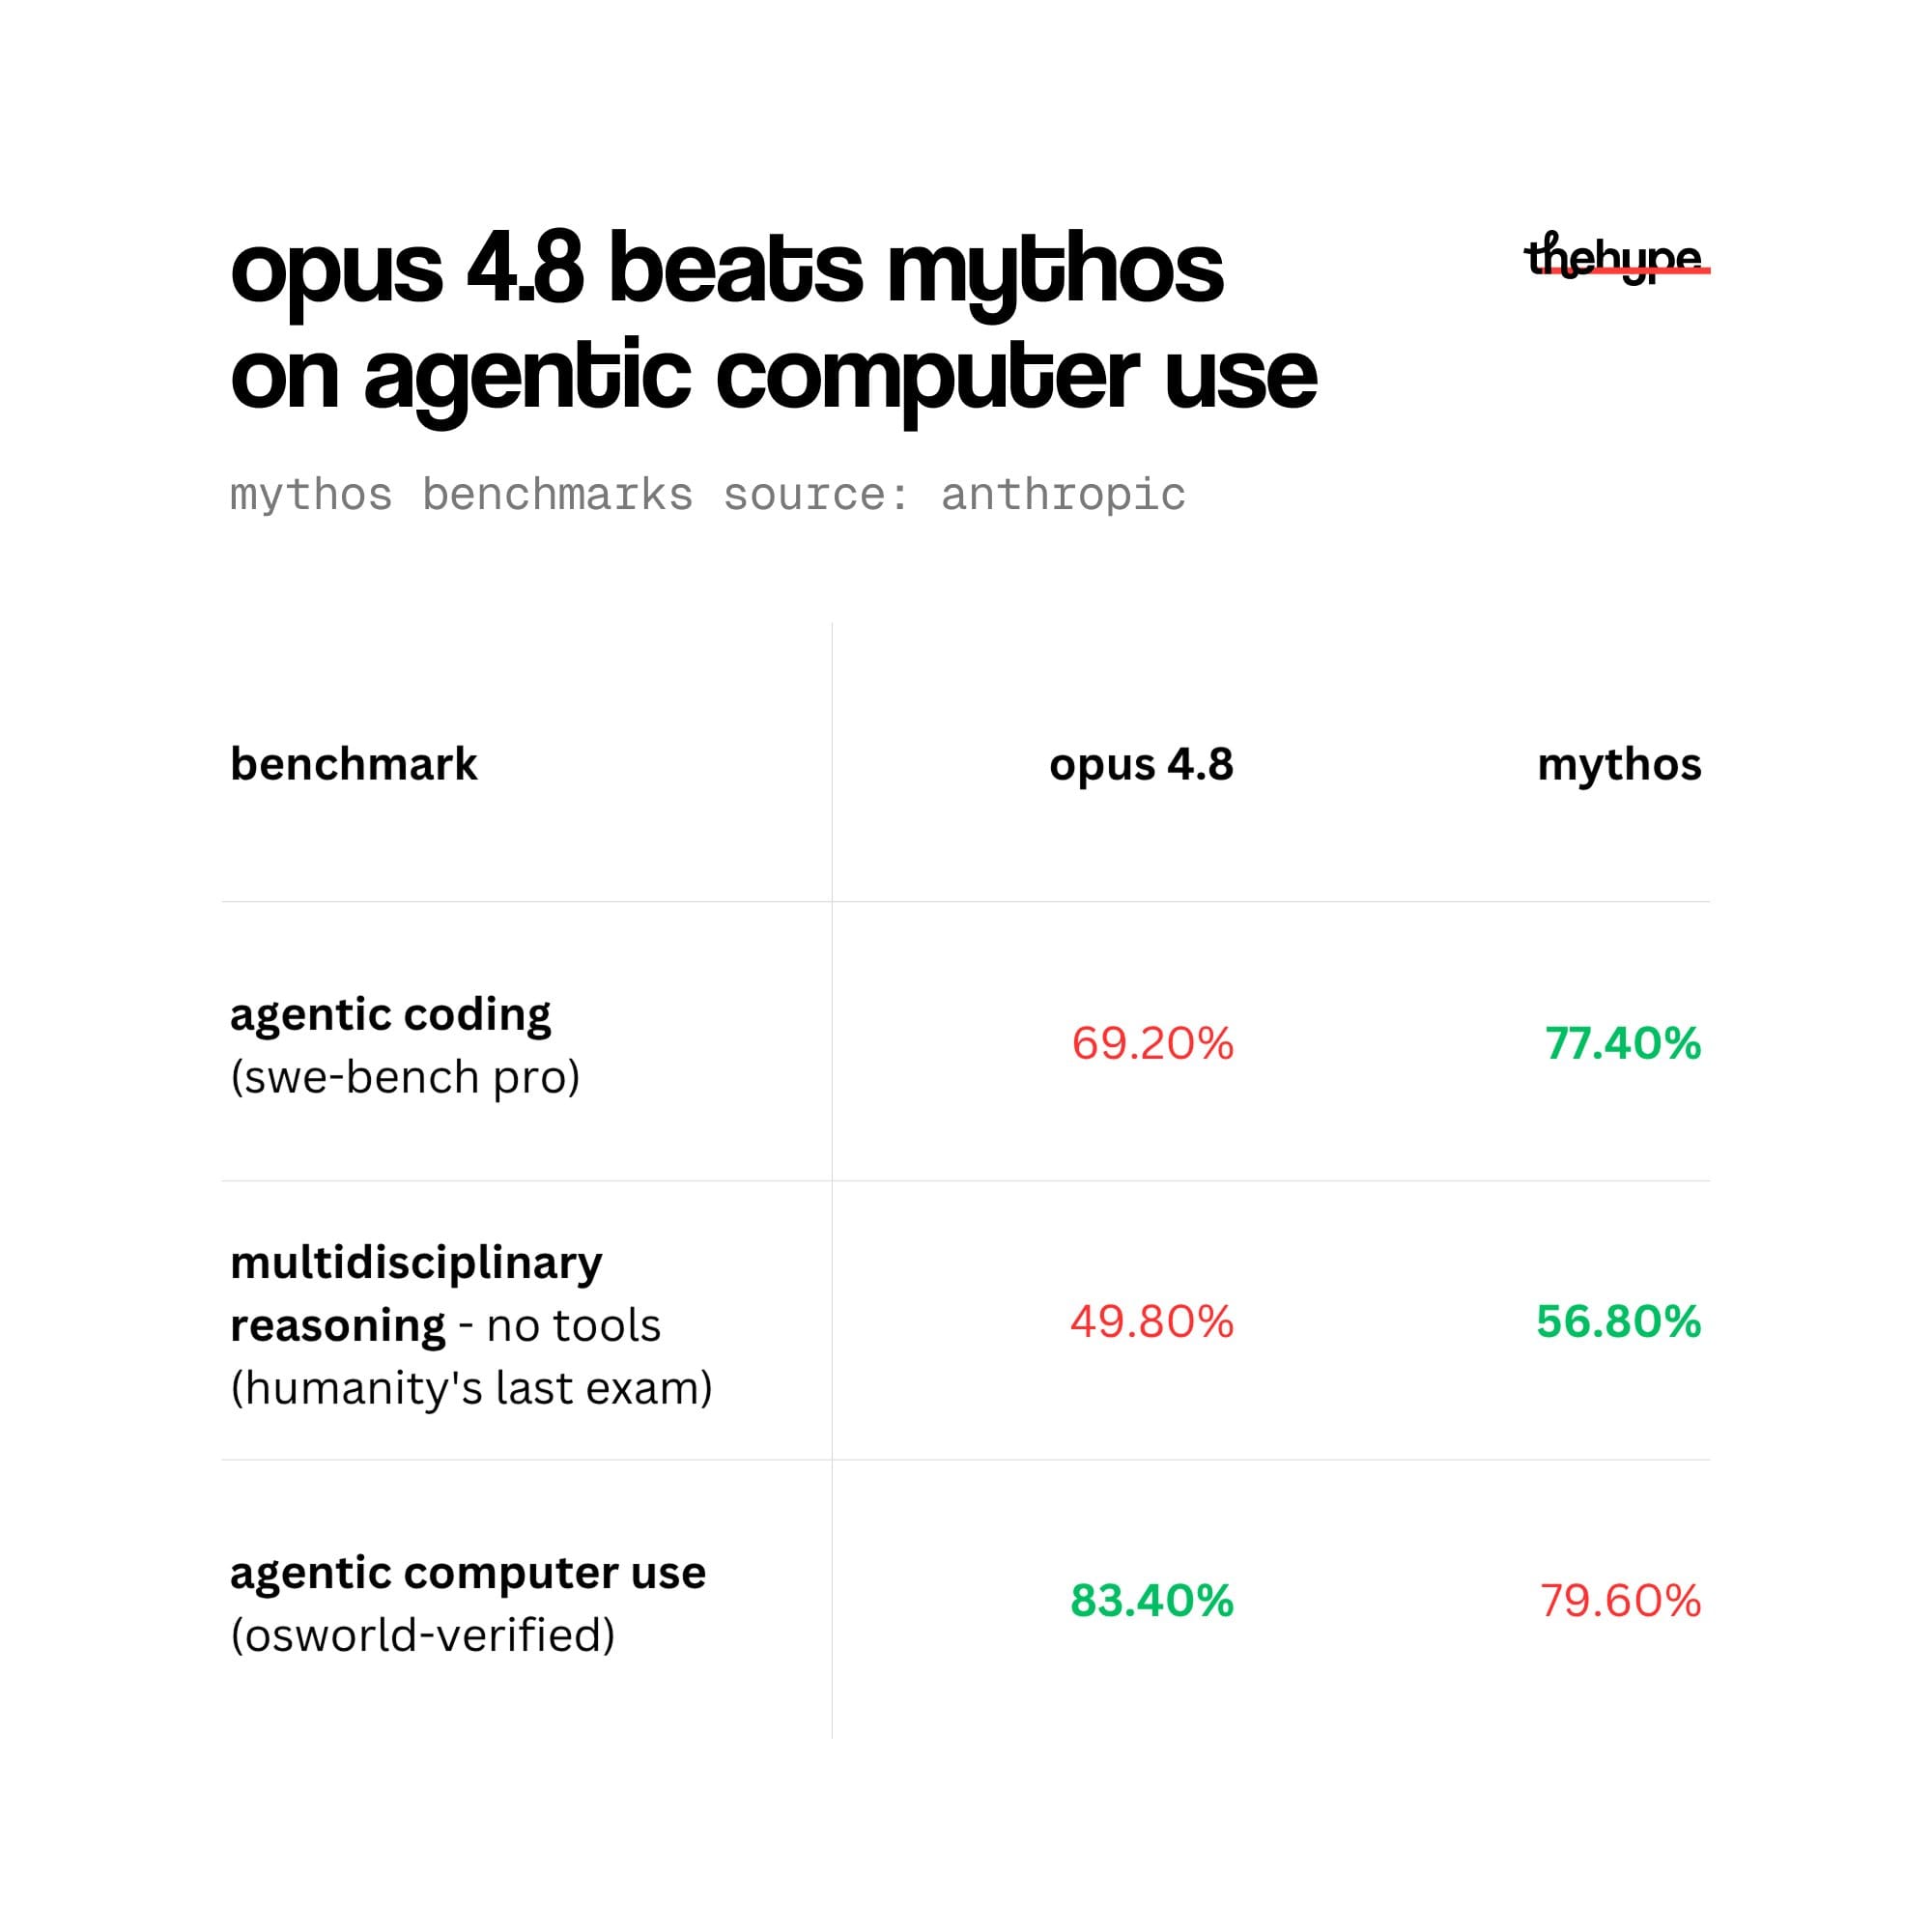
OSWorld-Verified bench tests AI on real computer tasks – opening apps, filling forms, navigating browsers. Each task is pass/fail. The % is simply how many tasks the model completed successfully out of the total
83.4% vs 79.6% – a nearly 4% gap on pass/fail tasks isn't noise. It's a pattern
Public models are closing the gap faster than anyone expected. If Anthropic doesn't open Mythos to the mass market soon, the window closes
And according to the Opus 4.8 release notes – it already is. Mythos goes public in weeks
Introducing Claude Opus 4.8: it builds on Opus 4.7 with sharper judgment, more honesty about its own progress, and the ability to work independently for longer than its predecessors.
— Claude (@claudeai) May 28, 2026
Available today at the same price. pic.twitter.com/EufxL7T1kb