 Nick Trenkler

Google keeps shrinking their open models
Just released new versions of their Gemma 4 AI models yesterday, optimized using a technique called quantization-aware training (QAT)
How is QAT different from normal compression?
Normal compression (PTQ) quantizes the model after training – which often hurts performance. QAT bakes quantization into the training process itself, so the model learns to stay accurate even at smaller sizes.
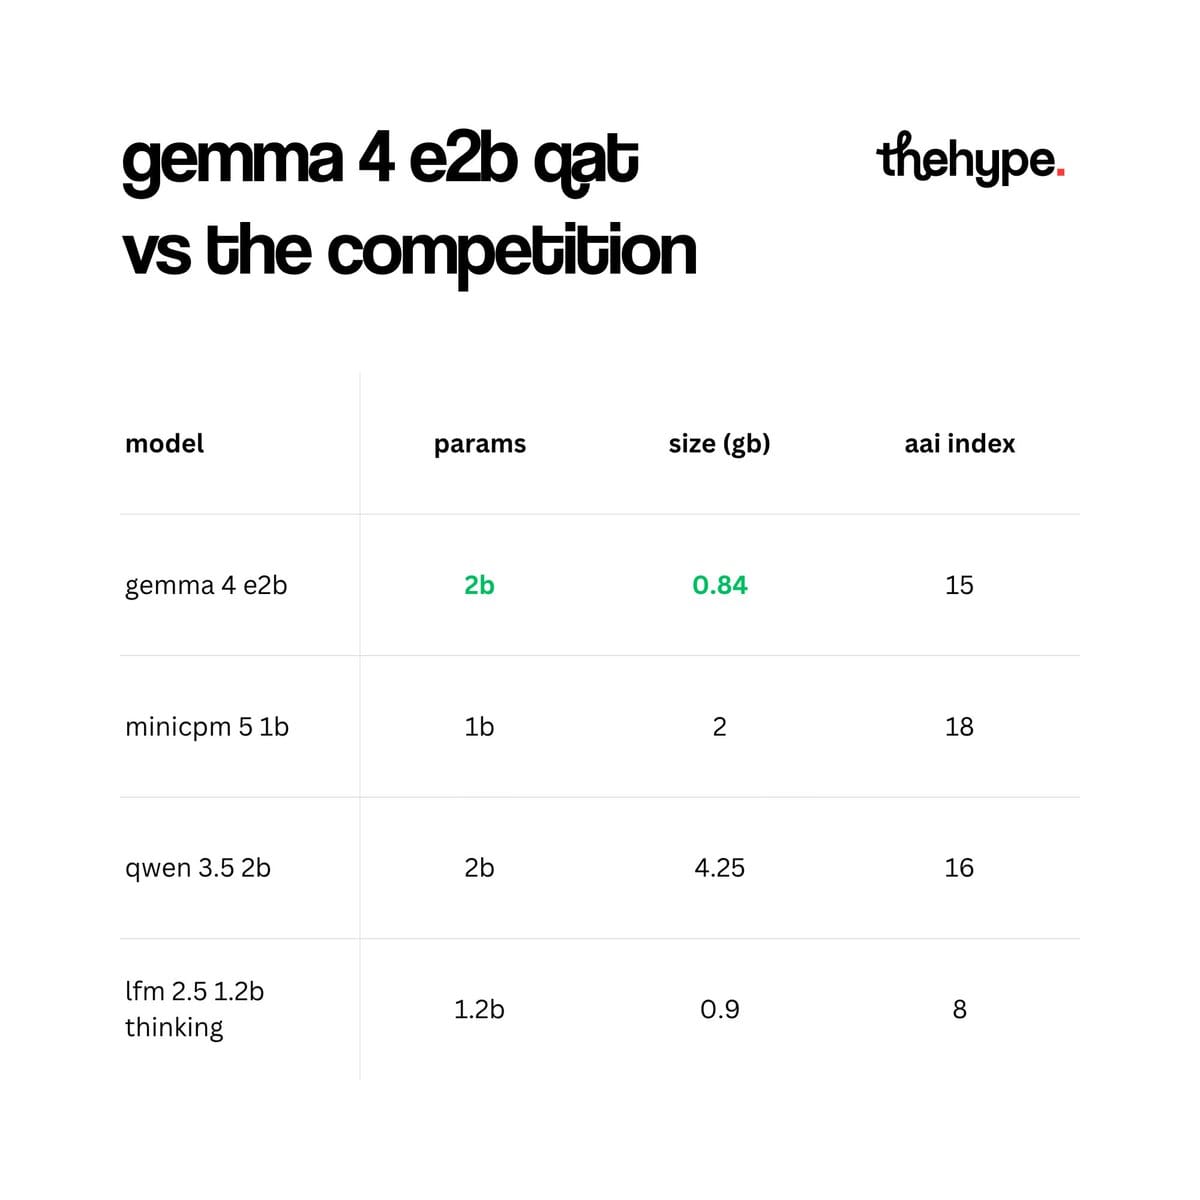
The smallest model, Gemma 4 E2B, has been squeezed down to 0.84 GB of memory in text-only mode. What's its normal size?
• Full size Gemma 4 E2B (bf16): 11.4 GB
• Quantized Gemma 4 E2B (q4_0 / 4-bit): 2.9 GB
• Mobile version (QAT): 1.1 GB
• Mobile text-only version (QAT): 0.84 GB
That's roughly a 91% reduction
What they did to get there:
- Pre-calculated activation scaling instead of doing it on the fly
- Structured data to fit mobile chip architecture natively
- Compressed token generation layers to 2-bit while keeping reasoning layers higher precision
- Optimized the vocabulary and short-term memory (KV cache) to allow longer conversations in less RAM
At 0.84 GB, Gemma 4 E2B QAT is now the most lightweight model in its class. But here's the interesting part – QAT is a technique, not a Gemma exclusive. Apply it to something like MiniCPM 5 1B (currently 2 GB) and you could shrink it even further